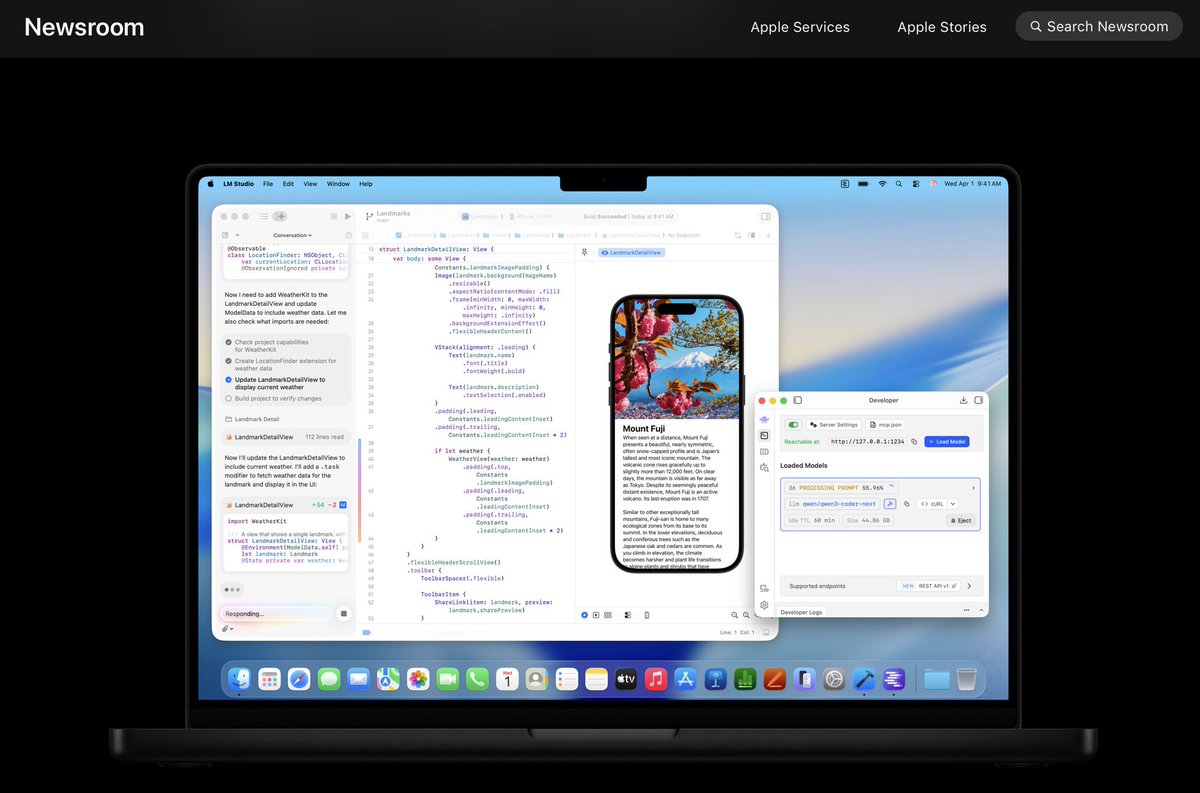
So excited to share that @adrgrondin and @LocallyAIApp are joining LM Studio family!
Together we are doubling down on Apple platforms to bring you delightful AI experiences across devices.
Adrien was able to build a tasteful and much loved app over nights and weekends, and have been crushing it on twitter as well. Could not be more excited to join forces and build the future together.
Welcome to the team, Adrien!
I’m excited to announce that I’ve joined @lmstudio 👾
The team behind the app is amazing and I couldn’t be more proud.
I’ll still be working on Locally AI, now full-time, to bring the best experience possible.
Today, we’re excited to announce that we’re joining @lmstudio!
We share a common vision of building amazing products for everyone and making local models more accessible.
We’re combining our efforts to bring you the best experience possible.
Locally AI is joining LM Studio!
We are beyond excited to welcome @adrgrondin and @LocallyAIApp to the LM family.
Together we are doubling down on native AI experiences across your devices, anywhere you go.
Read our announcement https://t.co/Yzcnr8EEP0
@mikewazar@lmstudio@GoogleDeepMind Thanks for reporting - We've just released new v2.11.0 llama.cpp engines with a candidate fix - would you be able to retry with this updated engine and let us know how it goes?
@AdamLangePL@lmstudio@GoogleDeepMind Thanks for reporting - We've just released new v2.11.0 llama.cpp engines with a candidate fix - would you be able to retry with this updated engine and let us know how it goes?
Nemotron 3 Super by @nvidia is now live in LM Studio!
🦾 Open-weight 120B MoE, 12B active params
📜 Supports up to 1M tokens context window
Requires about ~83GB to run locally 🚀
https://t.co/5v6WKnnUra
One of the coolest uses of @lmstudio and @AIatAMD is using LM Link to have a Framework Desktop be a remote inference server for a laptop, including something little like Framework Laptop 12. It feels native on the laptop, but gets the desktop’s performance.
Introducing LM Link ✨ Connect to remote instances of LM Studio, securely.
🔐 End-to-end encrypted
📡 Load models locally, use them on the go
🖥️ Use local devices, LLM rigs, or cloud VMs
Launching in partnership with @Tailscale
Try it now: https://t.co/Vl2vr6HlF5
Introducing Parallel Requests for MLX!
Multiple requests to the same model can now be processed simultaneously ✨🚄⚡️
Works both in the API and in Split View chats.
See it in action 👇🕺
Introducing LM Studio 0.4.0 🎉✨
It's the next generation of LM Studio.
🪄 Deploy on servers, in CI, or anywhere
🚄 Parallel requests for high throughput use cases
🔨 New stateful REST API: use local MCPs
🎨 Complete UI revamp
See what's new in this release👇🧵
LM Studio is excited to partner up with @OpenAIDevs to support Open Responses for local models.
In this update:
- 🔧 Open Responses /v1/responses endpoint
- 🔮 Logprobs for candidate tokens in API responses
- 📊 Rich stats about the prompt cache state
Please update to 0.3.39 first!
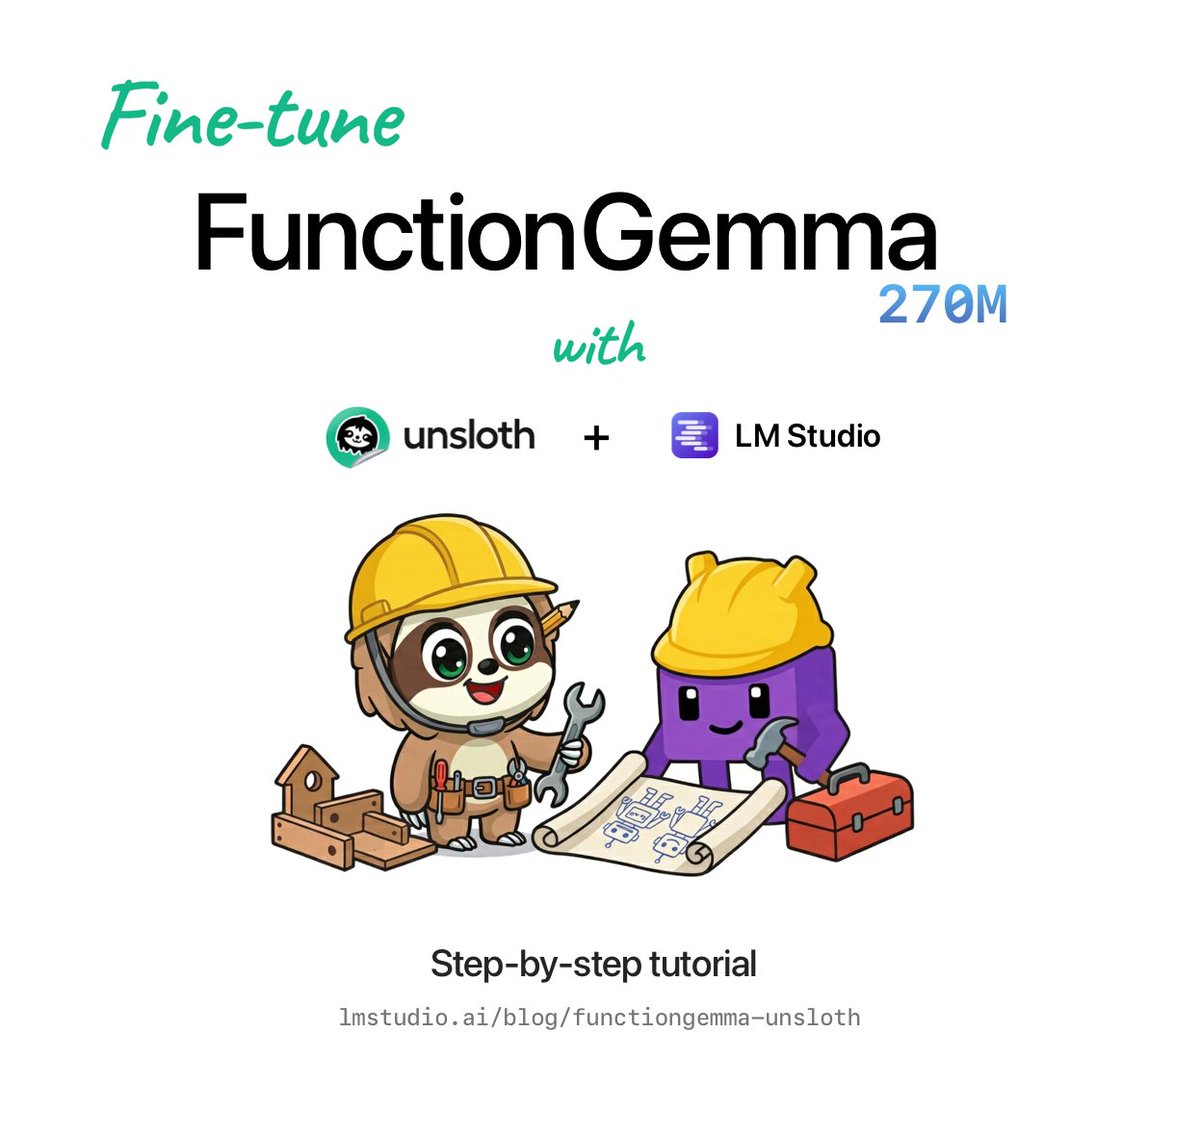
We worked with @UnslothAI on a new beginner's guide:
How to fine-tune FunctionGemma and run it locally!
🔧 Train FunctionGemma for custom tool calls
✨ Convert it to GGUF + import into LM Studio
👾 Serve it locally and use it in your code!
Step-by-step notebook: https://t.co/JkRxBlorvy
Blog post: https://t.co/PiqcOdDbCC