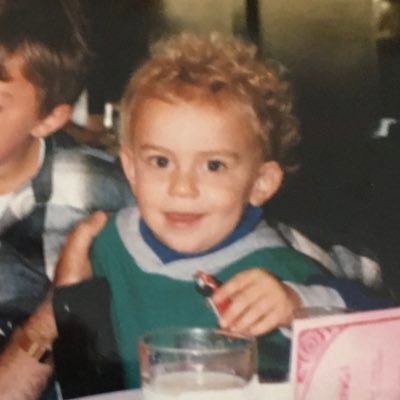
1/ After 5 years, I’m proud to share that @ColumnTax has found a new home.
We’ve been acquired by @AiwynAI.
I couldn’t be more sure this is the right move for our business, tech, and team.
These pics are the moments we started & sold the company:
I haven't seen this before: GPT-6.2 Sol scores worse than 6.1 on TaxCalcBench - for kind of a weird reason:
6.2 Sol seems to be too skeptical of the inputs: it refuses to take certain deductions, calling them "unsubstantiated"
GPT-6.2 Sol—an efficient and versatile model for everyday work.
It powers through multistep agentic workflows, writes clearly and naturally, and is intuitive to collaborate with.
Many OpenAI employees use GPT-6.2 Sol as their go-to model across technical and non-technical work.
Benchmark design & QA is really hard, and no one really talks about how much it really costs (time & money)
Here are the numbers on what I've spent making sure that TaxCalcBench is near perfect...
$21,631 total, broken down into:
- $16,537 on benchmark runs via APIs
- $5,094 in agent work (API equivalent pricing, but paid via subscription)
835 hours building the benchmark and fixing bugs:
- 466 human hours building the test cases, building the harness, writing the research paper, and fixing bugs
- 369 hours of agent (Claude Code & Codex) time
This type of cost makes it hard for independent researchers from building high-quality benchmarks.
A couple things contributed to my ability to find bugs:
1) the benchmark is open source so random folks online contributed issues & PRs
2) the Data, Research, and QA teams at the frontier labs
I made a sort of unhinged benchmark I'm calling "MichaelBench"
Every time I use AI to do a task on my computer, I rate if it was done correctly 👍/👎 (using a custom Mac app)
MichaelBench tracks which models (at which thinking levels) I think are doing my actual work well:
@epichrisis yeah, exactly - this isn't statistically rigorous at all, just for fun :)
atm, my personal (easy) usage skews toward Chat and engineering taks toward Claude, hence why 6.1 Sol is on top
@kale_panoho@henrytdowling yeah, i guess we'll see 🤷♂️
if i had to bet, I would bet on BigModel generalizing > small model with very specialized task training, though
@henrytdowling@kale_panoho agree:
> build a model that outperforms frontier labs" is a tough one
what evidence do we have of specialized small models outperforming NextBigModel for very long?