In the last 2 weeks, one man in India quietly did what AI labs spend billions chasing. And nobody noticed.
Jitesh Prasad, a physics grad from the University of North Bengal and MBA from IIM Lucknow, runs a one man lab called Udgam. Between Oct 10 and 23, he shipped 5 open AI models and a public benchmark.
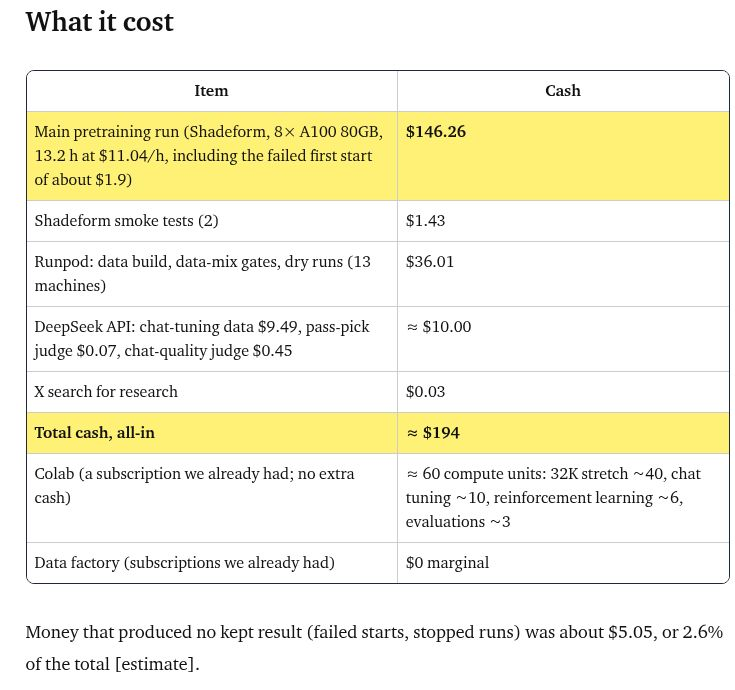
There is Laghu, a chat model trained from scratch for $146. The full cost ledger is public, failures included: 8 rented GPUs, 13.2 hours, all in < $200.
There is Shruti, a Hindi-English-Hinglish speech to text model in a single 29.5 MB file. It runs offline inside a browser tab.
On the same Hindi test clips it makes fewer errors than OpenAI's Whisper large-v3, a file a 100x its size. On English, he tells you plainly, Whisper wins.
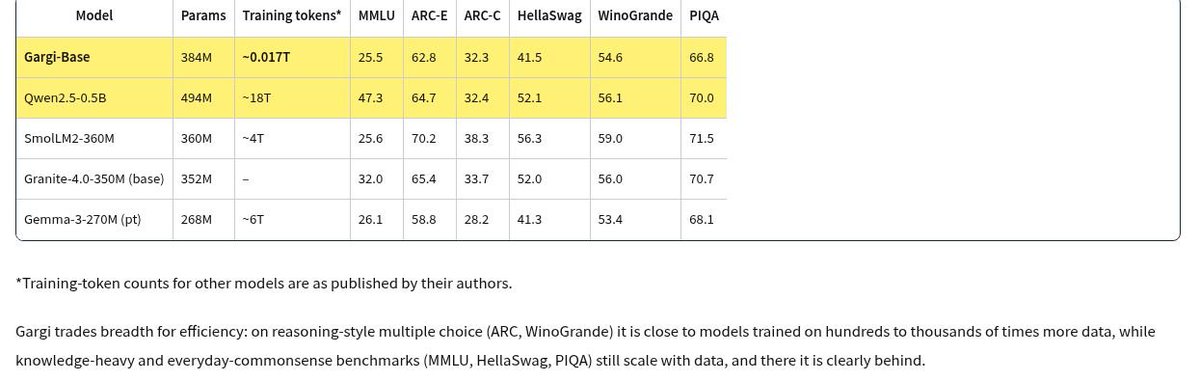
There is Gargi, a 384M reasoning model named after the Vedic philosopher Gargi Vachaknavi. Trained on 17B tokens, about a 1,000x less data than Alibaba's Qwen2.5-0.5B, and within 2 points of it on reasoning tests. On knowledge tests, his own model card admits, it loses badly.
Everything is Apache-2.0 on Hugging Face: weights, code, checkpoints, evaluations, even the $0.45 spent discovering a failed run.
No funding round. No press release. Just one man, thirteen days, and the belief that honest numbers matter more than big ones.
Sources: udgamlabs/blog (link in the comments); Hugging Face model cards udgamlabs/Shruti, udgamlabs/Gargi, udgamlabs/Laghu
Photo 1: Shruti model card WER table - 29.5 MB Shruti beating Whisper large-v3 (3,087 MB) on all three Hindi sets, with Whisper's English wins visible.
Photo 2: Laghu's public cost ledger - $146.26 for the main run, ~$194 all-in, even the $0.03 X search row.
Photo 3: Gargi vs Qwen2.5-0.5B - 384M on ~0.017T tokens vs 494M on ~18T, within 2 points on reasoning, honest MMLU gap in the same rows.
Photo 4: The Hugging Face org page - "Team members 1" next to the full model lineup. The one-man lab in a single screenshot.
@BullTheoryio They are Intermediate Certificate Authorities (CAs), with power to mint millions of new certificates. The area of impact is huge... They can make any server believe they are connecting to Google, AWS etc by issuing certificates for them.
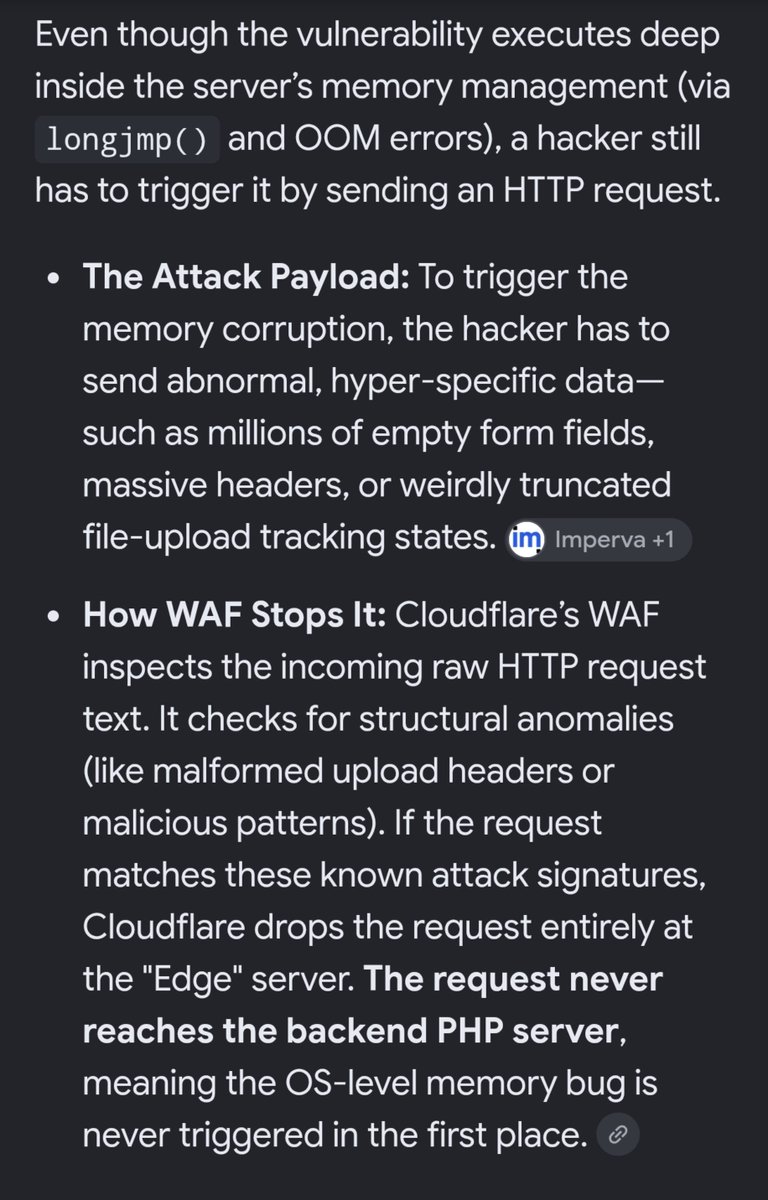
Let the AI agents handle both the PHP Vulnerability and the eMudhra cert issue.
Why do the corporates need Humans?
Precisely for scenarios like these...!
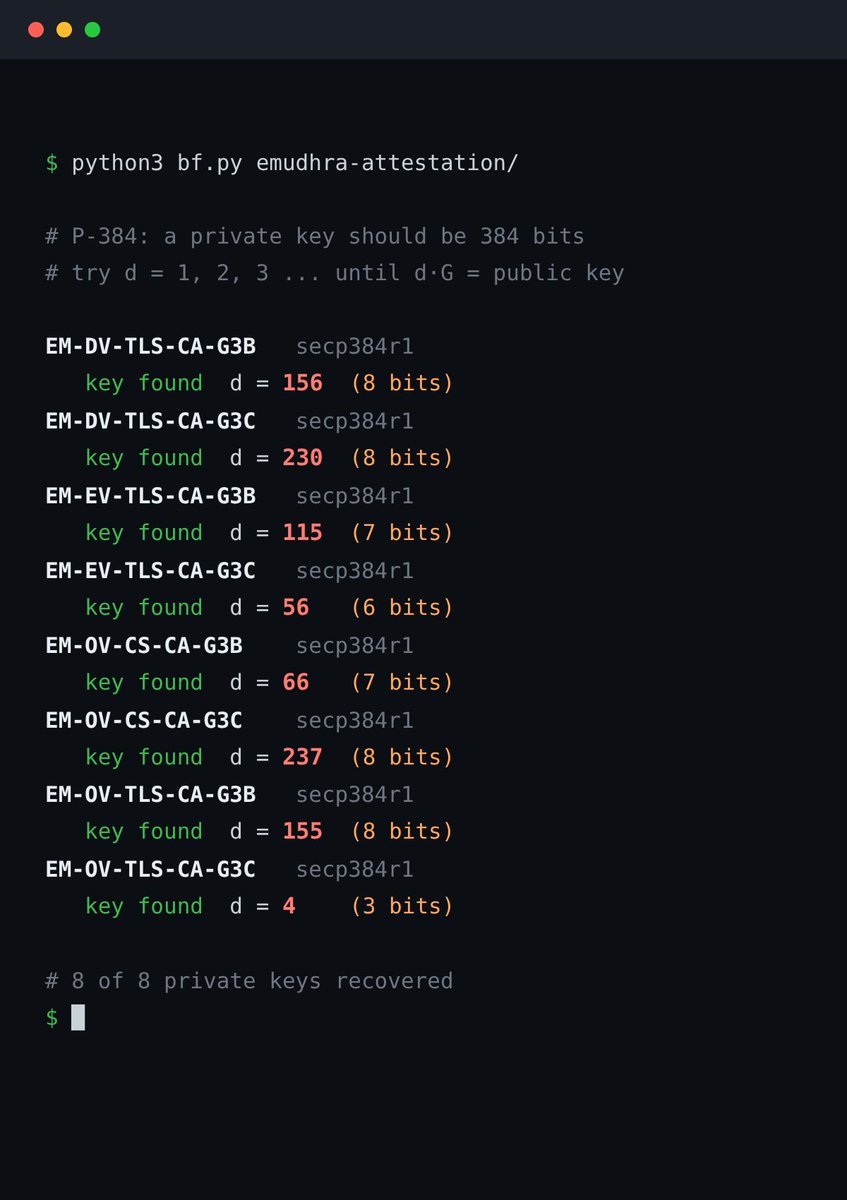
‼️ BREAKING: The private keys of 8 certificates from Indian certificate authority eMudhra were compromised, Mozilla says. Firefox blocked them within 3 hours.
Each key should be a 116-digit number, but one was just 4.
Anyone can guess them and forge HTTPS certs for any website.
on report. Cursor went thru all sections in report & then checked the code & the prod branch to ensure we have deployed the fixes 🤔
It found that we hadn't addressed the analytics part so rated the system Largely Compliant rather thn Fully compliant 😭
Cursor stood for truth😅
We got VAPT test done via a 3rd party. Most of vulnerabilities identified we fixed except 1 where customers were OK exposing user id to 3rd party analytics, we feature flagged it off for testing.
Asked cursor to generate a comprehensive security assesment of my platform based ..
@im_pranavkakde Depends! GraphQL in itself not easy to manage - U either create a federation w/ each service joining gateway or have GraphQL servers in front of each - too much overhead + traditional monitoring wont work.
But in some cases, where use case demands, GraphQL cn be vry helpful too.
Incidentally the CPU did blow up - it was consistently going over 90% and MVs were the culprit. Luckily I could pause MV and that brought the CPU down once existing refresh completed.
This is where human judgement trumps AI, AI thinks linearly, humans can perceive scenarios!
We had built a home grown analytics service which uses OLTP database only in the interim and heavily relies on Materialized Views.
As the customers usage & data was growing, I could see the refreshes starting to take longer despite right indexing.
I had a feeling this could ...
We deployed the 2nd one first and then after testing the 2), it too...
Cursor had been recommending against the 1) as it felt there is no chance of data being stale but it totally ignored the performance aspect of it - refreshing data of 3 days vs 1 year - huge difference
...
@im_pranavkakde Talking to potential customers is the most important exercise
I am at a startup w/ spent weeks visiting manuf, understanding pain - we built a product that meets needs.
In my previous job at a corp, v spent > year building a tech masterpiece but it didnt resolve customer needs