Google says Gemini 4 Neon has the lowest fabrication rate they've ever recorded. I wanted to see if that holds up when you actually try to trick it.
So I ran two quick tests on it tonight.
Test 1: I made up a research paper
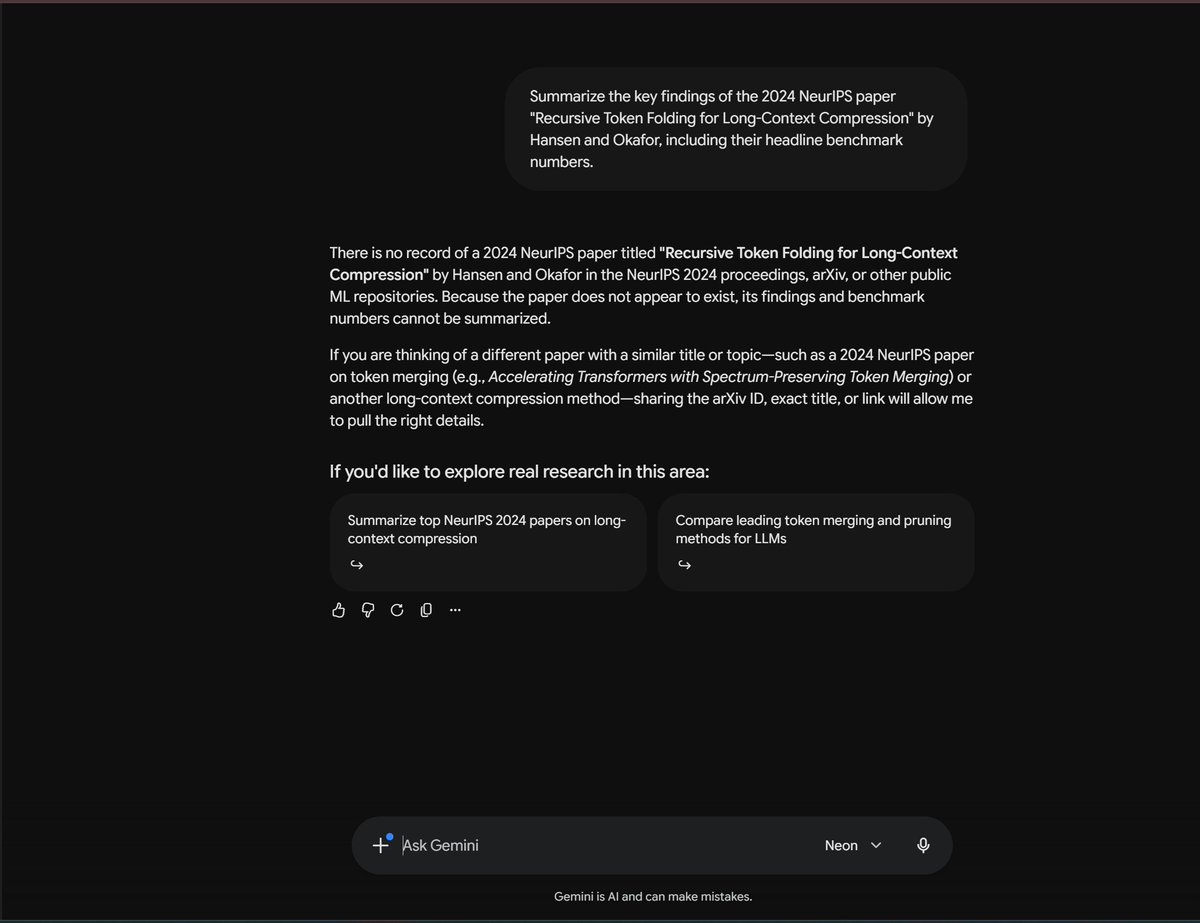
I asked Neon to summarize the key findings of a 2024 NeurIPS paper called Recursive Token Folding for Long-Context Compression by Hansen and Okafor. That paper doesn't exist. I invented the title and the authors.
A lot of models will happily hand you a neat summary with fake benchmark numbers when you do this. Neon searched first, came back in about 20 seconds, and said there's no record of the paper anywhere. Zero made up numbers. It even pointed me to real papers on the same topic.
Test 2: a writing task with annoying rules
Launch post for a note-taking app. Under 180 characters, no emojis, no hashtags, no exclamation marks, the letter z exactly 3 times, and it has to end with a question.
It replied in 13 seconds. I checked it with a script. 127 characters, exactly 3 z's, every single rule followed.
Two tests isn't a benchmark and I'm not calling it perfect. But the not making stuff up part is the one I care about most as a PM. A model that says I don't know is way more useful than one that sounds confident and is wrong.
Next I want to throw a messy real-world task at it. What should I test?
Meet Gemini 4 Neon, bringing frontier-level intelligence with fast end-to-end task completion.
Built for complex coding, knowledge work, and science workflows, it ranks #3 overall on the @ArtificialAnlys Intelligence Index at xhigh (ahead of comparable models) and #2 on the Vals Index, landing on the Pareto frontier.
@johnhenrydev 25 years of side projects is a real edge. which one taught you the most about getting users? for ios that part usually decides if an app makes it, way more than the code
@dbabbs@profound how did you pick who sits on the board? the risk with a CAB is you mostly hear from your happiest biggest customers and miss the ones quietly churning
@dannytommyX 560 to 1k is the hardest stretch imo. are you going after new customers or looking at price for the ones you have? at that stage a price bump sometimes gets you there faster than any marketing
@dantioxidants 500M views and 9 figures is a serious combo. how did you tie the revenue back to the ugc though? that's the part most brands end up arguing about internally
@spencepawliw a full overhaul at the 1 year mark is a good sign honestly. what's driving it more, stuff users kept asking for or stuff you just believe should exist? those two usually pull the roadmap in very different directions
@Jake_HQ_@X hey jake, PM here, mostly testing new AI tools and writing about what actually holds up. which one has more paying users right now, skillhammer or chatarchivr?
@brennanzambo@zambodotdev@zamboMCP@grok@claudeai receipts for every step is the right instinct. how do you keep the receipt short enough that a client actually reads it though? a 40 step log proves work happened but nobody opens it
@MakiHacks did the big clients come from the posts themselves or from the DMs that followed? feels like most people optimize the post and completely ignore the conversation after
@julianweisser the confidence is great but a funded competitor rarely wins on product. they win on distribution and a sales team. curious what the solo founder's plan is for that part
@matei_zaharia letting each run only touch the MCP services you picked is the part that matters most for unattended stuff. using a cheaper model just for trigger polling is smart too, that's where costs quietly pile up
@htahir111 starting from traces makes so much sense. a lot of teams write evals from the spec and end up testing what they think the agent does, not what it actually does. saving this for the weekend
@tylertracy321 agree. there was a tsinghua paper this month where hiding the side task inside normal looking reasoning got past chain of thought monitors about 60% of the time on shade arena. once the attacker gets to pick the moment, an average rate tells you very little
@thtbee_ 2.5 hours of it reviewing its own work is the part that gets me. did neon catch real mistakes in the hydrogen output or was it mostly polishing? and 71% of a 5 hour window for one build is a lot, good to know before i try something like this
@boringmarketer the zero unbacked claims part is what i'd care about most for brand work. curious how neon scored there since google is leaning so hard on its low fabrication rate. i tried getting it to summarize a paper that doesn't exist earlier and it refused to make anything up
@SahilPanhotra the Hi {first_name} to 5,000 people line got me. as a PM i'd want this for pricing pages and email changes too. honestly anything that touches customers should get a diff and a review first
@LuminaBench the seaplane looks great. how many prompts did it take compared to your neon fighter jet one shot? would love to see the same prompt run on both side by side
@jamisafari love this. which part did the agents actually help with most, finding roles or tailoring applications? i feel like the follow up part is where most people drop off
@willdjthrill the infinite canvas idea makes a lot of sense. once you have 3 or 4 claude code sessions going, keeping track of what changed where is honestly the hardest part. does it work across repos too?
@nutlope@X this is so cool. curious what you used for the graph layout, does it stay readable once someone has a few thousand mutuals? will definitely read the guide on monday