@imjustnewatai Consider that the average player should have a offboard GPU so probably it should be better than the mediapipe model.
The arena should reflect a real boxing arena.
There should be VFX for punches and knockout should be possible, when being hit in the face, it should move.
@imjustnewatai Create the best boxing webcam game experience you could do, it should be in first person view, online multiplayer, browser based have realistic movements, especially the z axis (that is very tricky on some mocap models)
The character should be drawn in detailed cartoon like dota
Introducing Griffin, the first model to pass the video Turing test.
48% of people who talked to it live thought it was a real human. Previous systems have had a pass rate <3%. It is #1 on NVIDIA's benchmark for full-duplex AI video.
It’s the first Human Interaction Model (HIM).
@iamspritz mano oq me impressionou é a voz, como fez pra criar essa entonação etc
também seria top se dissesse mais ou menos quais tool calls a IA faz pra criar essas músicas
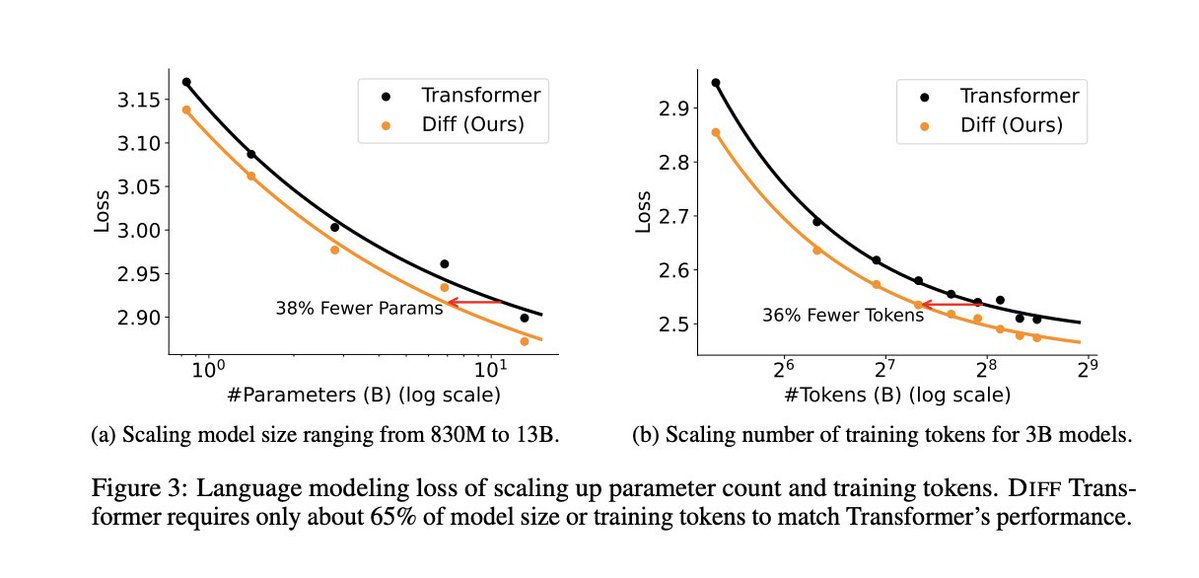
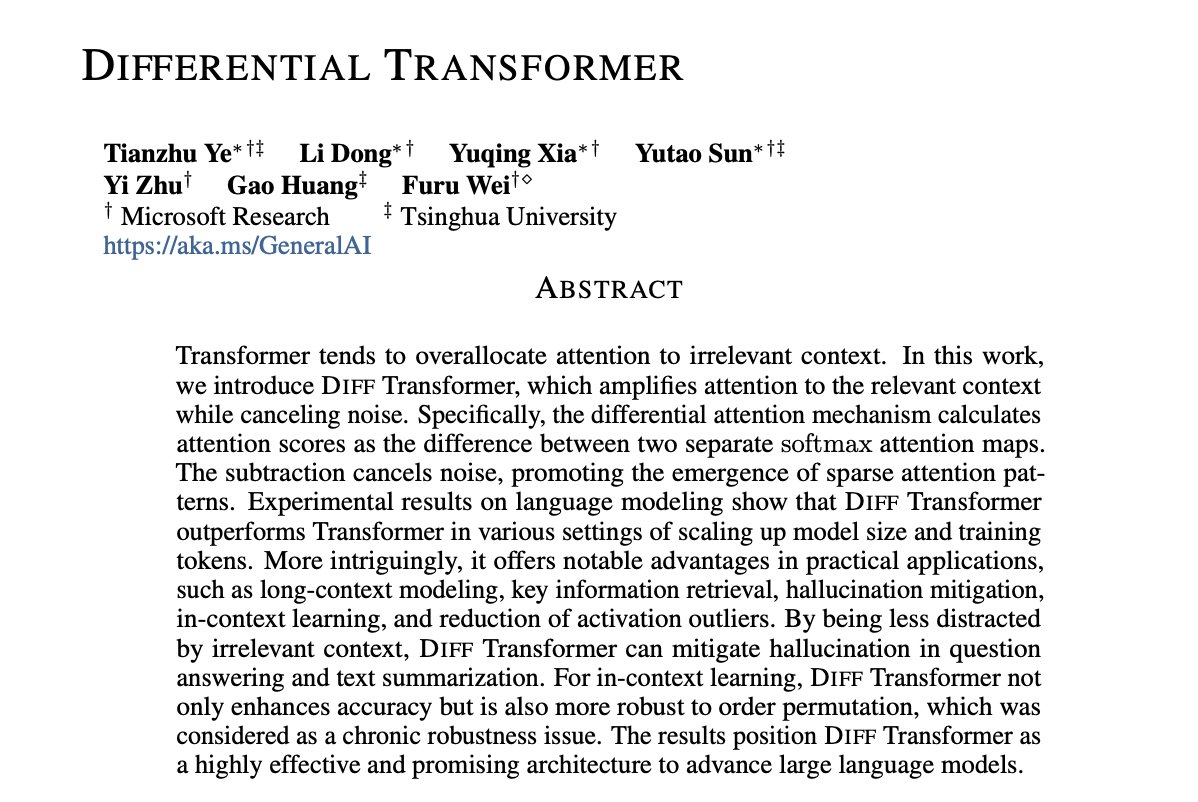
Attention is inherently noisy! 🧠
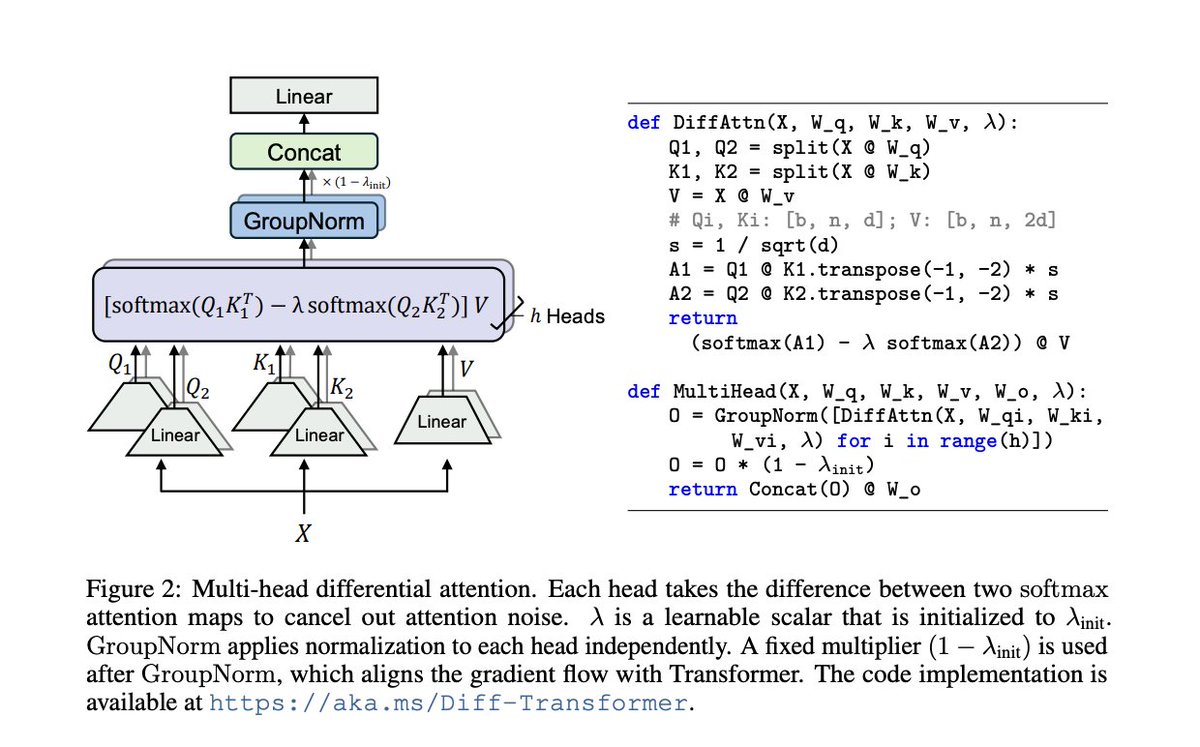
The "Differential Transformer" subtracts two attention maps to cancel out noise and focus purely on the signal.
A massive leap for long-context reasoning without hallucinations! 👇
https://t.co/lqnxKyEs2i
@RisingSunInt_ Actually pixel art is one of the hardest art forms for AI to get right- I've been working on it for over 4 years and we still aren't there completely.
Getting closer every day, but an experienced pixel artist can tell you a million things wrong with this horse animation.
@DonFutboI Cara fica muito claro como as linhas eram mais abertas na época haha, hoje em dia se vc receber a bola sem saber pra onde vai acabou...
É muiito mais compactado o bloco
@fastrlife If you increase output.. at the end of the day you will still need caloric deficit to loose weight...
Also, caloric deficit increases lifespan according to several studies..
MiMo-V2.6-Pro debuts as the top open weights model on the Artificial Analysis Intelligence Index (46). At $0.13 per Intelligence Index task, it lands on the Intelligence vs. Cost per Task Pareto frontier
@Xiaomi has just released MiMo-V2.6-Pro, an open weights model with major advances in intelligence over its predecessor, MiMo-V2.5-Pro (Intelligence Index: 26). Despite the improvement, it retains the same attractive pricing at $0.435 per 1M input tokens (with a 99% cache-hit discount) and $0.87 per 1M output tokens. This makes MiMo-V2.6-Pro one of the most cost-efficient models to deploy.
MiMo-V2.6-Pro is an MoE model with 1.02T total parameters and 42B active parameters. Stay tuned for additional analysis of the model.
Check out MiMo-V2.6-Pro full benchmarking breakdown here: https://t.co/czBJhQKuWJ