Benchmark Spotlight: @getcontextdev
Benchmark: Company News Search
Metric: Accuracy vs Cost
This benchmark tests whether a search API can return the results needed to answer factual questions about recent company events: layoffs, launches, acquisitions, funding rounds.
@getcontextdev 's POST /v1/web/search with numResults=10 answers 98.0% of questions correctly for a total of $1.32, securing the second position out of 19 web search endpoints on this benchmark.
@ExaAILabs fast leads at 99.3% for a total of $2.10. The two accuracy values are within Wilson interval of each other (95% confidence).
Adit Abraham of @reductoai on why everything in AI is "state-of-the-art all the time," and how to find what actually works for you:
"One of the unfortunate things about the AI industry... is benchmarks have become marketing over time."
"There's a public benchmark out there that we tested where if you take the same documents and you add a little bit of noise, like you tilt it one degree, you add a little Gaussian blur, the provider that published the benchmark gets way, way worse than everyone else, but everyone else is kind of consistent."
"Our recommendation is actually LLM as a judge is quite strong today if you're thoughtful about how you think about a rubric and how to approach it."
"We want to see the industry move closer to people testing on their own data, with tools maybe to make that evaluation easier."
"Instead of trusting a generic benchmark, you really should be at a point where you know what works best for you."
@aditabrm
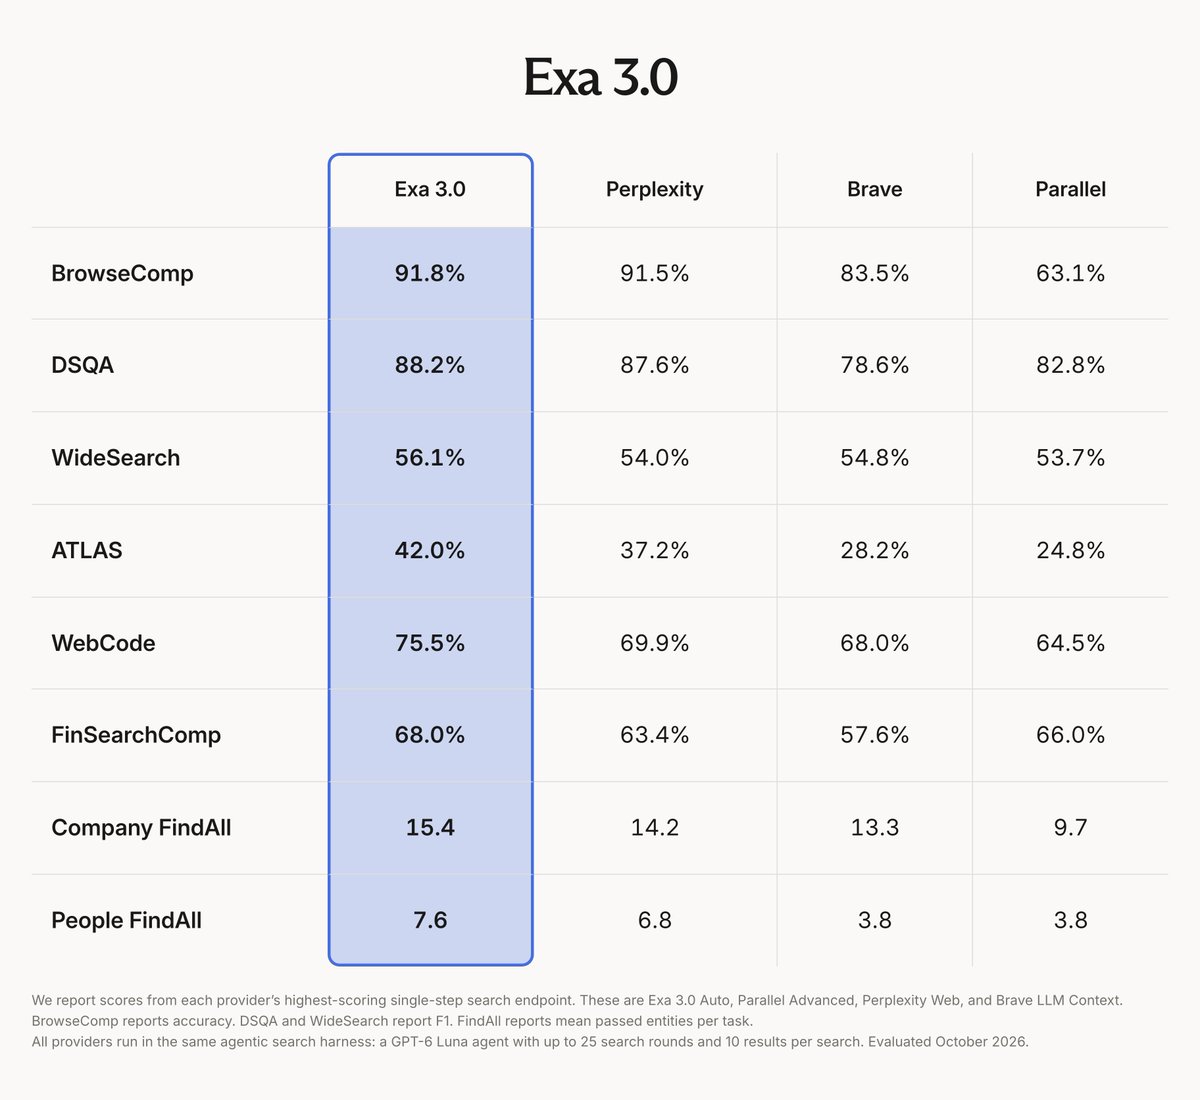
Introducing Exa 3.0: our largest ever improvement to search quality.
Exa is now #1 on every benchmark we tested, from public evals to verticals like coding and GTM intelligence.
It's the result of multiple research breakthroughs 🧵
Eval harness is Open Source
Eval harness + code: https://t.co/1Uf6W8NvmT
Public dataset: https://t.co/qSx8OAb9Mb
Full benchmark: https://t.co/eRpMQnQd61
Today we're launching our next major version of LegalParseQA. It's a benchmark to measure how well document parsers handle strikethroughs and legal redlines, and how well AI agents paired with document parsers can assist with Legal Q&A over those contracts.
It builds on our previously launched LegalParseQA, and introduces a lot of exciting changes.
Reducto, LlamaIndex and Extend are partners. Partners suggest domains, help us understand which evals and benchmarks are useful to their customers, and subscribe to our evaluations on the public and validation sets. Task design, data preparation, labelling and the held-out set are not shared with or influenced by any partner.
Our upcoming major version release for LegalParseQA Benchmark accounts for parser variation and model variation across multiple runs to filter out noise & along with LLM-as-a-judge for evaluations and grading.
@reductoai@llama_index@ExtendHQ@datalabto@MistralAI@Pulse__AI
Benchmark Insights: LegalParseQA
LegalParseQA is an independent benchmark to measure how well document parsers handle redlined contracts. It covers redlines in places that usually break parsers like tables, footers and references that span multiple pages.
We compared 7 standard document parsers against the frontier models: @claudeai Fable 5.1 and @OpenAI GPT-6 Astra.