Nice strategy by reviewers. Ask for A LOT OF EXPERIMENTS, authors provide strong rebuttal, then say this much experiments need another full review and I'll maintain my score. Blatant disrespect to authors time and effort.
@NielsRogge It was never strictly required. I find it helps to do so, especially for points I'd like the reviewer to focus on.
I often use the markdown quote blocks with the reviewer's comments so its easier for the reader to follow my response and what is it I am trying to address.
i feel like calling a result “mathematically trivial” in ICLR review now has lost its teeth.
all results are effectively mathematically trivial now cuz astra or the upcoming internal model can probably prove anything.
it’s more about whether the result changes how we think about things or teaches us something and whether the paper is written in a honest/interesting way.
by the same standard, it also makes no sense to claim “mathematically nontrivial” as a paper’s primary contribution without any other redeeming factors for the same reason.
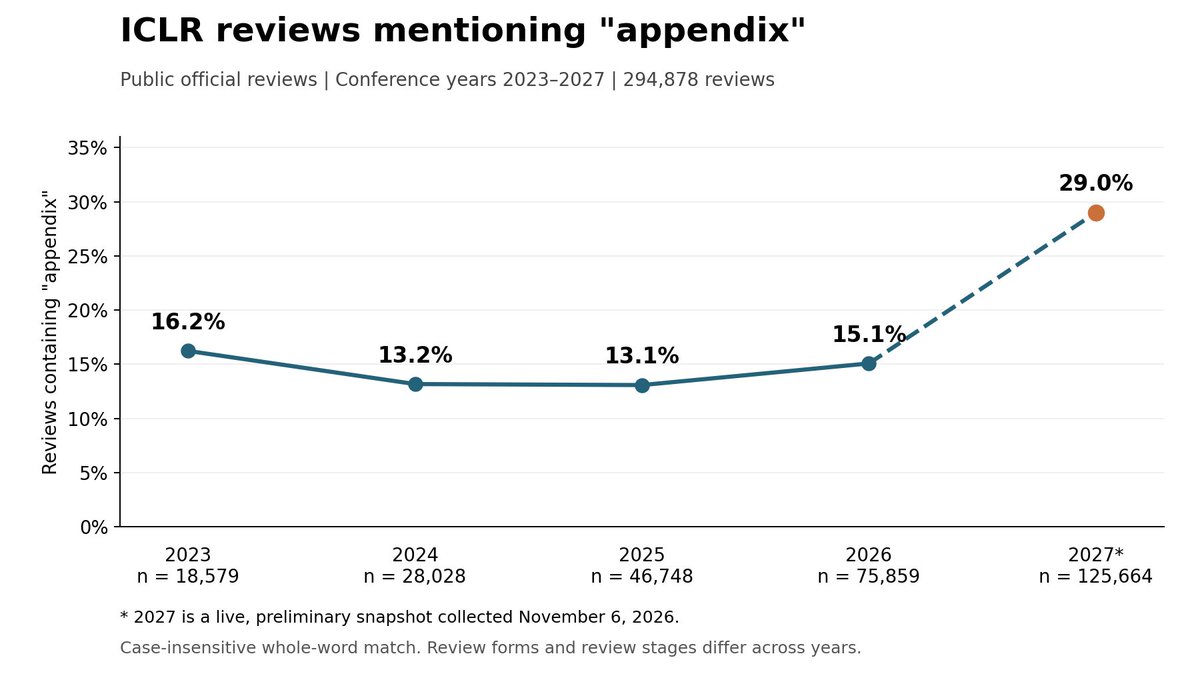
ICLR 2027 reviews are out. I pulled every ICLR review since 2025, about 250k of them, and it's not looking great.
AI written reviews are now the majority (* based on a sample):
2025: 18%
2026: 41%
2027: 65%
Scores are collapsing into the middle, and as others have pointed out - most consolidate around "Weak reject" (score 2). Weak rejects went from 36% of all scores to 57%. Clear accepts and rejects fell from 41% to 21%.
An indication that this is an AI phenomena - AI-flagged reviews picked a clear side less than half as often as humans.
Then you have the really awkward slip-ups.
94 reviews this year call the paper "the provided manuscript." That's chatbot for "the PDF you uploaded." In 2025 there were zero.
28 complain the paper is full of garbled numbers. Those are probably the line numbers embedded in the submission's margins, which is what they look like after a chatbot turns the PDF into text.
23 reviews have a Weaknesses section written for a different paper, word for word. For example, one paper on RL training got criticized for its chemistry. It has no chemistry. In half of these cases, the two reviews were posted less than 9 minutes apart.
I'll leave everyone to draw their own conclusions, but clearly we're not adapting quickly enough.
I am an AC for ICLR 2026. One of the papers in my batch was just withdrawn. The authors wrote a brief response, explaining why the reviewers failed at their job. I agree with most of their comments. The authors gave up. They are fed up. Just like many of us. I understand. We pretend the emperor has clothes, but he is naked.
Here is the final part of their withdrawal notice. I took the liberty to make it public, to highlight that what we are doing with AI conference reviews these last few years is, basically, madness.
---
Comment: We thank the reviewers for their time.
However, upon reading the reviews for our paper, it became immediately apparent that the four "reject" ratings are not based on good-faith academic disagreement, but on a critical failure to read the submitted paper.
The reviews are rife with demonstrably false claims that are directly contradicted by the text. The core justifications for rejection rely on asserting that key components are "missing" when they are explicitly detailed in the manuscript. Some specific examples are (and many are even fake claims).
Claim: Harder tasks like GSM8K are missing.
Fact: GSM8K results are in many tables, like Table 2 (Section 4.2) and Appendix G.
Claim: The method does not use per-layer ranks.
Fact: This is the entire point of our method. The reviewer clearly mistook our method for the baselines. (Section 2, Table 1).
Claim: The GP kernel is not specified.
Fact: It is specified in Appendix E (Table 6).
Claim: There is no ablation of the method's three stages.
Fact: Section 4.4 ("Ablation Study") and Appendix J are dedicated to this.
Reviewers have a fundamental responsibility to read and evaluate the work they are assigned. The nature of these errors is so fundamental, so systemic in overlooking explicit content, that it goes far beyond what "limited time" or "oversight" can explain. This work has gone through several rounds of revision over the last year. In earlier submissions, the paper usually received borderline or weak-accept scores.
Numerous signs strongly suggest that some reviewers are relying entirely on AI tools to automatically generate peer reviews, rather than fulfilling their fundamental responsibility of personally reading and evaluating manuscripts.
We strongly protest this.
This is a gross disrespect to the authors. It is a flagrant desecration of the reviewer's sacred duty. It fundamentally undermines the integrity of the entire peer-review process.
Given that the reviews are not based on the actual content of our paper, we have decided to withdraw the submission.
We leave this comment so that future readers of the OpenReview page are aware that the items described as "missing" are already present in the submitted manuscript. These negative reviews for this submission are factually unsound and do not reflect the content of the paper. We cannot and will not accept an assessment that is not based on the work we actually submitted.
@nsaphra True, I agree. I’m not sure this is solely down to slop papers. In general, it seems as though patience and respect for the work are in short supply.
Couldn’t have said it any better. I’m unsure if reviewers deliberately ignore the distinction. I now have two reviewers who think me citing the arxiv version of some papers is a critical weakness 🤷🏻♂️
My biggest struggle with reviews in 2026 is that (AI) reviewers don’t seem to know the difference between limitations and critical issues. An LLM can easily find 100+ limitations in any paper (even the best ones in history), but that doesn’t mean the paper shouldn’t be accepted.
Introducing ShadowBench: can frontier models recreate shadow puppets?
The model gets an RL environment with a curtain and 3D hands, and must pose them joint by joint until it matches a diagram from a 150 year old (!) puppet book.
Crafted at @perpetual_si
Happy to announce our new pre-print on Multiparty Human Motion generation!
Paper: https://t.co/eDuZIL6dZj
Most generative models of human motion treat people independently or leave this structure implicit. Our new preprint makes it explicit.
BRAID (Bilevel Representations for Agent Interaction Dynamics) is a hierarchical sequential latent-variable model of multi-person motion:
→ A group latent captures the shared dynamics of an interaction; person latents capture each individual's behaviour, conditioned on that evolving context.
→ Real social scenes are rarely fully visible, because people occlude themselves and each other. BRAID is a hierarchical sequential Neural Process, so its latents are inferred from whatever subset of joints and people is observed.
→ One model with no task-specific heads handles social forecasting, inpainting of occluded joints or entirely missing people, and partner response generation. It is trained on SMPL-X bodies across conversation, dance and boxing data.
→ It produces varied plausible completions, not a single averaged future. A socially valid continuation need not match the one recorded future, so alongside standard metrics we evaluate synchrony and cross-person structure.
→ The latents are inspectable: for instance group latents separate Latin from Western ballroom styles, and person latents keep the same individual close across different groups without explicit identity features.
Why it matters:
- For motion capture, this gives interaction-aware priors, since the people around an occluded person constrain what they are plausibly doing.
- For embodied agents, it gives a compact social state: how the interaction is unfolding and how each participant tends to behave.
- Can drive socially coherent digital humans, act as a social simulator for robots planning around people,
- Or feed world models/LLMs/VLMs the social state vectors to help them reason about people.
Work done with @chiragraman, Yash Surange and Augustinas Jucas (@tudelft@EEMCS_TUD@TUDelft_AI)
I took an Advanced Topics in Computer Vision for my masters in CS focused in AI. CSC 577. Top-tier American university, 2017.
I was the only non-Chinese student in the class. The professor was Chinese.
I arrived late for a class by ~ten minutes, walked in, and it was being taught in Mandarin.
This debate is insane
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq