And the appeal process is really bad! I just got the same email again after appealing. No idea what policy was violated or how I can correct any error on my part. What am I even supposed to do? @ClaudeDevs
@claudeai@AnthropicAI
Having a really terrible experience with random account suspension on my pro plan. Random usage policy violation, when in fact i had not even been using Claude much lately. I was actually looking forward to using it more in coming weeks.
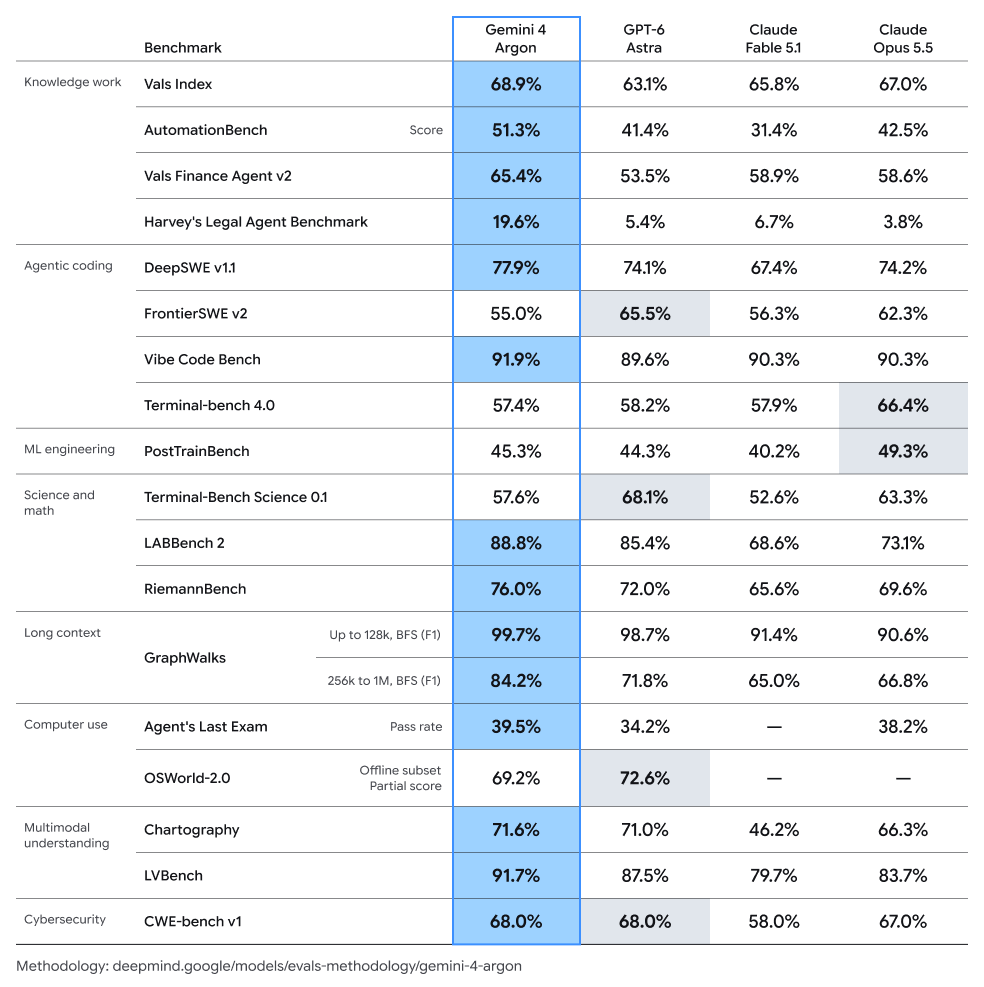
Lots of discussion out there about our next model(!), so I wanted to give an early look as soon as possible. Introducing Gemini 4 Argon!
It shows frontier performance in complex workflows, cyber defense and software engineering. Teams are using it extensively at Google, from coding to quantum computing, great feedback.
Here’s a look at the benchmarks:
Gemini 3.7 Flash smashed previous Gemini growth records in its first week, making it our fastest growing model yet. Great to see the huge excitement from our developer community! Now running in Search and @Geminiapp too.
Today we're launching Gemini 3.7 Flash - our latest workhorse model for coding and agentic workflows, with an introductory price at half the original cost of 3.6 Flash. ⚡️
We have been iterating rapidly with the Flash series, going from 3.5 to 3.7 in just 3 months, making it more helpful across a wide range of tasks:
• Software Engineering (DeepSWE v1.1): 37.0% ➔ 65.3%
• Web Development (Code Arena Elo): 1506 ➔ 1588
• Enterprise Automation (AutomationBench): 13.4% ➔ 30.4%
@bcherny FR: Claude sees remaining context in the current window and says, "I can ship x but not y in the remaining budget before we have to wait for 5h. Proceed?"
Resuming development after the window reset unnecessarily eats a lot of tokens. I'd rather ship small and compact.
I don't know when this /btw feature was launched in Claude Code, but it is absolutely delightful!
Also, discovering new features in the terminal is somehow more fun than in the app.
For frontier models, model personality is an invisible layer of the UX for consumer apps.
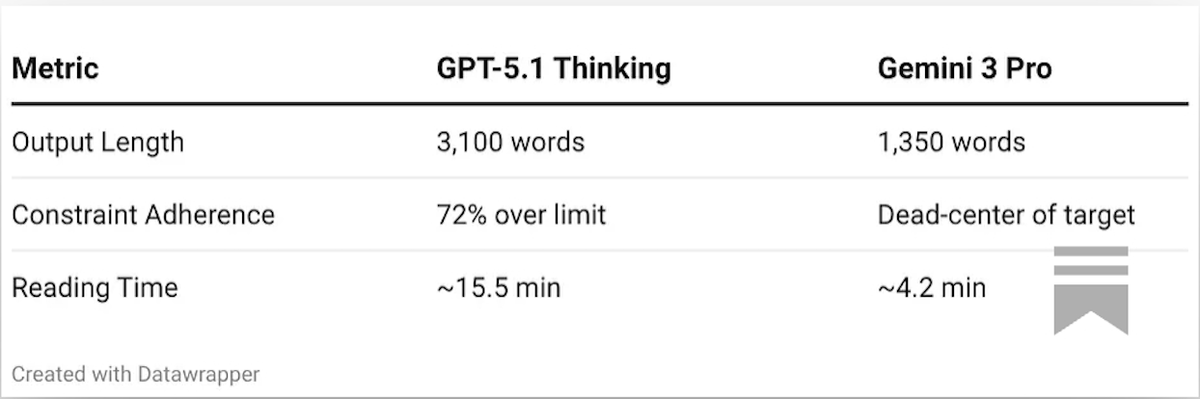
I conducted a 2-part eval of Gemini 3 vs. GPT-5.1 Thinking to see how their internal rewards handle prompt constraints.
Result: Gemini seems 2.3x token-efficient than GPT! Post below
Although GPT 5.2 is out, the idea here is to evaluate the "Thinking" architecture, and the structural bias here seems to persist across incremental model updates.
Same prompt, yet 2.3x token difference!
Part 1: https://t.co/FFSNV7tQHh
Part 2 about steerability coming soon!
@bcherny Thank you for sharing! Could you share more on how to get Claude to iterate on UI/UX for webapps? I often find that opus is great at backend out of the box but its first attempts for new ui features tend to be somewhat off. I send screenshots and logs to CLI and ask it to fix.
The biggest downside of taking @shreyas' product sense course is that I can never again work with anyone who doesn't understand these concepts.
This includes not just co-founders and product leaders, but probably also marketers and sales leaders.