We trained a first-of-its-kind family of models: SWE-grep and SWE-grep-mini.
Designed for fast agentic search (>2,800 TPS), surface the right files to your coding agent 20x faster.
Now rolling out gradually to Windsurf users via the Fast Context subagent.
You can use Cerebras' gpt-oss-120b to build realistic speech-to-speech voice interfaces with emotion via @hume_ai's new EVI 3. Perfect for your next voice ai project!
Link to try below 👇
Frontier AI is now on Cerebras.
This week we are launching Qwen3-235B—@Alibaba’s flagship reasoning model that rivals ChatGPT and Claude. In classic Cerebras style, we run the model at 1,500 tokens/second.
That means reasoning time goes from 60 seconds on GPUs to just 0.6 seconds. For enterprise customers, we're enabling them with 131K context, which enables production-grade code generation. @Alibaba_Qwen 3-235B will be available for all to try later this week.
Meanwhile, try Qwen3-32B for free at https://t.co/39xaLQwfpL
🤯 Holy mother of AI
Met @hi_im_dev_ yesterday on a YC event in Paris.
Amazing dude
He showed me @cerebras and how fast their llama model was...
Didn't believe it at first
I plugged the model on my SaaS compared to gemini-2.5-flash-preview-04-17
The result in video, it's like 100x faster.... WTF
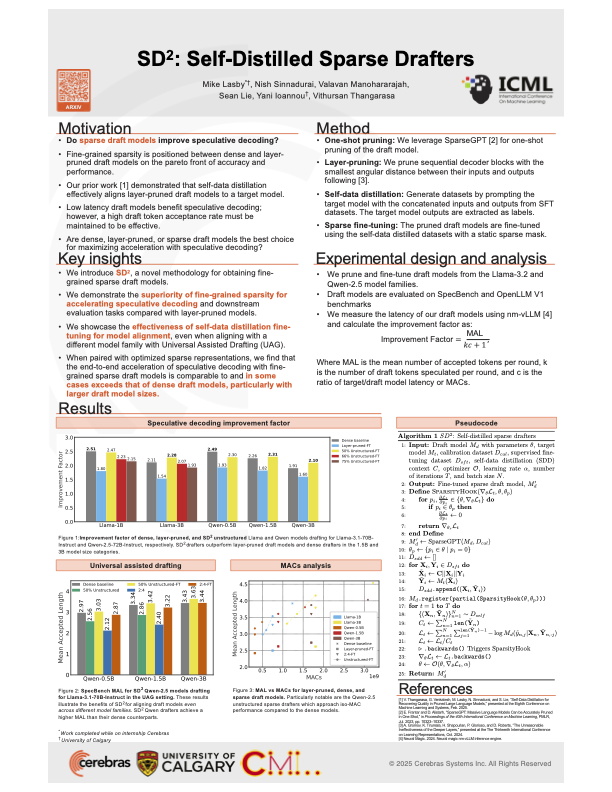
Featured Paper at @icmlconf - The Internationall Conference on Machine Learning:
SD² - Self-Distilled Sparse Drafters
Speculative decoding is a powerful technique for reducing the latency of Large Language Models (LLMs), offering a fault-tolerant framework that enables the use of highly compressed draft models.
"Before Cerebras, everything sits sub 200 tokens per second output. And after us, on every model, you have vast improvements, order of magnitude improvements. And what this allows you to do is deliver something special and different to your customers —faster responses, richer interactions, more intelligent systems."
But how?
We do this with a relentless commitment to bottoms-up engineering and a fearless approach to tackling extraordinarily hard problems. We began by designing the industry's largest processor..."
Cerebras x @IBM : Partnering to help enterprises accelerate AI adoption without compromise.
Businesses shouldn’t have to choose between bleeding-edge AI performance and enterprise-grade reliability.
It’s no longer enough for AI to be powerful, it also has to be practical, efficient, and trustworthy at enterprise scale.
That’s exactly why we’re working with IBM and @IBMwatsonx
17. Finally, have you eaten a banana lately? I had one yesterday. They're pretty good.
Also, my father was a longshoreman who unloaded banana boats for years. If you like me or my tweets, thank a banana!
I love the art banana.
The end.
To understand success, pay less attention to the final product and more to the mundane process.
It's way more fun to read Harry Potter and see Hamilton than it would be to watch @jk_rowling and @Lin_Manuel write.
But the seeds of greatness are planted in the daily grind.