📃My "ML vs DL models for pulmonary nodule detection in chest X-rays" paper is published in Health and Technology (Springer)! Key finding: Traditional ML (SVM, Random Forest) offered better performance with limited data than DL models. https://t.co/2vtKsL82Me
Use expensive reasoning only when it adds value.
Games are a great playground for testing this idea.
Where would you draw the line between LLM reasoning and code?
#AI#LLM#python#agents#dontstarve#AIEngineering#GameAI
I’ve been thinking about my Don’t Starve AI agent again.
What if an LLM didn’t need to decide every move?
Instead:
LLM sets the goal.
Jev handles intermediate decisions.
Rules handle simple actions.
♻️ Repost this for someone debugging an agent. It may help them inspect the system before swapping the model.
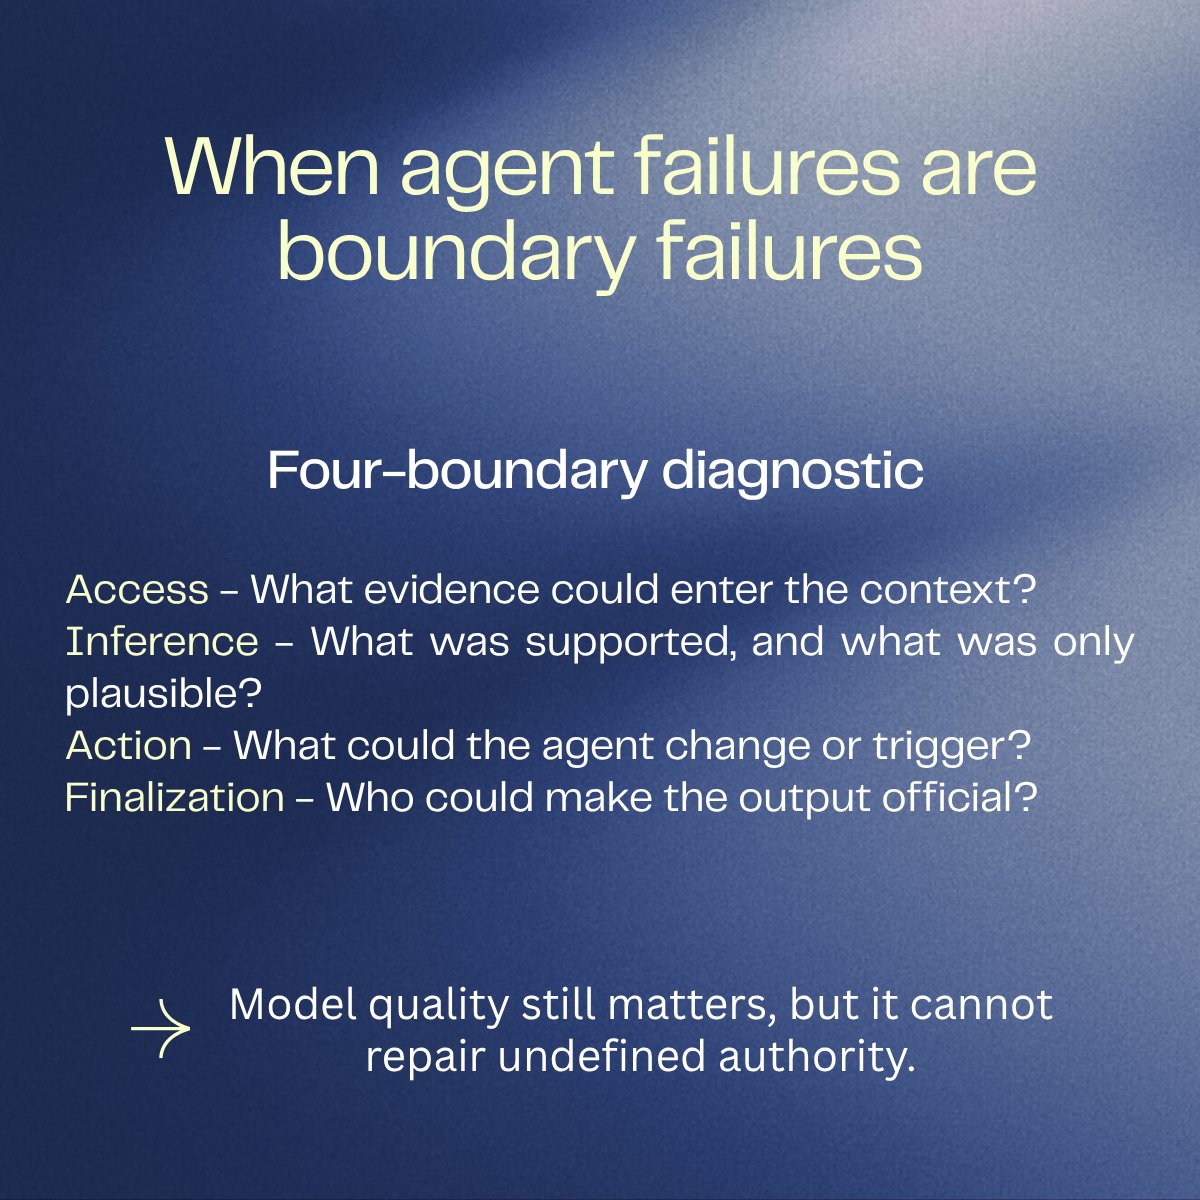
📃 Read the full four-boundary guide: https://t.co/eiloFJ00ed
#AIEngineering#AgenticAI#SoftwareArchitecture
1/ I used to ask whether the agent got the answer right. Then I watched it search when it shouldn’t, return no evidence, and still invent gaps. So I started evaluating the path, not only the output.
4/ Model quality still matters. It cannot repair undefined authority. The biggest difference between MarketMind and Folium is that authority, evidence, and human review are now explicit.
Before upgrading the model, I want to know which boundary failed.
5/ Before upgrading the model, name the failed boundary.
📃 Read the full guide here: https://t.co/eiloFJ00ed
👉 Check out my blog: https://t.co/DBd07NBuZV
#AIEngineering#AgenticAI#SoftwareArchitecture
4/ An empty retrieval result can also be correct. If no authorized evidence supports the answer, preserving the gap is safer than widening the search until something plausible appears.
Model capability still matters. But a stronger model cannot compensate for undefined authority
Followed Ben Burtenshaw’s Training Agents SFT tutorial and ran the Gemma 4 repo locally for 100 steps.
Training token accuracy: 0.7291 -> 0.8268.
Useful training signal, not proof of broader agent improvement
@ben_burtenshaw Great article and livestream! The post uses Qwen, but I followed the Gemma 4 repo from the livestream description and ran it locally for 100 steps. Training token accuracy went from 0.7291 to 0.8268. Really useful hands-on intro to SFT from agent traces.
@melissapan@arena@pidotdev Agree. Really insightful experiments. Harnesses arent going away, especially if they can make capable models cheaper to use. I think they will just become more specialized around specific workflows, models, and constraints
@mitchellh I like this one. Explaining the system's current state isnt enough. I should also be able to show the experiments behind my decisions. AI can help me try a lot of things, but I still need to understand the tradeoffs
@Tesla This is why I love FSD. For most of us, it can give us time back. In cases like this, it can give someone some independence back too. Pretty amazing!