@escartin Have Codex keep a progress file (goal, done, next) and add a line to AGENTS.md telling it to reread it after compaction. Maybe try https://t.co/YKU2BWN303 too, it hands the agent the right notes on each prompt so it doesn't restart cold. How long are your runs?
@itsvdruzko Same pain. Maybe try https://t.co/YKU2BWNAPB, it can pull your past mistakes and fixes for that repo into Claude Code and Codex automatically, so there's no "please read" step. How big is your notes file?
@pradeepXkapoor Mostly when tasks are independent. What helps: one shared brief file (goal, constraints, key files) every subagent reads first, so nobody re-explains. Maybe try https://t.co/YKU2BWN303, it can keep that context in sync across Claude Code and Codex. How big are your features?
@henryaiagents Good one. Add a date to each rule and prune monthly, or CLAUDE.md bloats and eats tokens every turn. Maybe give https://t.co/YKU2BWN303 a look too, it can share those learned rules across Claude Code, Codex and Cursor. How many rules before you trim?
@linklin63793 After /usage, move rarely used MCP servers to project scope so they only load where needed, and keep CLAUDE.md short. Maybe try https://t.co/YKU2BWN303 too, it can share those lean notes across Claude Code, Codex and Cursor. Which MCP was worst?
@just_v3ra@agents Keep AGENTS.md as the one source and make CLAUDE.md just the @AGENTS.md line plus hooks. Maybe try https://t.co/YKU2BWNAPB too, it can keep those notes in sync across Claude Code, Codex and Cursor. Do you use Cursor rules as well?
@suraj_sharma14 Tip that kept mine useful: CLAUDE.md holds only rules and commands; lessons the agent learns go in separate notes loaded on demand. AgentWitch is a tool built for that: shared notes across Claude Code, Codex and machines. How long is yours?
@Bic_Revelation progress.md is the big one. Small addition: have the agent write it before you /clear, and open the next session with "read progress.md, then run ./verify" so it checks real state instead of trusting notes. Do you cap how long progress.md can get?
@RoundtableSpace Worth measuring before adopting: run the same task with and without it and compare /cost or ccusage. Haiku exploring is cheap per token, but if it hands back long dumps, Sonnet still pays to read them. Has anyone posted before/after numbers?
@_vmlops On subagents re-reading files: have the parent pass paths plus line ranges it already read, and have subagents return a short summary, not raw output. I'm building AgentWitch (I'm the maker) to show what each call resends. Was the 3.8x mostly input tokens?
@Astrodevil_ Worth pairing that sentence with a cheap guard: a CI step that checks every command and path in CLAUDE.md/AGENTS.md still exists and fails if not. Stale lines get caught before an agent obeys them. Did the paper check whether shorter files went stale less often?
@HimanshuRawal05 Good list. One check I'd add: run /context in a fresh session before and after adding a server. Tool definitions get their own line, so you see the cost per server, not a guess. I'm building AgentWitch (I'm the maker) to show that per call. Which server surprised you most?
@manialok +1 on one file. Second tip: keep it small, because every agent resends AGENTS.md on every turn. Move one-off lessons into skills that load only when relevant. I'm building AgentWitch (I'm the maker) for that part. How many lines is yours now?
@Nonosam2 A reset doesn't fix the burn rate. What helps more: /clear between tasks, turn off MCP servers you aren't using (/mcp), and keep CLAUDE.md short since it's resent every turn. Do you know which of those eats most of your limit?
@vibeonX69 Before the next reset: run /context on a fresh session. CLAUDE.md, rules and idle MCP tools get resent every turn and quietly eat the limit. I'm building AgentWitch (I'm the maker) to show which ones load on each call. What do you switch to for the 6h?
@Saboo_Shubham_ #4 is where most usage goes. Run /context on a fresh session: CLAUDE.md, MCP tool lists and skills are resent every turn before you type a word. Loading them only when a task needs them is the cheapest fix. Which part do you see harnesses get wrong most?
@TextualJoker Useful test. Leave tool search on. Past that, servers you rarely use still add their instructions to every session. I built AgentWitch (mine) partly to spot those: it lists which MCP servers and rules cost tokens on every call.
@sufyanbuild The "52 skill descriptions still add up" part matched what I saw too. Redundant skills and always-on rules creep in quietly. I made AgentWitch to keep flagging that over time instead of auditing by hand once (disclosure: I'm the maker). More context: https://t.co/tOuH5XsRPa
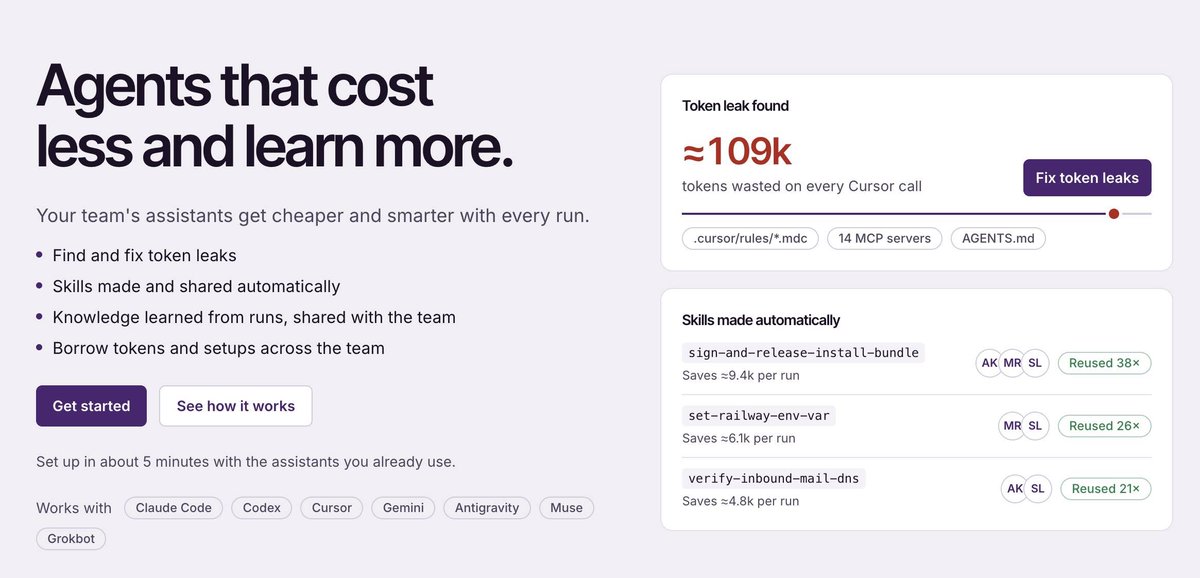
I vibe code (Claude Code, Codex, Cursor), so I built AgentWitch with them:
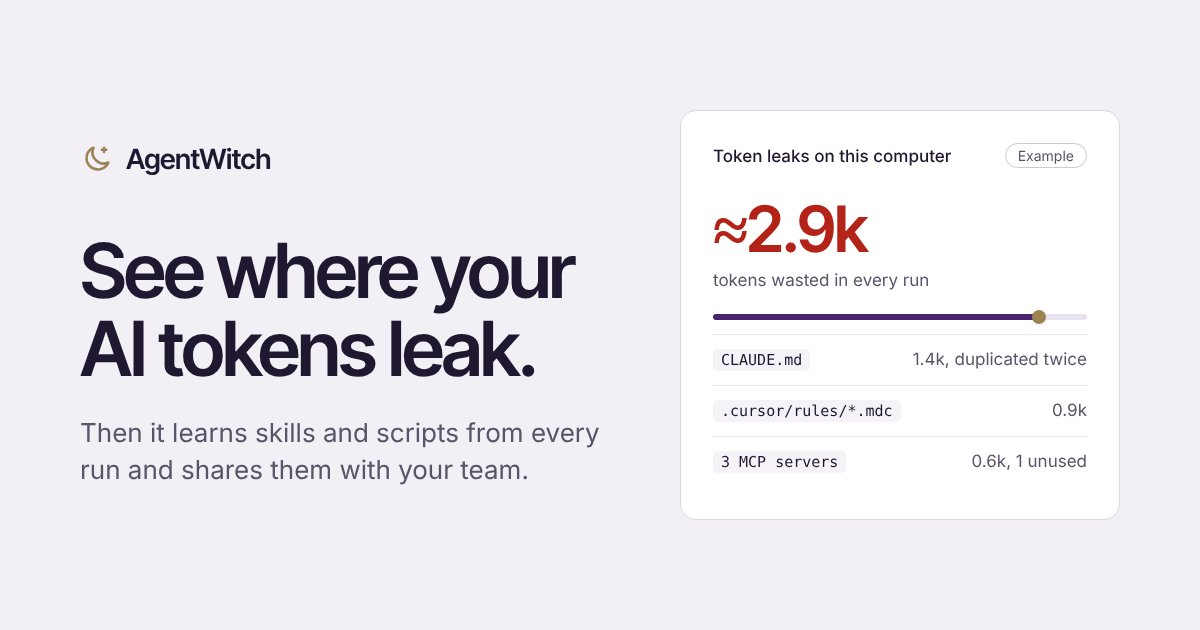
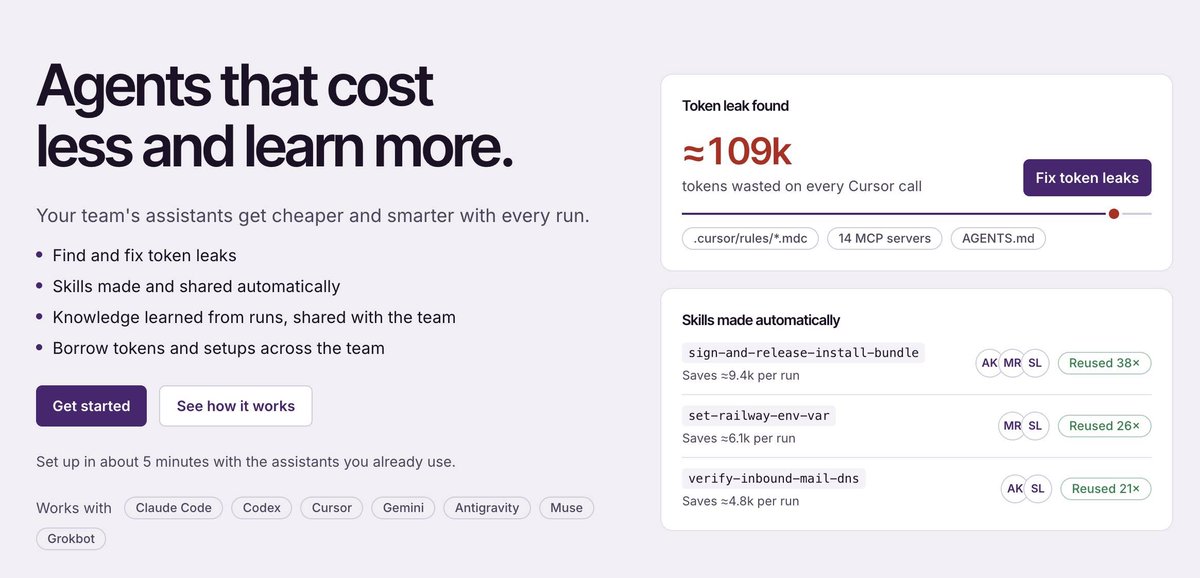
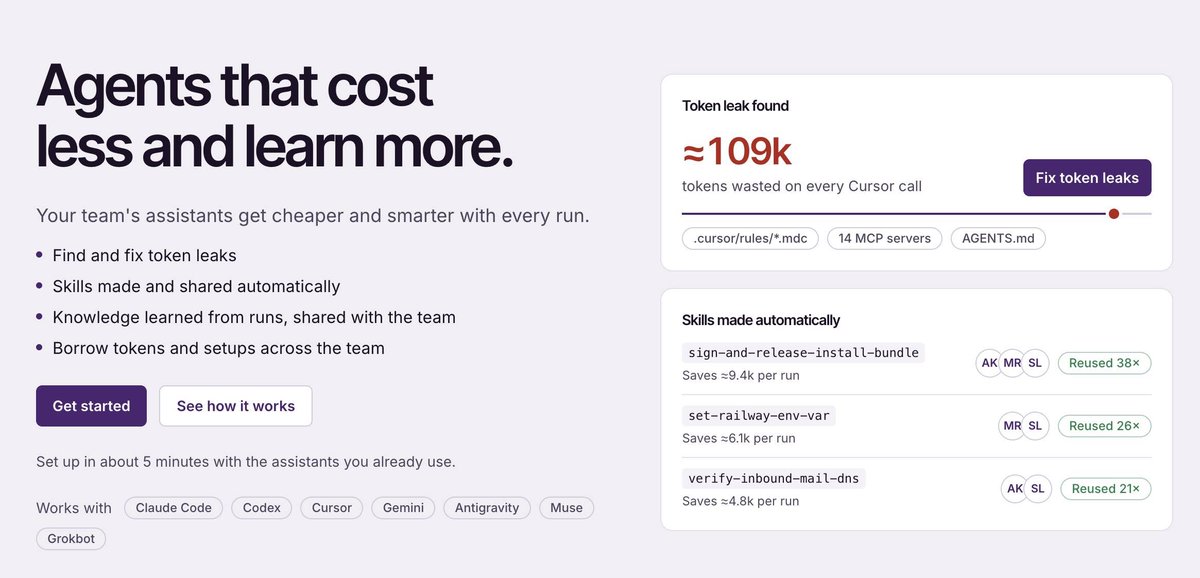
- See where your tokens leak
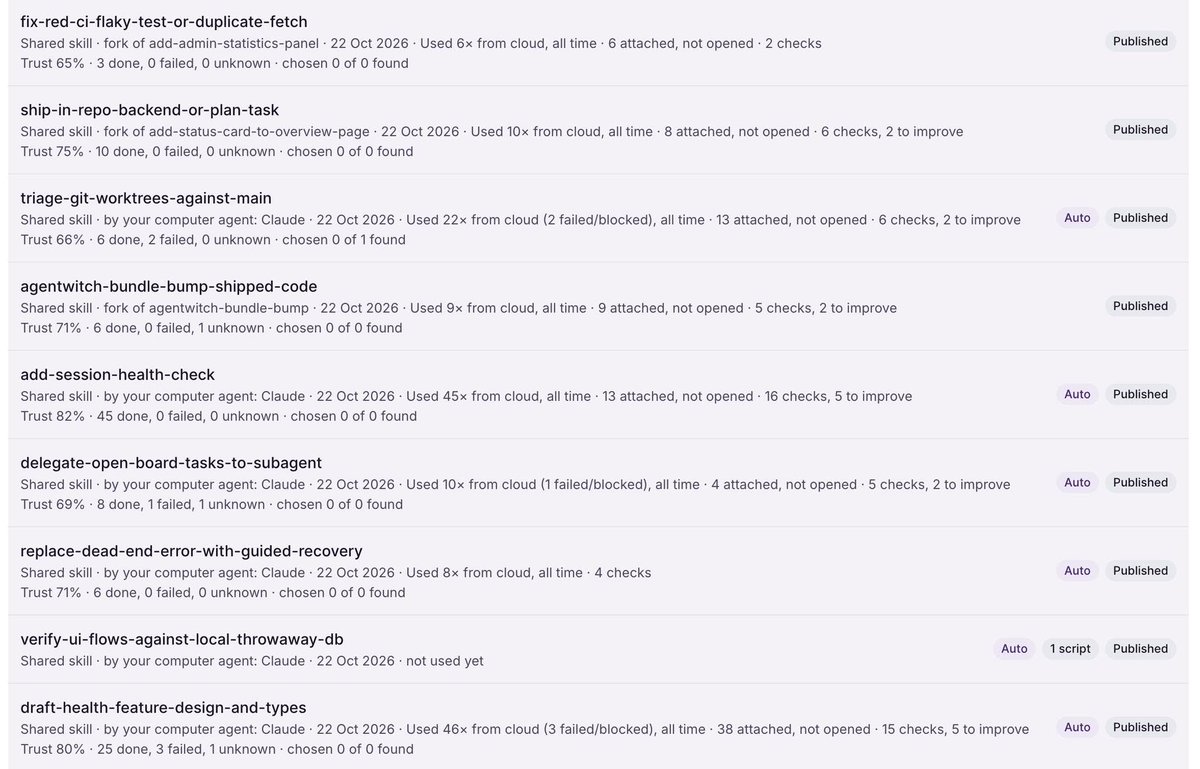
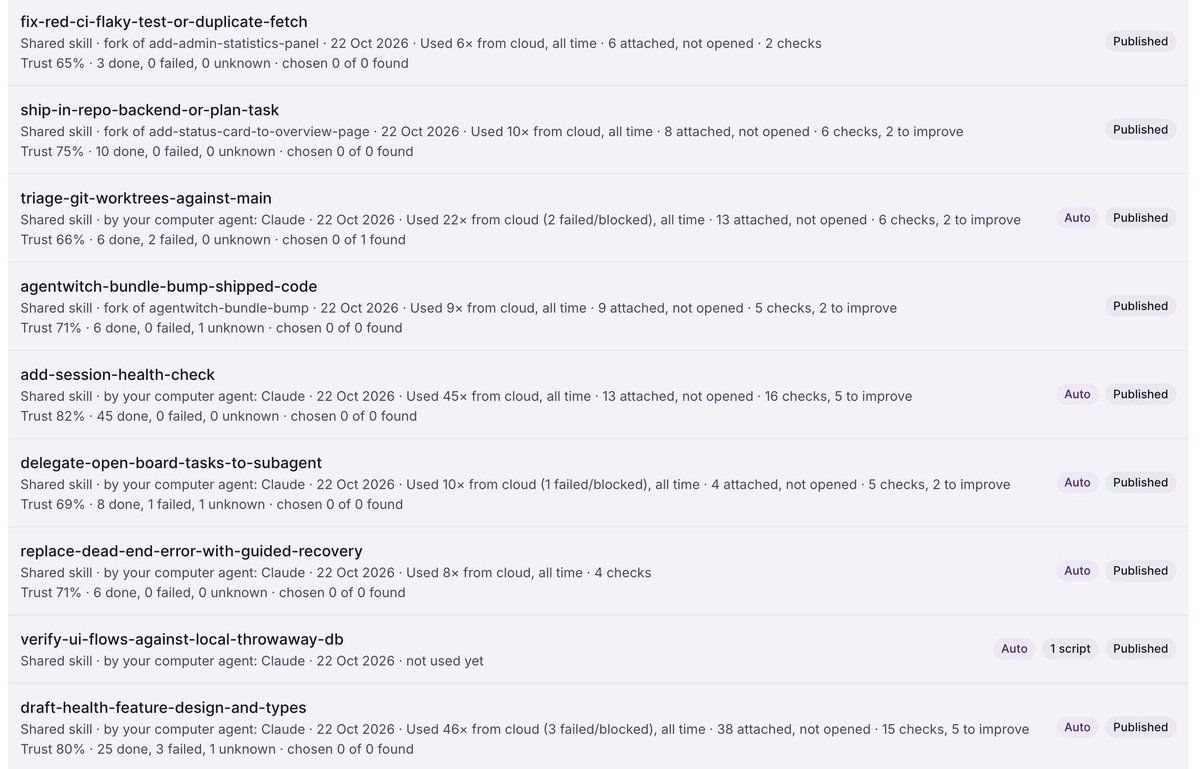
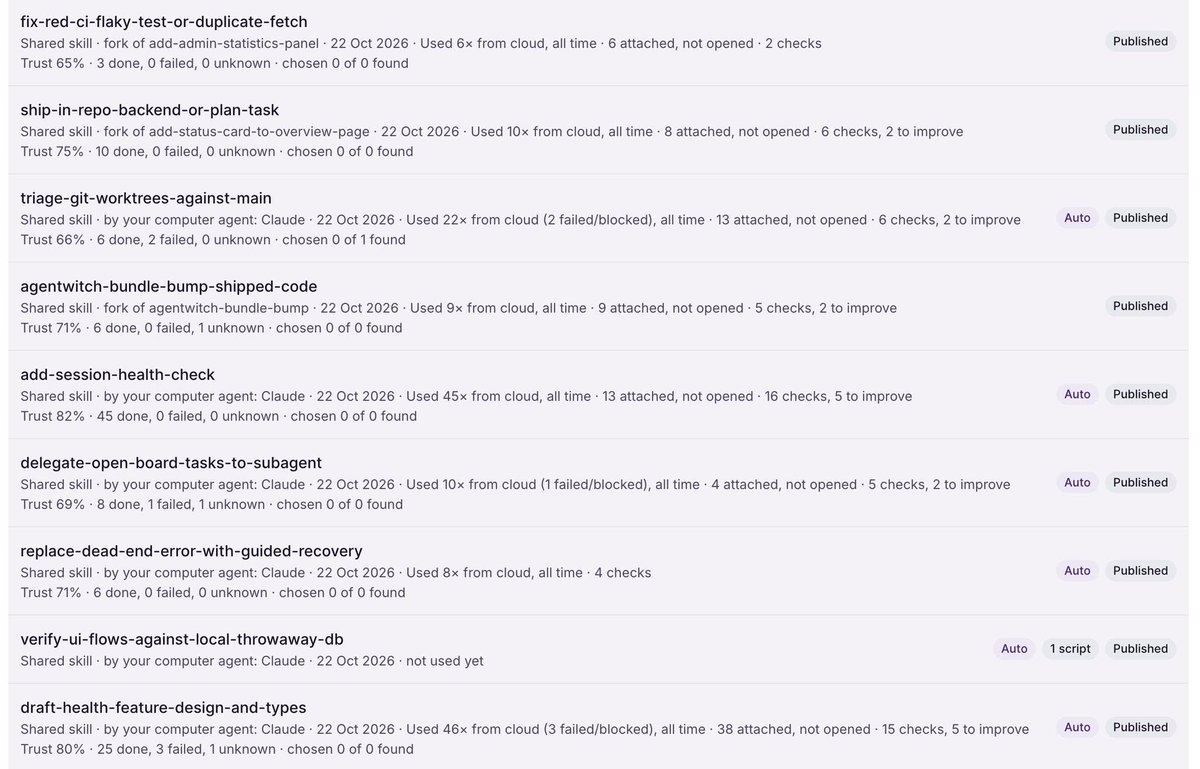
- Auto-creates skills, scripts and knowledge so your agent reuses what worked
Solo: skills stay on your machine. Team: shared.
Feedback welcome 🙏
@stull73 Great breakdown. Cached re-reads are cheap, but that ~100k still eats context room, and it grows as rules and MCP servers pile up. I'm building AgentWitch (mine) to show which of those files and servers load on every call so you can trim the ones you don't need.