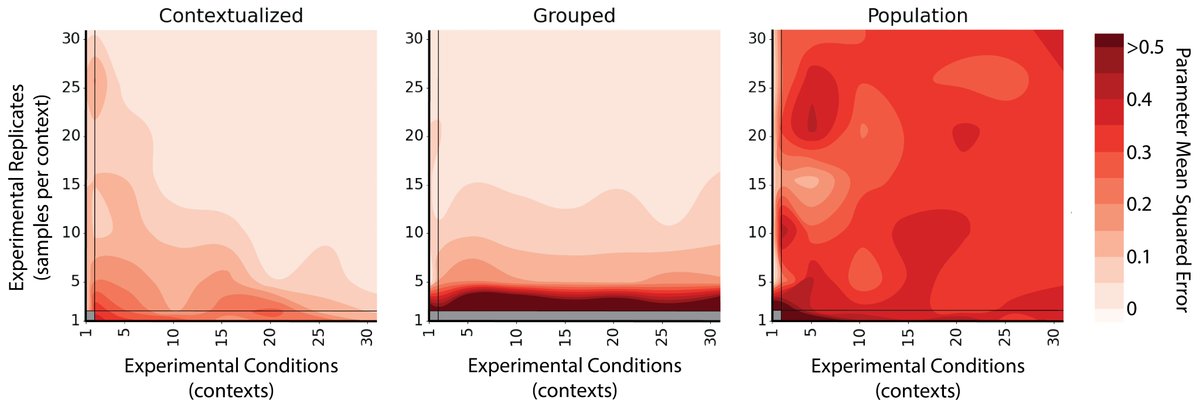
Honored to share a major thread of my PhD research, out now in PNAS. We address a core issue with how models are used for scientific discovery.
Models are so important that they define the entire scientific process... 1/n
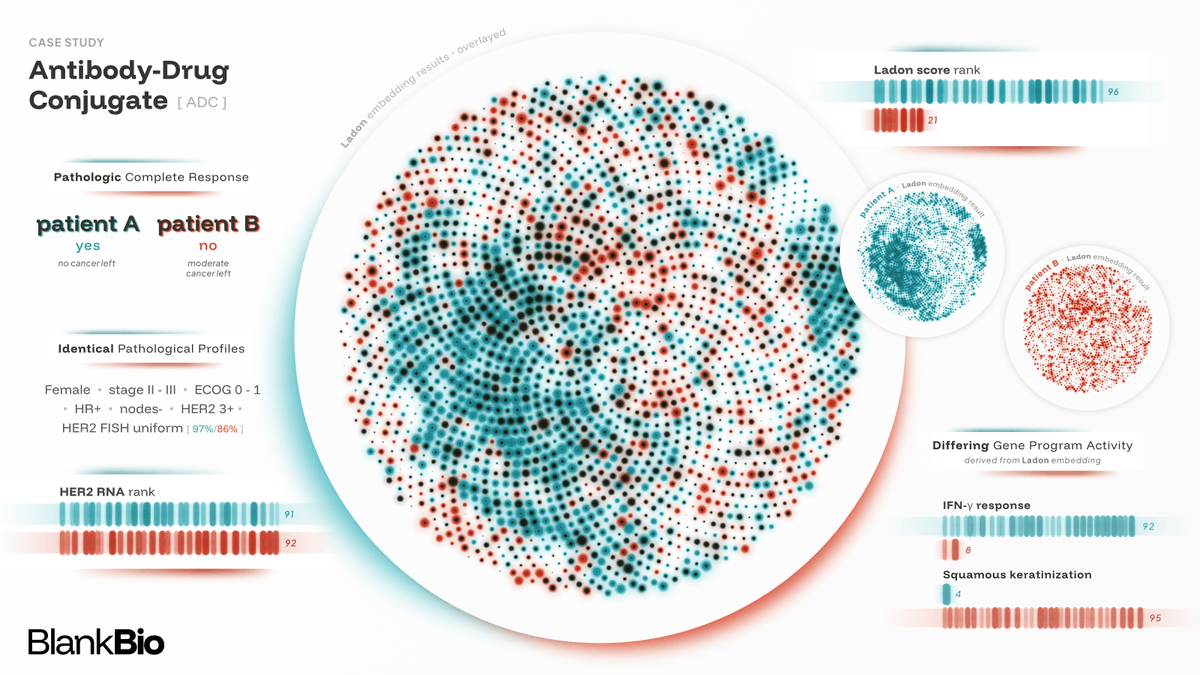
Today, we are excited to introduce Ladon, a state-of-the-art biological foundation model that predicts disease trajectory and treatment response in patients. There is immense complexity in the individual biology of every patient. Two patients can have the same diagnosis and receive the same treatment, yet have very different outcomes: one responds well and lives for years, while the other’s disease continues to progress. Understanding and resolving this heterogeneity to predict outcomes is how we accelerate our delivery of medicines for patients and unlock clinical trial abundance.
Ladon is our first step towards this future: one where we can learn more from every patient enrolled so that we can run smaller, faster trials with higher success rates. We built it to give drug developers quantitative support on billion-dollar clinical trial decisions. Today we're excited to share Ladon's capabilities in our blog and technical report.
Ladon is a 3B parameter model trained on millions of RNA-seq samples spanning decades of technical and biological variation across tissues and species. Ladon beats gene expression baselines, established biomarkers, and existing RNA foundation models at predicting patient prognosis and therapeutic response in 140+ oncology tasks, including external validation on past clinical trials. This is significant because clinical trials are fundamentally generalization problems. We show that Ladon-derived predictions are robust across indications, treatments, and sequencing platforms.
Reach out if you’d like to get started with the model today!
Read more about Ladon in the blog: https://t.co/dpDCYE4wRv
Find more technical details in the white paper: https://t.co/dpDCYE4wRv
@brian_armstrong It's not just replication, we need a standard for anyone (including agents) to replicate, run comparisons, and simplify! We tried this, and found that many past ML results from Nature, Science, and Cell are just an artifact of poorly tuned baselines.
https://t.co/IznDgVaZLM
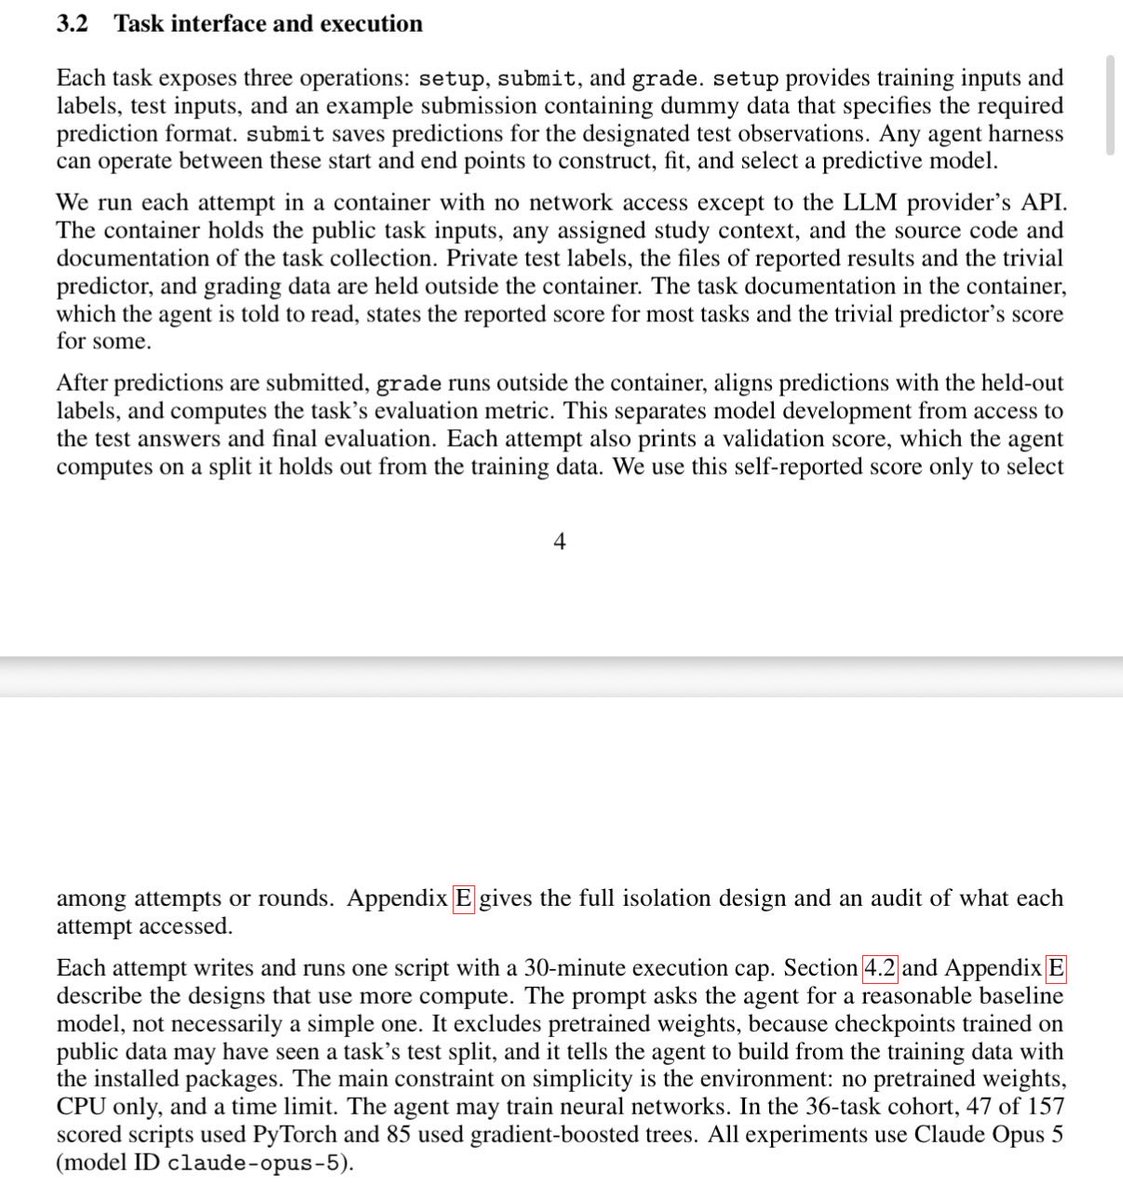
We used coding agents to automatically build baselines for 36 "AI for science" deep learning methods from Nature, Science, and Cell-family publications. These baselines recovered a median of ~95% of the score of the published method, and beat them in 33% of cases.
@rpinho_sci Us too! We build the execution container to mirror a standard consumer laptop. We wanted to produce a procedure that any author could carry out on their own machine, to review their own papers or others'.
We used coding agents to automatically build baselines for 36 "AI for science" deep learning methods from Nature, Science, and Cell-family publications. These baselines recovered a median of ~95% of the score of the published method, and beat them in 33% of cases.
@kdpisda Section 3.2 has the answer you're looking for. The agents work in a container without internet access or test data. Test is held outside the container and only evaluated after the agent has proposed a final solution for the baseline.
Scaling laws depend on a metric that improves gradually with scale in order to extrapolate to a large target scale. We are interested in the accuracy metric, but you might get zero accuracy for small models. You can't extrapolate from a bunch of zeros.
Key idea: introduce a *hint* level, and fit a joint scaling law Accuracy(scale, hint) = ... More hinting makes the problem easier in a controlled way, so accuracy is no longer zero, allowing for extrapolation! Learn more below.
Contextualized gene representations work surprisingly well for predicting multigene perturbation effects.
I’m excited to introduce EMBER, a pretrained gene-centric foundation model designed specifically to learn context-specific gene representations. A joint work with @jmuiuc and @ericxing.
With innovations in single-cell pretraining and dataset curation, EMBER gene representations can be combined with a lightweight probe for single gene knockouts, genetic interactions (double knockouts), and even drug perturbations.
Both a 🧵 and a 🎥, got in front of a camera to share some highlights! (1/n)
Paperclip Datasets is live! Describe the table you need, and agents collect the data from papers, patents, trials and regulatory documents. Each value links to its source passage so you can check it.
Try it: https://t.co/lPJwmb7nfS
Read more here: https://t.co/vPEZ1QRNhv
If you're interested in understanding how LLMs can do weight-space programming and parameter generation, a few months back @ben_lengerich, @ericxing, and I put together a major review that ties this back to basic statistical learning principles.
Statistical estimation is being absorbed into context.
In a new 90-page review, we provide a unified view of statistical and foundation models through the lens of context-adaptive inference! ...
It's still super cool, I just don't want to see the whole emergent capabilities train to run away again.
Relevant slides from @ben_lengerich on why gradient-descent and network updates are almost a perfect application for in-context learning.
This is super cool, but I'm not sure it's emergent. Hypernetworks have been around for a while and it's straightforward to build an RL env for weight generation or modification in smaller models. It probably just means math/code are diminishing in returns and labs have moved on.
i've reproduced the results from the MIT blog post today on weight-space programming. but one additional result i have to add: this is a new, step-change emerging capability that's appeared in just the latest set of models.