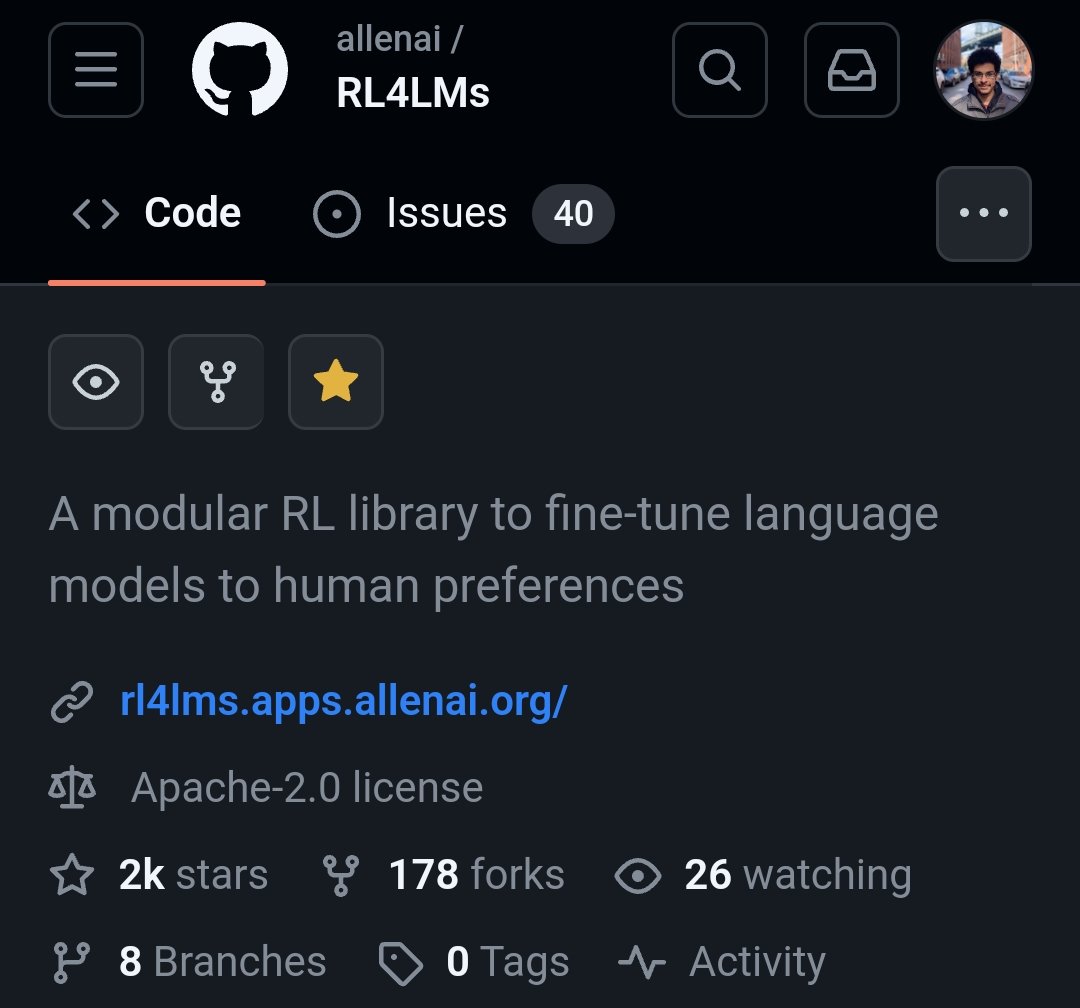
Our work on aligning LMs to human preferences is finally out! Fine-tuning with RL made easy using
-RL4LMs: modular library built on @huggingface + SB3 @araffin2
-GRUE Benchmark with 20+ RFs on 6 tasks
-novel alg NLPO
Github: https://t.co/xlJfLHK2Wn
Paper: https://t.co/64hVUoh0cl
The secret to aligning LMs to human preferences is reinforcement learning. But Why&How is it used? Announcing
💻RL4LMs: library to train any @huggingface LM w/ RL
https://t.co/73rpjTWxfc
👾GRUE: benchmark of 6 NLP tasks+rewards
📈NLPO: new RL alg 4 LMs
🌐https://t.co/7uPL0KD8G4
Nothing groundbreaking here. But it is a nice reminder that autoregressive models are not always the right call, even when they handle things zero-shot. Latency, cost, and all that still count.
After co-inventing ChatGPT, I kept asking myself: why have superhuman chat models not led to AGI?
I’ve spent the last 2 years in stealth building a new way to train models (RLCD), and a new type of frontier AI model that we are releasing today: Jev
• 20-200x faster
• 40-400x cheaper (w/ output tokens free)
• Frontier composable intelligence optimized for decisions
AFAICT the shortest path to AI-based economic revolution
(1/N) New paper! Dataset Reset Policy Optimization for RLHF (https://t.co/kYoOFfiGpf)
RLHF is a popular paradigm for fine-tuning generative models. But the question is, can we design algorithms that take advantage of additional properties of the RLHF framework?
Only a year ago that our paper on when and how to use RL in NLP was accepted to ICLR-23. We're now at 100 citations and 2k GitHub stars!
Less about numbers and just how excited I am that so many people are working on RL for NLP! Only a few years ago this was unimaginable!
Excited to share TRIL - a new RLHF library combining Reinforcement and Imitation Learning for fine-tuning LLMs.
Code: https://t.co/NVyN5TvsS7
Paper: https://t.co/IrcpH2Y3ll
Amazing work led by @j_nadan_chang@xkianteb Dipendra Misra and @WenSun1
Announcing 📣 an update to our paper "Learning to Search Better than Your LLM" and our new Transformers Reinforcement and Imitation Learning Library (TRIL)!
Paper: https://t.co/VwMcTDHUOv
Code: https://t.co/2ViHKZyjZv
New paper! Learning to Generate Better Than Your LLM (https://t.co/D3n7PIpYHK)
RLHF has become a powerful paradigm for fine-tuning LLM, but we only use general-purpose RL algorithms. We introduce new algorithmic paradigm that takes advantage of additional feedback for learning.
Now in #ACL2023!! Look forward to @peizNLP's presentation! See y'all in Toronto and let's chat #DnD dialogue, theory of mind, and all things interactive NLP!!
Camera ready soon!
https://t.co/5r6FJ8u7Bq
Why not both? I fine-tuned flan-t5-xxl (11B) on databricks-dolly-15k. If you want to play with it, I uploaded the weights here: https://t.co/zfcZjJu4X3
(caveat: this was just a quick experiment to help better understand the new databricks corpus)
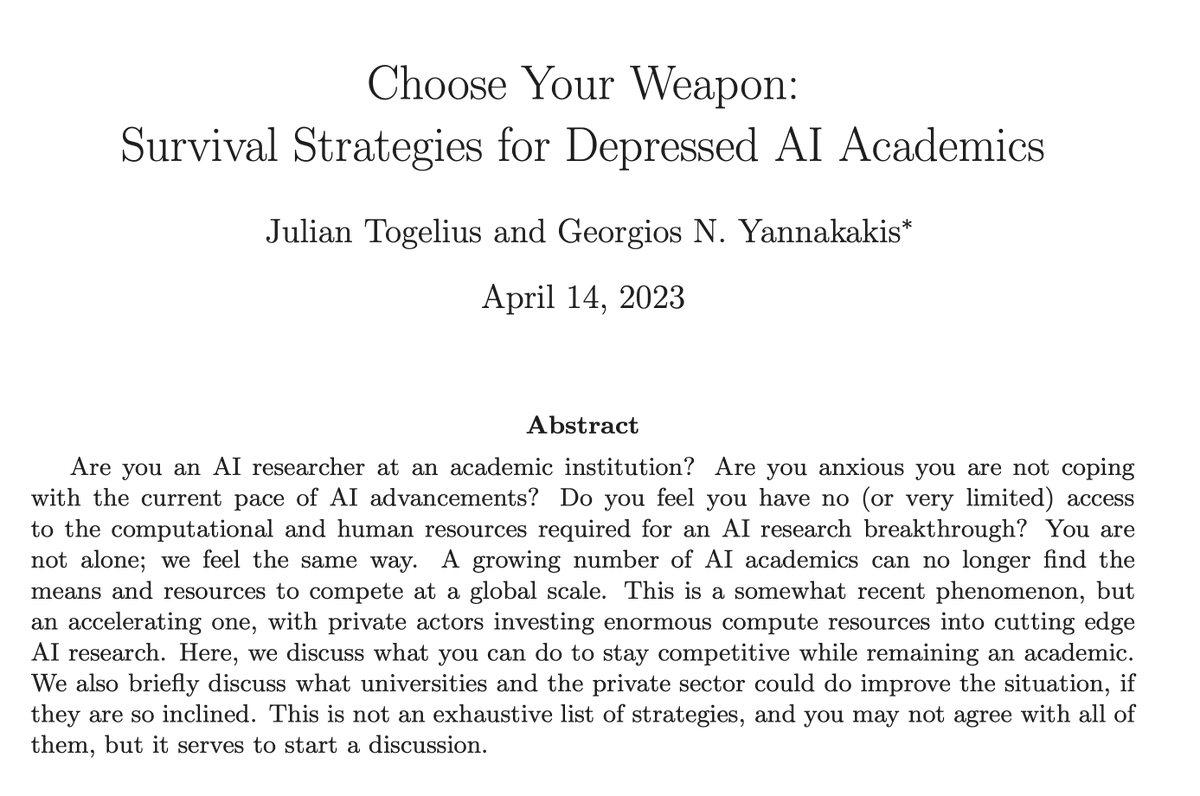
Not long ago, breakthroughs in AI research often came from lone academics or small teams using desktop hardware. These days, not so much. Are you anxious about how to stay competitive in AI as an academic?
@yannakakis and I wrote this piece for you:
https://t.co/BpXc2IeQZh
🚨🚨
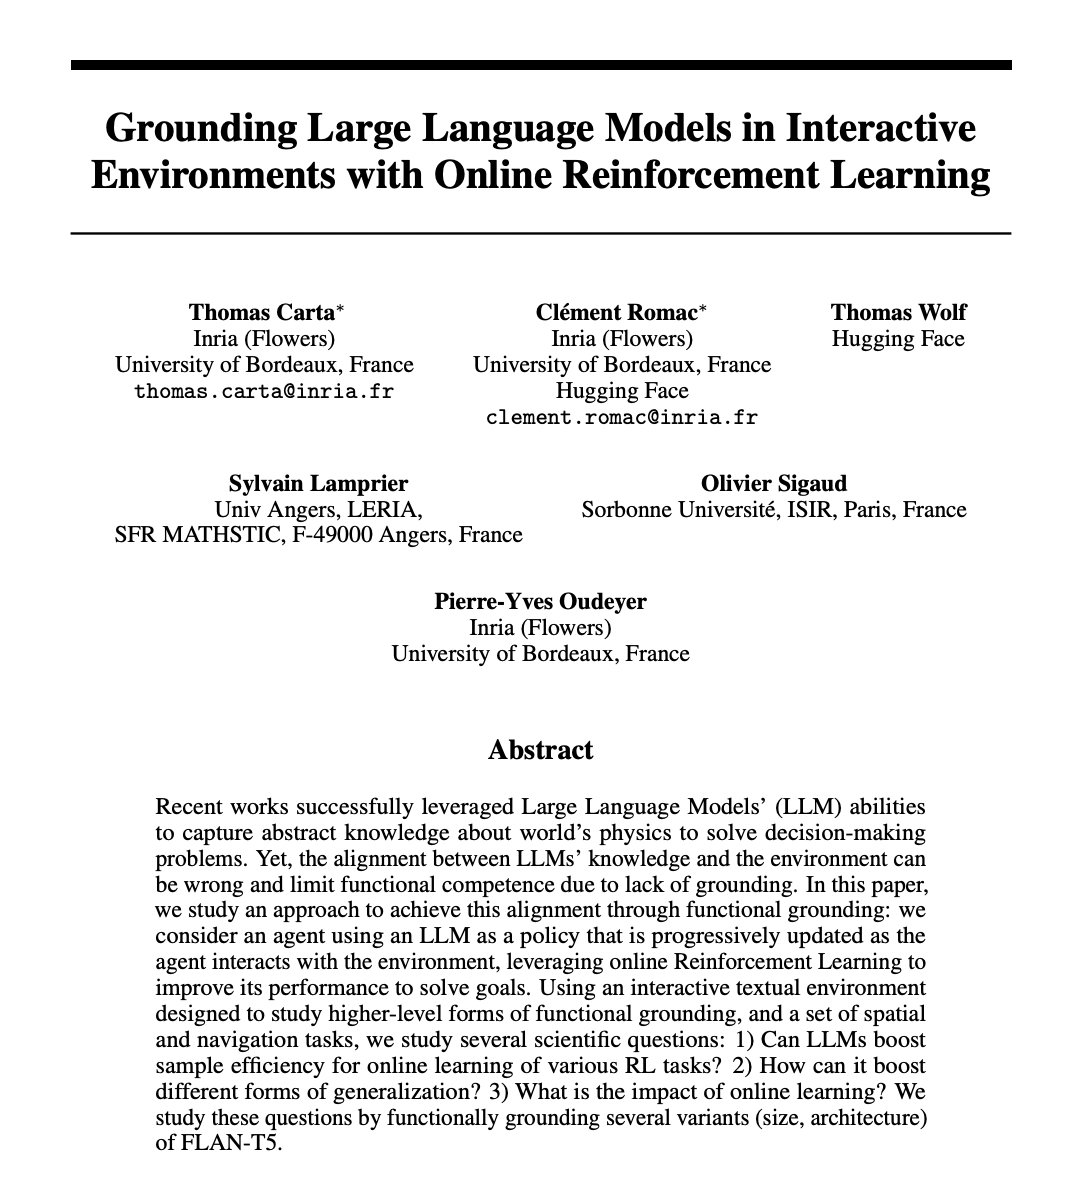
Large Language Models encode world knowledge that can benefit RL agents when solving decision-making problems (e.g. in robotics 🤖).
But what happens when their knowledge are wrong? 🎯
Can we align LLMs and ground their knowledge through interactions with online RL? 🕹
RLHF is suddenly all the rage since #ChatGPT
Probably the most knowledgable person in the world about RLHF who is also on the faculty job market is @rajammanabrolu. He made a RLHF toolkit and improved policy optimization for NLP.
You should hire him.
https://t.co/sZCGcI7ami
RL4LMs is one of the first open source RLHF libraries but it isn't "basically ChatGPT" or "production ready".
No open source repo is currently. Open source libs are an important prereq (reproduceability!)... but so is acknowledging limitations. 1/n
https://t.co/rk67tR3kVi
In 2022, I spent 17,715 hours training 8,220 models on @wandb! My #longestrun, ac7bf3e7e77e06d172aa6863a0c56266, trained for 48 hours. Here's its collector card, with an image generated by DALL·E 2 from @OpenAI: https://t.co/eHP3hqxdy3
In 2022, I spent 17,715 hours training 8,220 models on @wandb! My #longestrun, ac7bf3e7e77e06d172aa6863a0c56266, trained for 48 hours. Here's its collector card, with an image generated by DALL·E 2 from @OpenAI: https://t.co/eHP3hqxdy3
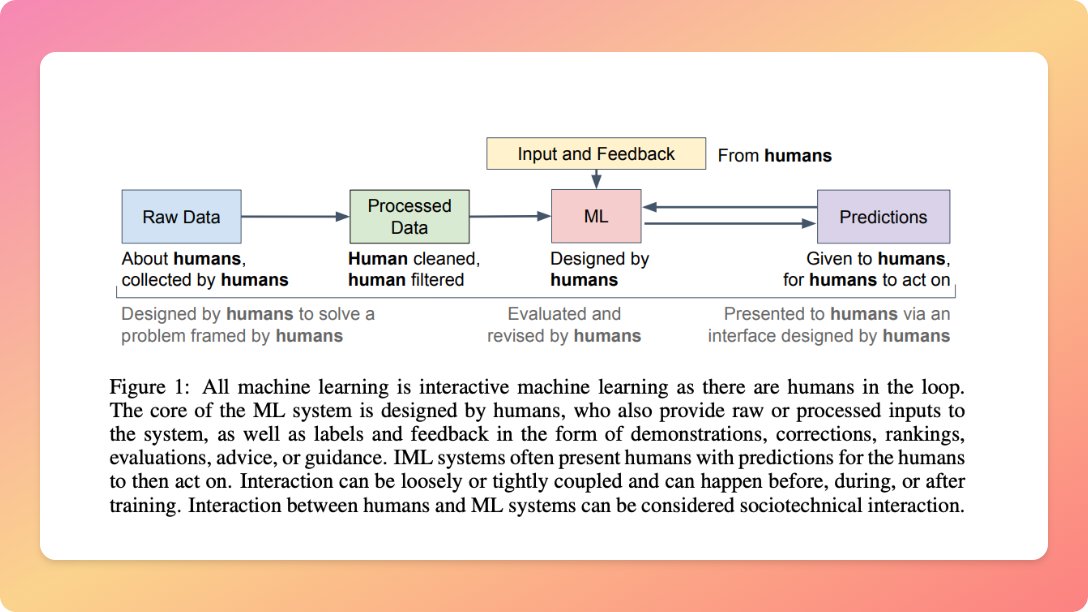
2023 will be the year of Interactive Machine Learning
So it is a good time to remember
➡️ ALL MACHINE LEARNING IS INTERACTIVE ⬅️
➡️ Why does this matter?
➡️ What can you do on your next AI / ML-powered project
A short 🧵 to start the year.
RL4LMs has 500 stars on GitHub! Thanks for the support for your one stop shop for all things RLHF!
3000+ expts over 7 NLP tasks, 4 RL algos, any Huggingface generative LM, 20+ metrics, human preference collection UIs, continual deployment, and more!
https://t.co/73rpjUeGtk
📍Introducing an AI Dungeon Master’s Guide🧙♂️, or how to make a #DnD DM dialogue agent trained with intents and theory of mind-inspired💭reinforcement learning.
Predicting how your players will react to you ahead of time makes for a better DM!
📃https://t.co/pIKnI20rqq
Our newest work on creating a dialogue agent able to act as a teacher and guide students towards a goal beneficial to them! Built using #dnd as a test be and our preference learning library RL4LMs!
https://t.co/73rpjTWxfc
Announcement time! I'm on the academic job market this cycle! Please reach out if I'm a good fit!
I make trustworthy and safe AI agents that communicate with language, build world models, and learn from human and environmental feedback. More: https://t.co/Fk8ynQbbbB