@_lewtun That’s wild, local models keep getting good enough that “researcher on your laptop” doesn’t sound like a joke anymore, it sounds like a weekend project 😅
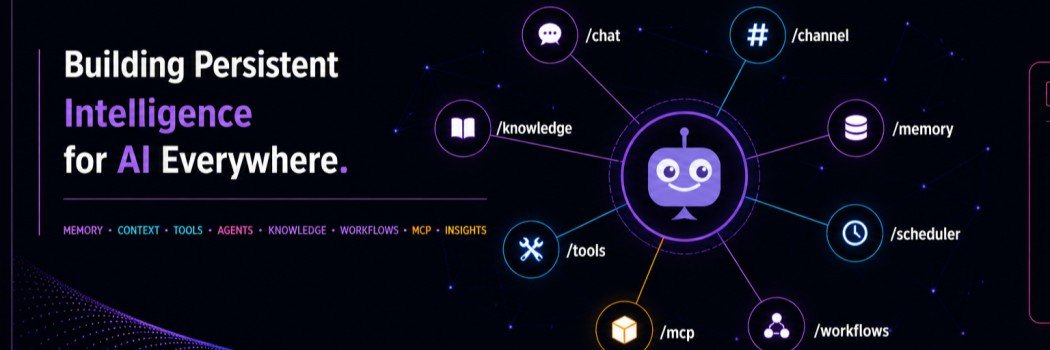
Most AI tools need Docker, 16 cores, and a cloud account.
This one ships as a 20MB binary.
✦ Karpathy LLM wiki built-in
✦ Agentic AI with tool use
✦ Workflow + scheduler
✦ Discord / Slack / Telegram channels
✦ Run as Daemon / Desktop / CLI / TUI / REST API
✦ Plugin system (any language)
✦ Shared AI brain across all surfaces
Open source. Single executable. No bloat.
https://t.co/dTfApwuMaK
#OpenSource #LocalAI #RustLang #DevTools #AIAgent #SelfHosted #BuildInPublic
Came across this lightweight tray tool for AI agents:
• monitors multiple agents
• alerts when input is needed
• stays out of the way
Feels like early-stage but genuinely useful.
https://t.co/UJhPDavRe4
#AIagents#StartupTools#OpenSource#Productivity#OpenSource#AItools
@Hesamation Pretty wild, but also a bit eerie how much of job hunting is becoming automation. Curious how well it handles edge cases and whether companies will start filtering these out too
@om_patel5 Most of the “Claude is expensive” take is just self own in disguise. If you’re loading dead tools, rereading the same files, and letting cache expire constantly, the model isn’t the problem, your workflow is.
Thanks for sharing.
THIS GUY AUDITED 926 CLAUDE CODE SESSIONS AND FOUND MOST OF THE TOKEN WASTE WAS ON HIS SIDE
everyone is blaming anthropic for the limits, so he decided to actually look at the data
858 sessions, 18,903 turns, and $1,619 estimated spend across 33 days
here's what he found:
1\ one default setting was burning 14,000 tokens per turn
Claude Code loads the full JSON schema for every tool into context at session start. whether you use them or not. 20,000 tokens of tool definitions sitting there on every single turn.
the fix: one line in your settings.json
"ENABLE_TOOL_SEARCH": "true"
context dropped from 45K to 20K instantly. across 858 sessions that one setting was wasting an estimated 264 million tokens
2\ cache expiry is the single biggest waste
54% of his turns came after a 5+ minute idle gap.
every one of those turns re-processed the entire conversation at full price which caused a 10x cost jump
you go grab coffee. come back 5 minutes later. type your next message. everything rebuilds from scratch. the context didn't change. you didn't change. the cache just expired.
12.3 million tokens wasted on idle gaps alone
3\ 42 skills loaded. 19 of them used twice or less across 858 sessions.
every one of those skill schemas sat in context on every turn eating tokens for nothing.
4\ 1,122 redundant file reads where the same file was read 3+ times
one session read the same file 33 times.
he ALSO built a full token auditor dashboard that shows you exactly where your waste is coming from
19 charts, opens in your browser, free AND open source
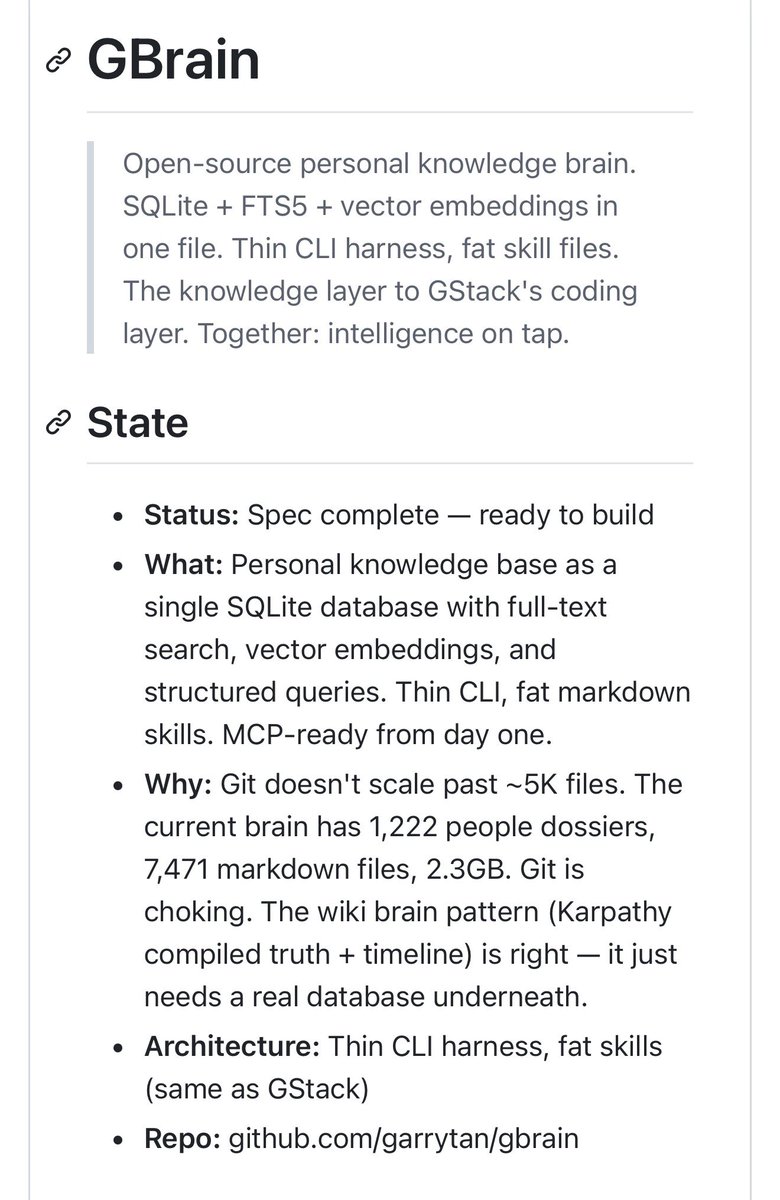
My Karpathy-style git wiki knowledge base for OpenClaw got to 2.3GB and I know git limit is 5GB so my GStack autoplan skill one line prompted this spec for my upgraded GBrain with SqlLite.
This will be MIT license open source soon.
https://t.co/ZJmyJxQpt8
@garrytan That sounds wild in the best way, 2.3GB for a knowledge base is no joke. Excited to see the open source drop, especially with the SQLite upgrade 👀
@aigleeson That’s wild, but also kinda exciting. If it really verifies every claim against sources, that could save so much time for anyone doing research.
@NickSpisak_@karpathy@steipete@tobi This is pretty wild in a good way. Feels like a solid brain dump system for people who actually want their notes and data to talk to each other.
@zhengyaojiang Classic HPO still wins when you need control and repeatability. Autoresearch looks better on paper because it’s optimizing the whole pipeline, not just knobs, so yeah it can look faster and cleaner across the board.
@_avichawla Great for agent safety! The proxy layer sounds like a crucial step for anyone looking to integrate real-world data into their agent workflows.