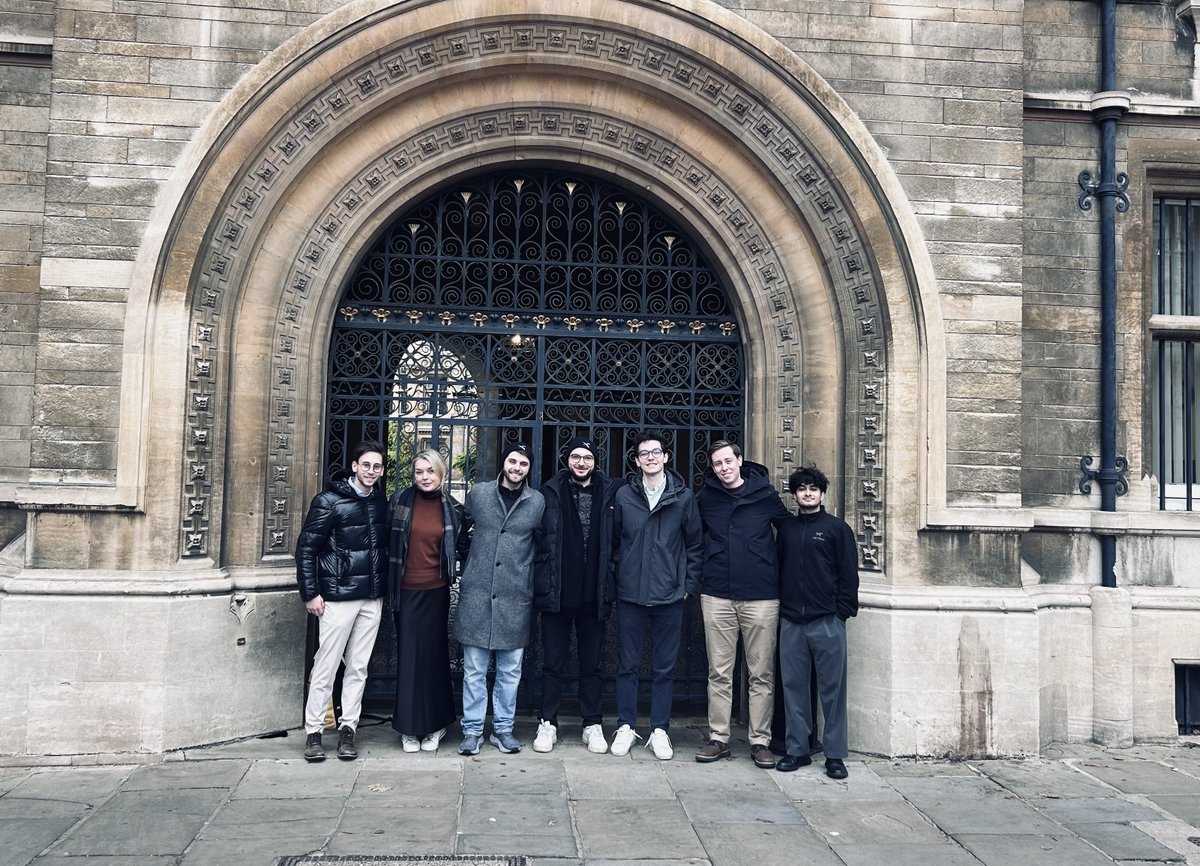
Meet the Parallax team! 🔍
Our founding team is gathering for the first time in London and Cambridge this week. We will kickstart our research activities and shape our agenda for bringing white-box belief auditing methods in the hands of AI evaluators.
It’s lovely to finally have everyone in one place!
i was diagnosed with thyroid cancer many years ago purely by chance, because i had to get blood work for my US green card application (thank you, USCIS!). i was in my mid-30’s and was reasonably healthy (or so i believed.) this was shocking and totally unpredictable news to me. thanks to the amazing team of clinicians at NYU Langone, i successfully went through a total thyroidectomy followed by radioactive iodine therapy. but, it was truly the most uncertain and confusing period of my life.
this is when i first realized that no one can opt out of healthcare. being sick isn’t what you choose to or choose not to. it is something that unpredictably happens to all of us at some point for one reason or another. this is why it is a healthcare system that we collectively build and use to support each other at the society level. because it must support everyone, the complexity of creating, maintaining and improving this system is a Herculean effort that calls for all the help in the world.
today, i am announcing @OrtetAI together with my dear co-founders, @keunwoochoi, @HenriDwyer, @elmanmansimov, @causalclaudia and Jeff, to lend our support to improving the health of each and every one of us. Ortet’s goal is to create a technological foundation that will enable health systems to deliver predictably better care to each and every patient. this will only be possible by working closely with all stakeholders in the broader ecosystem, which is enabled in part by Ortet’s close partnership with Thoreau.
Ortet is taking the very first step of a long journey ahead, and at the end of this journey, i strongly believe we would be able to say that Ortet had contributed to building better, more predictable healthcare and thus to improving health of each and every one of us.
see https://t.co/5H3Su81ewr for more!
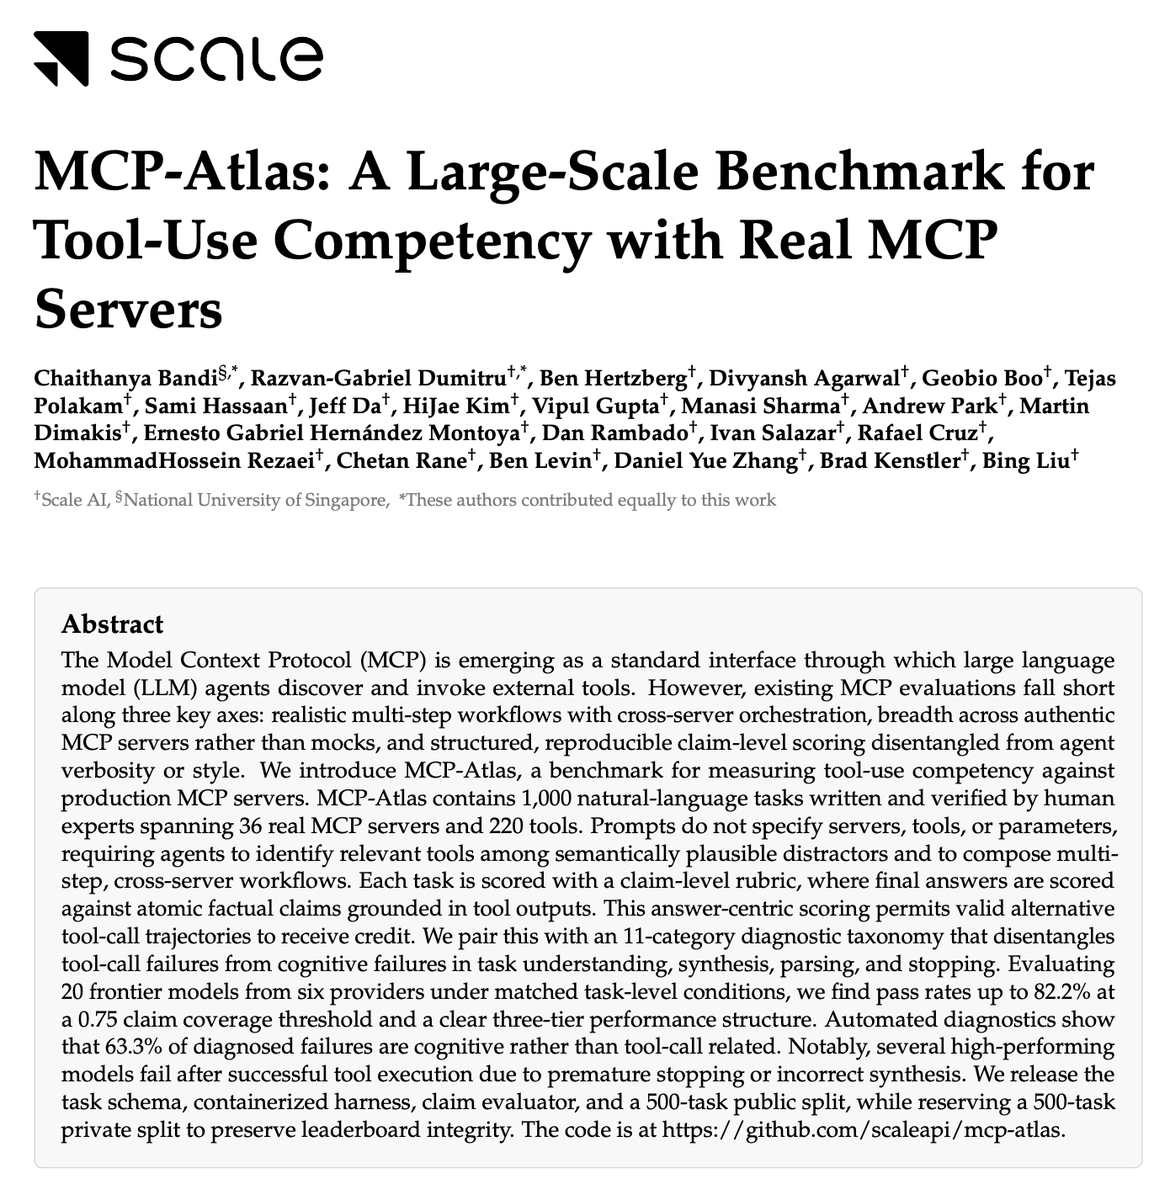
"MCP-Atlas: A Large-Scale Benchmark for Tool-Use Competency with Real MCP Servers" has been accepted to NeurIPS 2026!!
I had the privilege to be co-first author on the paper and to work with virtually all of the frontier labs to enable them to report numbers on our benchmark!
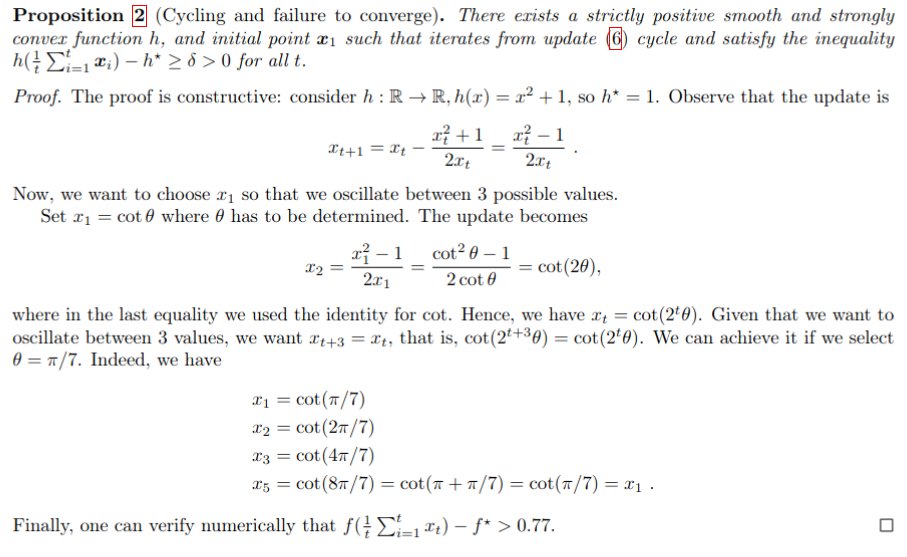
As promised, we put on Arxiv the proof we did with Gemini. https://t.co/rcHOKY5Mbj
This shows that the Polyak stepsize not only will not reach the optimum, but it can cycle, when used without the knowledge of f*.
Gemini failed when prompted directly ("Find an example where the best and average iterate do not converge"), but it worked when I gave more specific instructions ("Find a function and an initial point where it generates a cycle of length 3 and none of the iterates nor their average converge to the minimum").
As you can see, the proof is not difficult, but it is very creative: Rewriting the update with trigonometric functions and using their doubling formulas to show the cycle is not something I would have thought!
Look who we found hanging out in her new @StanfordEng Gates Computer Science office!
We’re truly delighted to welcome @YejinChoinka as a new @stanfordnlp faculty member, starting full-time in September. ❤️
https://t.co/7qOwMuVyiB
Exciting that @scale_AI is sponsoring Agent Workshop at CMU in April. Students and researchers who work on agents feel free to visit CMU to present your work! I will also be traveling to Pittsburgh to share my recent focuses on agents, both capability and safety.
coming to a NAACL 2025 near you! 🌞 Looking forward to discussing with folks in Albuquerque :)
The camera-ready is on arxiv now, with more models, more tasks, and more compared settings-- including results comparing ICL to full finetuning!
https://t.co/wiIIrRZFF3
Excited to share our work on RSQ — enhancing quantization by focusing on the most impactful tokens.
- Rotate, Scale, Quantize: delivering strong performance
- Dynamic, attention-based token importance drives better efficiency
- Results across LLaMA3, Mistral, Qwen-2.5, and more
Check out 🔥 EgoNormia: a benchmark for physical social norm understanding https://t.co/Wvml9m69C1
Can we really trust VLMs to make decisions that align with human norms? 👩⚖️ With EgoNormia, a 1800 ego-centric video 🥽 QA benchmark, we show that this is surprisingly challenging 🤖
🌐 https://t.co/3DJNHGMLwk
Our amazing team: MohammadHossein Rezaei* (U of A), Yicheng Fu* , Phil Cuvin* (U of T), @cjziems , @StevenyzZhang , @_Hao_Zhu
🔥 Excited to share EgoNormia! A benchmark for physical social norm understanding.
Can we really trust VLMs to make decisions that align with human norms?
🌐 Check out our website for the answer: https://t.co/Tii6BuY9ME
Proud to be part of this amazing team! 🚀
**Kindly consider sharing the post**
We are seeking opinions about the current quality of reviewing in *CL conferences. We (@emnlpmeeting PCs along with @ReviewAcl EiCs) are committed to improving the review quality. We are bringing a series of changes in the review process. Kindly consider filling out the form:
https://t.co/eQ7uKd3Cx2
@VioletNPeng
Our new paper in Findings of NAACL 2025, with Vlad Negru, @robert_nlp, @CameliaLemnaru, and Rodica Potolea, proposes a new, softer take on Natural Logic, where alignment is generated through text morphing. This yields robust performance cross domain. https://t.co/jqiqSl5ZwF
🧵 1/N) Excited to share our recent work at @scale_AI, "Jailbreaking to Jailbreak (J2)".😈 We present a novel LLM-as-red-teamer approach in which a human jailbreaks a refusal-trained LLM to make it willing to jailbreak itself or other LLMs. We refer to this process as constructing a J2 attacker. They are so good at attacking 🫨.
Our approach is straightforward without complex wiring between LLMs, serving as an improved baseline in this domain. We see that the current LLMs have gained non trivial capability at jailbreaking.
🔗 Demo & Paper: https://t.co/DSUtek596O
Is your CS dept worried about what academic research should be in the age of LLMs? Hire one of my lab members! Leshem Choshen (@LChoshen), Pratyusha Sharma (@pratyusha_PS) and Ekin Akyürek (@akyurekekin) are all on the job market with unique perspectives on the future of NLP: 🧵
🚀Big update: 4 new SEAL multilingual leaderboards are LIVE — Arabic, Chinese, Japanese, and Korean!
🌍 Arabic: Gemini 1.5 Pro (gemini-exp-1121) leads the pack
🏮 Chinese: Gemini 1.5 Pro (gemini-1.5-pro-exp-0827) holds the crown
💫 Japanese & Korean: o1-preview dominates
📊 See how your models stack up: https://t.co/NoBUJ7iLP0
SEAL Visual-Understanding Leaderboard Launch 🏆
Today, we’re introducing VISTA—a new rubric-based visual task assessment benchmark that pushes beyond simple Q&A.
The leading models achieve under 40% on this eval, compared to a human baseline of ~55.4%. This highlights that multimodal reasoning remains challenging for current LLMs.