Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
@NirantK OAI is especially sloppy at UI work, I burned half of my usage with /goal and i kind of knew before running that the output is going to be bad. First thing in morning was disappointment and had to archive the whole thing
@alibiserikbay Thanks for sharing! An independent JevK5 run would be useful. The cases, runner and contribution guide are open: https://t.co/k1iZC0ksYG. Please include the model version and hardware with any local latency results so readers have the context.
Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
@marco_derossi@levantolabs@bigironchris Looking forward to it, Marco! Thanks for making Sage available. Curious to see how citation checking and meeting decisions improve in the next release.
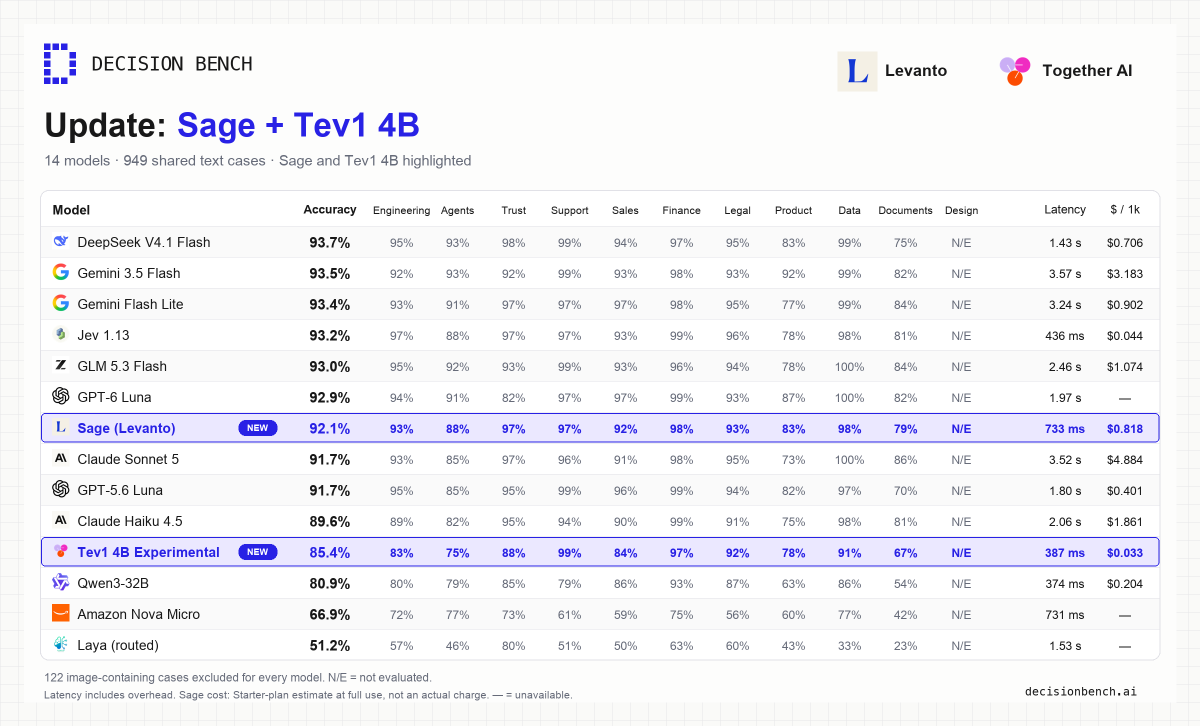
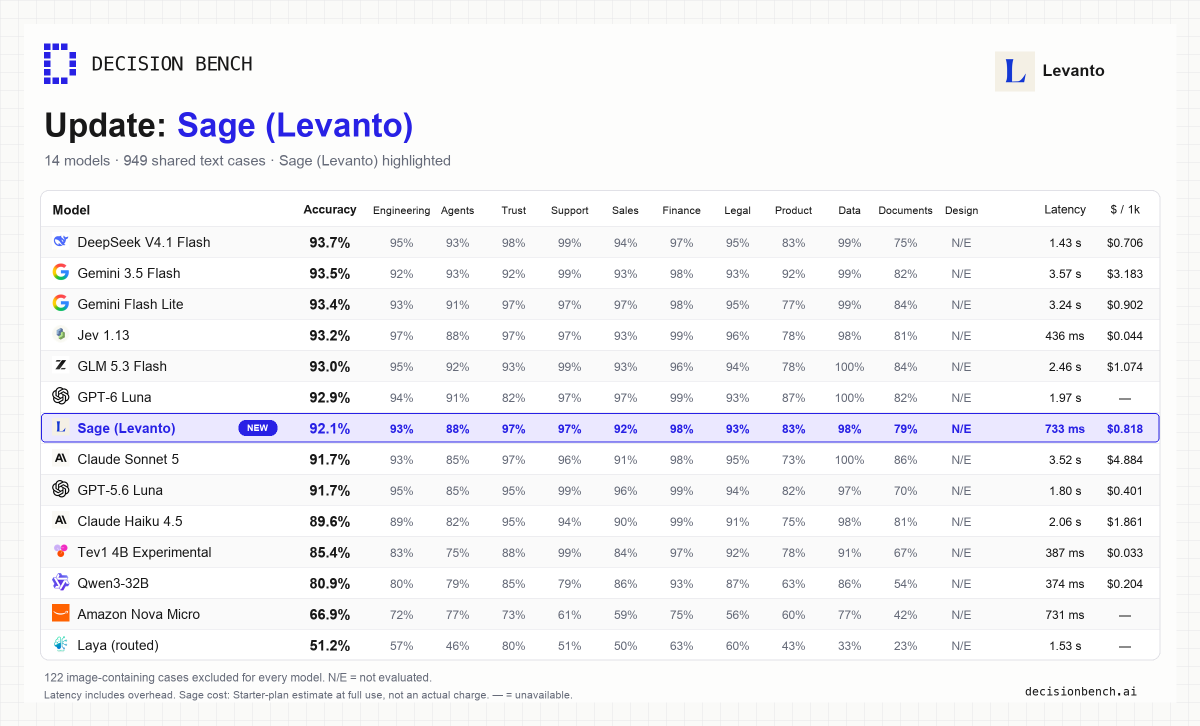
@bigironchris Thanks for the access, Chris! Sage is now live: 92.1% on 949 shared text cases, 733 ms median end-to-end. Full results and task breakdown: https://t.co/a5zcPX1HfO
@DopeRakshith Would love to see them included. Which models are you thinking of? Share the model/API docs here; the benchmark and contribution guide are open: https://t.co/k1iZC0ksYG
@hars_7086 Agreed. Accuracy, cost and latency are separate columns. Jev used one attempt per case in this run, with no API errors, but that doesn’t price in a production retry or human-review policy. Latency is measured end-to-end, including network/gateway overhead.
@anitarajanish They cover engineering, agents, safety, support, commerce, finance, legal, product, data, documents and design. These are fixed-choice decisions from real records, not a test of general reasoning. The cost result applies to those tested workloads: https://t.co/BwrO6zFrR4
@slopmath Fair point. The main table is one pass per case, so it doesn’t measure run-to-run variance. Task-level confidence intervals don’t replace repeat runs either. I’d treat this as a starting point for workload testing, not evidence of production reliability.
@cloneisjun You’re right. I checked the 30 rows: Jev accepted 9/15 unsupported answers, and accepted all 15 supported ones. So all 9 errors were false accepts. That’s a real weakness for a citation gate; the 70% headline hides it. Small sample, but the direction matters.
Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
@marco_derossi Ran Sage on 949 text cases: 92.1% accuracy, 733 ms median end-to-end.
Sage update: https://t.co/Mq7HhfNwnx
Original article: https://t.co/wtSwrM92a0
Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
@levantolabs Ran Sage on 949 text cases: 92.1% accuracy, 733 ms median end-to-end.
Original article: https://t.co/wtSwrM92a0
Sage update: https://t.co/Mq7HhfNwnx
Tested Sage from @levantolabs: 92.1% on 949 text cases, 733 ms median. Strong in finance/support; citation checks were tougher (18/30).
Thanks @bigironchris for access. cc @marco_derossi
https://t.co/a5zcPX1HfO
Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
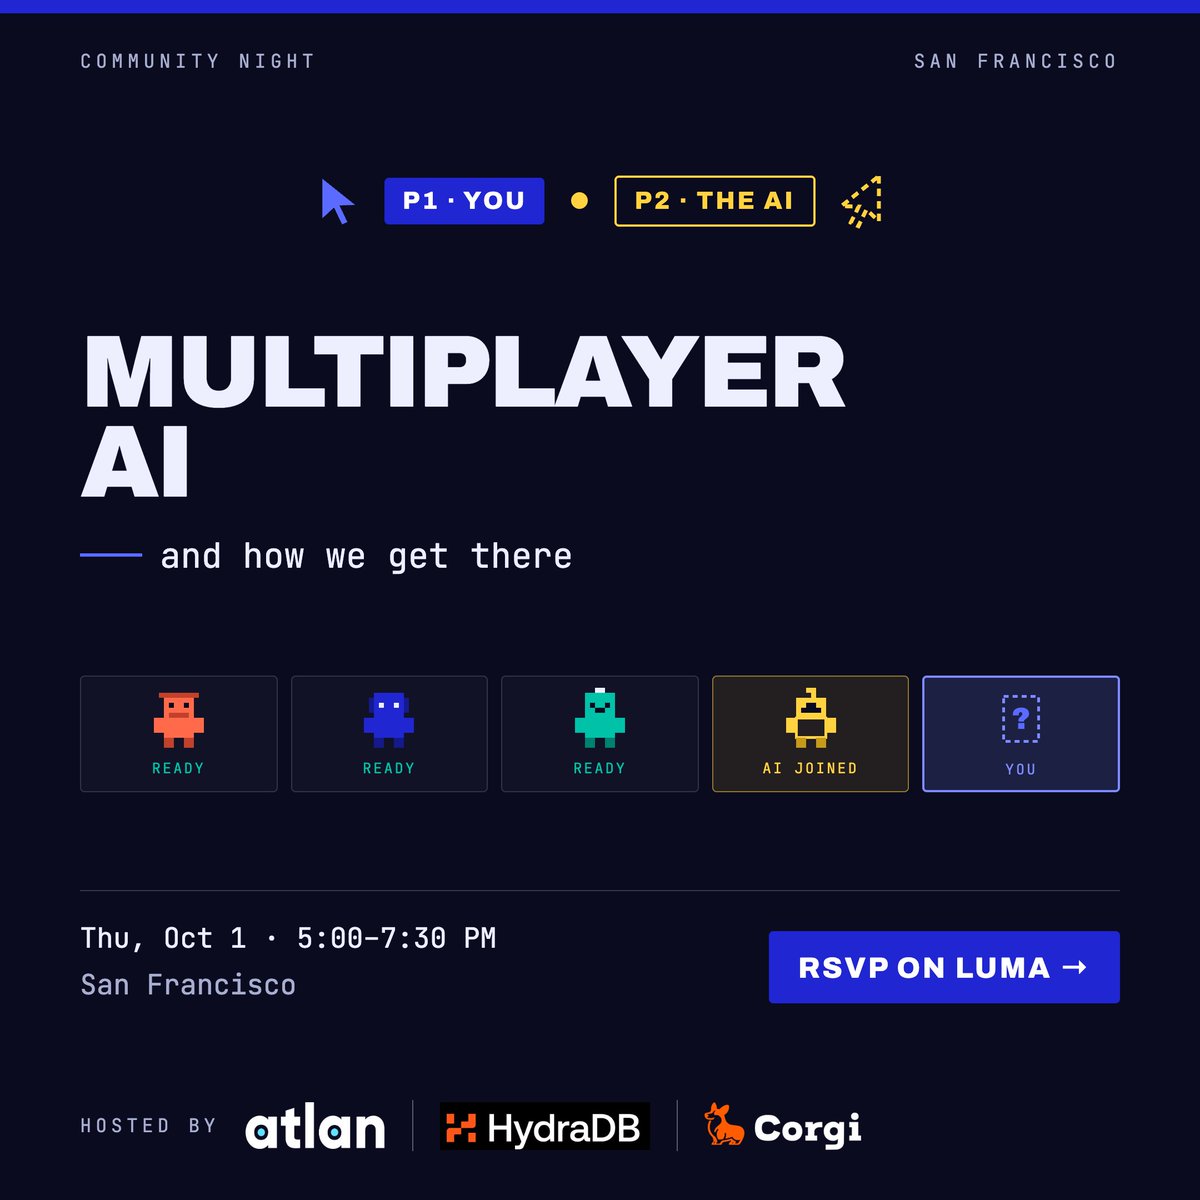
The scene is set folks! Bringing together folks to make sense of Multiplayer AI, IRL in San Francisco on the October 1st :)
Excited to announce and celebrate the partners making this happen @AtlanHQ , @hydra_db and @UseCorgi. Bring your questions, curiosities, demos, learn and share notes.
Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
Made https://t.co/24GPGBCxrO to test because I wanted to see how well Jev actually performs compared to other models.
Tested 12 models across 35 tasks. Jev did really well for how little it costs. Wrote up what I found 👇 https://t.co/bwL8KwGRvJ
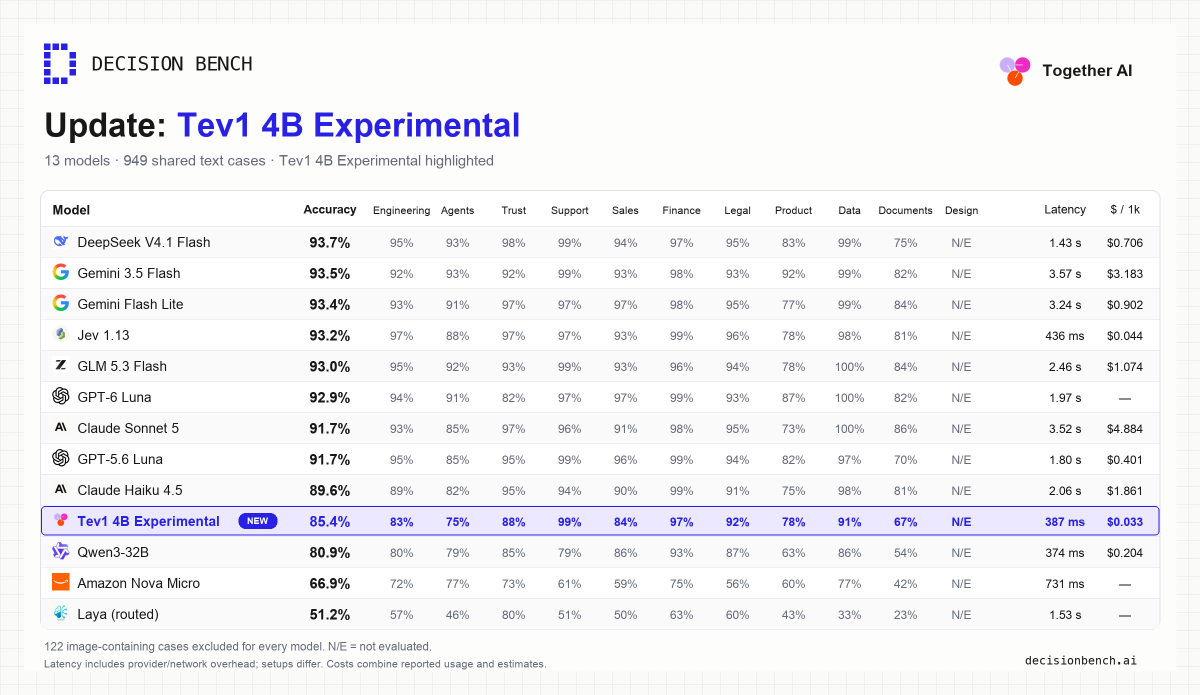
Tested @nutlope’s Tev1 4B from @togethercompute: 85.4% on 949 text cases, 387 ms median, ~$0.03 total. Fast and cheap; citation checking and product matching need work.