Following the discovery that eight eMudhra intermediate certificates use weak keys, Cloudflare is deploying mitigations and releasing client updates. We explain the impact, our response, and what customers and developers should do next. https://t.co/lYGxHb3PHS
Introducing EmbeddingGemma 2, a new open multimodal model that sets the standard for on-device efficiency.
- our first open, natively multimodal embedding model
- handles text, code, image, video, and audio tasks within a lightweight, modular 740M parameter form factor
- ideal for offline, privacy-first RAG when paired with Gemma 4
- outperforms some specialist models more than twice its size
Weights available now on Hugging Face.
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
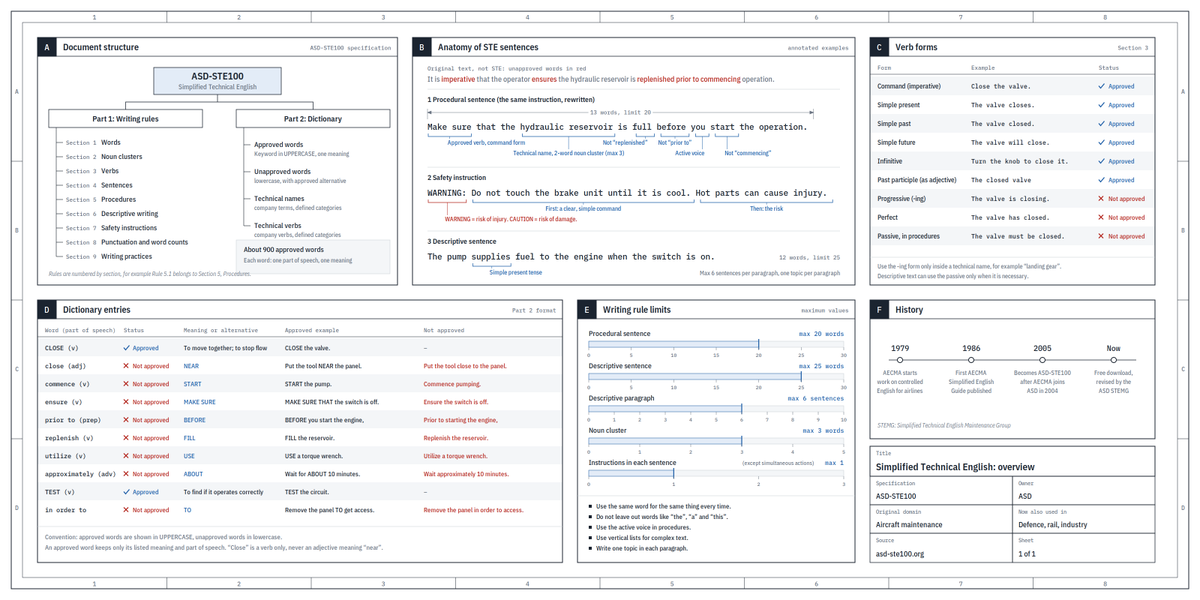
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
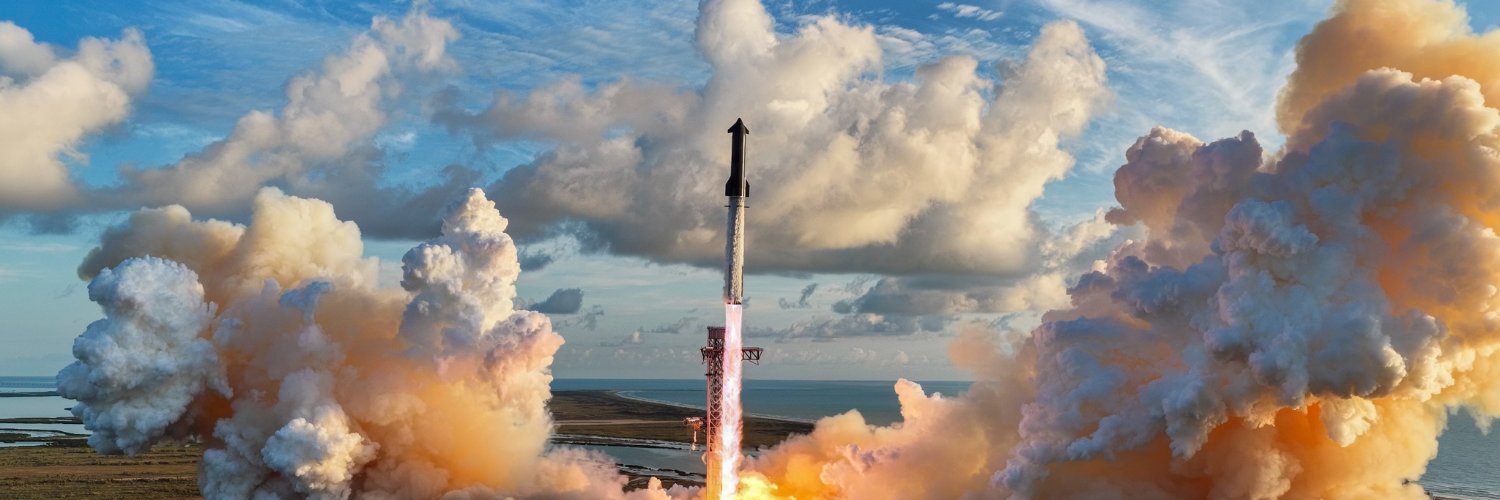
Starship’s 14th flight is set to launch on Monday, Sept 28. The 75-minute launch window opens at 7:15 a.m. CT. Live coverage of the mission starts ~35 minutes before launch → https://t.co/uQKQvgaTmJ
We're publishing our most detailed threat intelligence report to date.
It covers how people tried to misuse Claude—for cyberattacks, influence operations, surveillance, biology, and building weapons—and how we found and stopped them.
We disrupted every operation in the report, and used the lessons from them to strengthen our safeguards. Where appropriate, we also shared what we found with authorities and other AI companies.
These cases are not typical: we’re highlighting some of the most sophisticated misuse we’ve seen. But they’re especially important to discuss, because they show us where AI misuse is headed, where our safeguards work, and where they need to improve.
We’re publishing this report so others can spot the same activity on their own platforms, and so we can give the public a clearer view of how emerging threats develop.
Read the report: https://t.co/0EJUnYEgfz
Exciting day for NVIDIA and @huggingface.
Open models strengthen safety and cybersecurity, accelerate innovation and diffusion, and enable sovereignty. They allow every developer, startup, university, industry and country to build with, customize and benefit from AI.
Thank you @ClementDelangue for coming to me.
NVIDIA is going to be a great home for Hugging Face, its community and the future of open models. 🤗
https://t.co/q8Om2Xc5ye