Meet… Arena Conversations. @petergostev sits down with @poolsideai researchers,Connor Adams and Aalhad Patankar, to discuss how they’re building frontier open coding models.
Episode drops today at 10am PT on our YouTube.
They dig into Poolside's Laguna model family, why the team publishes full trajectories (not just benchmark scores) for anyone to audit, and how "experiments" at Poolside range from data mixes to harness design to reward-tuning decisions run tens of thousands of times a day.
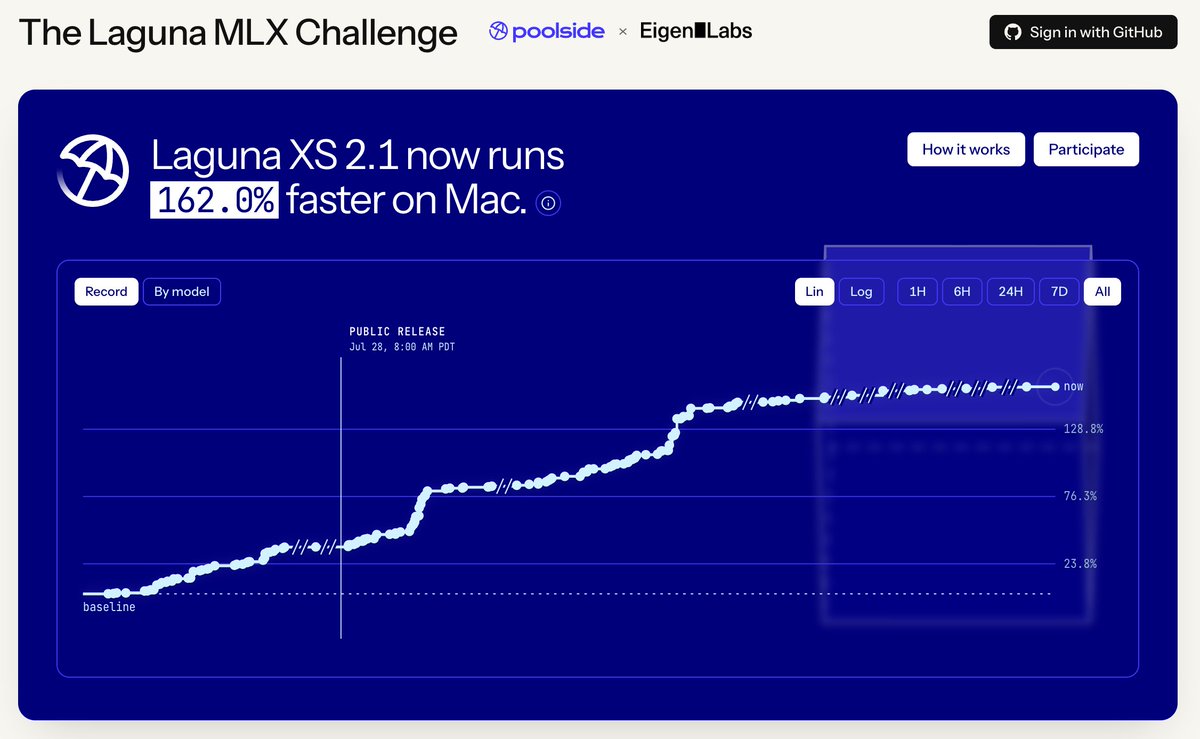
We started the https://t.co/38dsNYD3nP challenge with @poolsideai with one key question. How much faster can the community make Laguna XS 2.1 run on a Mac?
The answer so far has been 2.6x faster.
Nearly 1,800 submissions and 35 solvers later, the challenge comes to a close today.
And there’s one more thing. One of the solvers is taking home a Mac Mini M4 24GB!
Winner below ↓
One way to fall behind in data science has nothing to do with models or tools. It's struggling to explain your work.
In Writing for Developers, @c_a_dunlop and @sarna_dev share practical techniques for communicating technical ideas with clarity.
Hear Cynthia on Value Driven Data Science: https://t.co/nCck32HdAm
Book: https://t.co/zGHNmIgOQm
July in https://t.co/8mJ7fPbtDc 👇
Tailscale didn’t stop the Hugging Face intrusion // @apenwarr, @Tailscale
Finding bugs in Raft implementations // TW Lim, Rohan Padhye, Marco Primi, @AntithesisHQ
I'm sorry, Dave // @dhh
Watching Go’s new garbage collector move through the heap // @eatonphil, @theconsensusdev
Running unmodified Doom in the SQLite bytecode language // @glcst, @tursodatabase
My thoughts on the Bun Rust rewrite // Andrew Kelley
Performance per dollar is getting faster and cheaper // Ian Ye, @wafer_ai
We just crossed 10T tokens served across all our models in less than 3 months!
Laguna S 2.1 is pushing new highs at ~300B tokens a day, and has processed +2T in the 14 days since release.
That’s across @OpenRouter@vercel and our direct API.
Really good to see demand for open models keep accelerating.