ML4 is now open-weight! Frontier capabilities on code agents & cyber, way more efficient and compact than its Preview version three weeks ago (!) and cherry on the cake: technical report telling its epic backstory. Check it out: https://t.co/TOOfN9Pob2
Today, we release the weights of a new and improved Le Chonk, advancing the open frontier for agentic coding and cybersecurity.
💻 Built to build: Le Chonk ranks #1 on @cognition’s FrontierCode among open models, and sets a new benchmark for Pareto efficiency on @artificialanalysis.
🛡 Built to defend: State-of-the-art in cyberdefense, put through the paces by the world's leading cyber vendors, including @CrowdStrike, @cloudflare, @rubrik, @zscaler, and others.
Built for sovereignty: Make it yours. Download the weights on @huggingface , customize it with Mistral Forge, and deploy it wherever you need it.
Read more from our team and customers 👇:
Le Chonk is out of the bag 🐈
We're throwing Chonky Parties in our SF, NYC and London offices to celebrate the launch!
You can expect some Champagne 🍾, food, good music, and to meet the team behind our latest release.
📍 SF: https://t.co/p7pwxLaxo8
📍 London: https://t.co/xb7hear8pn
📍 NYC: https://t.co/rb4k7CGIBj
Please sign up! Registration is mandatory.
Join us at one of our events :
📍 SF: https://t.co/BSyC1VopX2
📍 London: https://t.co/YkAUW4Em5u
📍 NYC: https://t.co/JWTByNNNhY
We are almost at capacity, so make sure to secure your spot !
This Thursday, we are hosting events at our SF, NYC, and London offices to celebrate the launch of ML4 !
We're growing our teams across all three locations, as well as in Paris, Warsaw, Zurich, and Montreal, where we recently opened a new office.
If you believe the future of AI should be open, that scientific breakthroughs should be shared, and that everyone should benefit from frontier intelligence, come build that future with us !
At @MistralAI, we're throwing a party to celebrate ML4!
Come see what we've been building. If you've been looking for your next challenge, this is your moment to chat with the team and find out what we're working on!
https://t.co/2aWyhotF03
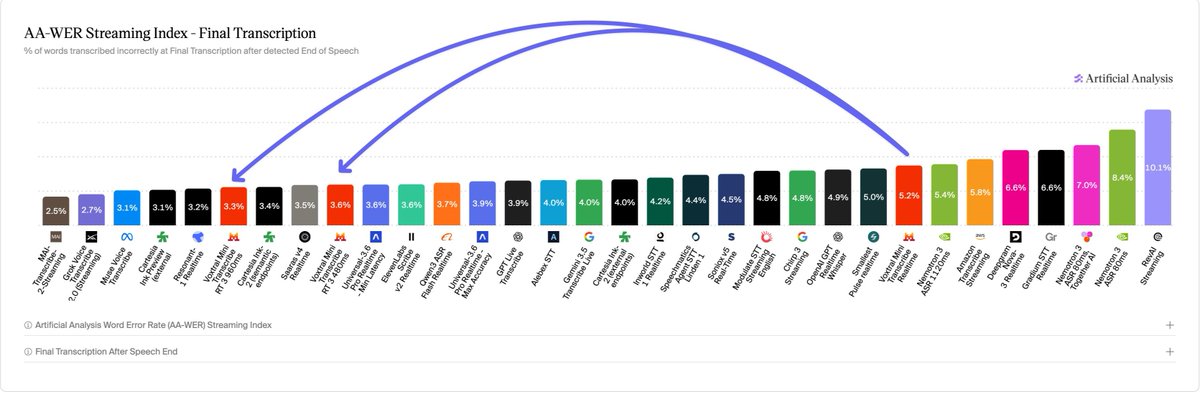
🎙️ Introducing Voxtral 3 !
A new family of SOTA speech models:
ASR: Mini & Small for batch transcription, plus real-time streaming
TTS: expressive, multilingual speech, batch + streaming
Voice agent SDK: low-latency conversations + tool calling
Available via API or on your own infrastructure !
Meet Mistral Large 4, aka Le Chonk.
• 1T parameters, natively multimodal. 49B active.
It is the best open weights model from US or Europe on aggregated benchmarks.
• State-of-the-art on critical workloads, including cyber defense, manufacturing and finance and it surpasses closed frontier models on visual grounding.
• Forged in Europe end-to-end and is deployable from Europe via our own Mistral Cloud infrastructure.
• Available to all via API today. Working with cybersecurity partners privately.
Open weights release end of October.
@trq212 I would switch away from claude if you removed plan mode. This is my exclusive mode to work in and get the details absolutely right before executing.
Big announcement from @MistralAI today:
⚡ European Compute Units
🌍 Regional inference
🎯 Third-party model support starting with GLM 5.2
@MistralAI is bringing together the inference infrastructure, open models, and long-term commitments Europe needs to control its AI future, and setting a roadmap for the world. More in the blog 👇
@aman2304 Tbh, I never saw coding Twitter so split as I've seen math Twitter. I think it's because fundamental difference in the of the nature of the folks.
Sub-agents in (latent) space!
We’ve been working on a side project.
As far as I know, this is the first massively multiplayer, completely LLM-driven game. Come play Gradient Bang with us. See if you can catch me on the leaderboard.
This whole thing started because I wanted to explore a bunch of things I’m currently obsessed with, in an application of non-trivial size, that felt both new and old at the same time.
So … a retro-style space trading game built entirely around interacting with and managing multiple LLMs. Factorio, but instead of clicking, you cajole your ship AI into tasking other AIs to do things for you.
Some of the things we’ve been thinking about as we hack on Gradient Bang:
- Sub-agent orchestration
- Partial context sharing between multiple LLM inference loops
- Managing very long contexts, and episodic memory across user sessions
- World events and large volumes of structured data input as part of human/agent conversations
- Dynamic user interfaces, driven/created on the fly by LLMs
- And, of course, voice as primary input
If you’ve been building coding harnesses, or writing Open Claw agents, or doing pretty much anything that pushes the boundaries of AI-native development these days, you’re probably thinking about these things too!
This is all built with @pipecat_ai, the back end is @supabase, the React front end is deployed to @vercel, and all the code is open source.
I gave a talk at the EleutherAI ML Performance Reading Group on speculative decoding for LLM inference!
Covers SpecDecode → Medusa → EAGLE (1/2/3), with a focus on systems tradeoffs: acceptance rates, verification cost, batching, and KV-cache behavior.
TIL modern spec decoding gets much more complicated than I realized … link to eleuther ai ML perf reading group for anyone interested: https://t.co/mIWjAD2O1c it covers Medusa, Eagle 1/2/3, etc
My paper “Scalable GPU-Accelerated Euler Characteristic Curves” has been accepted at the NeurReps Workshop at NeurIPS 2025!
It introduces optimized CUDA kernels (up to 2000× faster) for ECC & a differentiable PyTorch layer for geometric learning.
Paper: https://t.co/wJUI5Rm1eo