Made the call: M5 Ultra Mac Studio with 512GB once that config ships (Apple says late October).
It won't beat a GPU cluster. That's not the point. Nobody can halve my plan overnight or decide which model I'm allowed to run.
Real numbers once it's on my desk.
Aleph Alpha's Kolibri has 78B parameters, but only 3.46B are active per token.
Each token touches about 4% of the weights. All ~78GB still has to sit in memory.
That's the workload I'm planning the 512GB Mac Studio for. Apache 2.0, so I can test it once it's here.
https://t.co/9BsjR4AUaA
@sudoingX Already halfway there. My 4080 runs Gemma 4 12B at 71 tok/s, the limit is 16GB of VRAM.
What pushed me was a $200 plan dropping to half the allowance for the same price.
Next step is a 512GB Mac Studio once Apple ships that config.
Apple is tightening Full Disk Access on the Mac and names AI agents as a reason.
Local doesn't get a pass. An agent on your own box with that permission can read your mail, messages and browser history too.
Worth checking: System Settings, Privacy & Security, Full Disk Access.
The firmware is open source. The model doing the thinking still sits behind an API token from Meta.
Fun to build. But if that token ever stops working, what's left on your desk? https://t.co/DUA3LlCiMS
🚨 side project alert 🚨
Announcing Muse Gadgets, an open source ESP32 firmware and Linux sdk so that you can make hardware devices that work with Muse.
Grab an API token from https://t.co/Q0dE0cYnCs and point your favorite coding agent at the github repo to build your own peripherals for Muse.
@VictorTaelin Your chart makes the price easy to judge. Opus 5.5 goes from 84 to 266 t/s at medium, and on the API fast mode costs $8/$40 per MTok instead of $4/$20.
About 3x the speed for 2x the price. Did you notice any quality difference between fast and normal?
@NXT4EU The model card puts a number on that: 85.6% on RGB Negative, the test where the answer isn't in the documents. So roughly 1 in 7 times it still answers anyway.
With Apache 2.0 weights you can at least run that test on your own documents instead of taking the number on faith.
PewDiePie's Ajax is a fine-tune of Qwen 3.5 9B.
I ran that base model on my RTX 4080 this week: 84 tok/s, 6.9 GB of VRAM at Q4.
The weights aren't on Hugging Face yet. When they land, a gaming card is enough to try it.
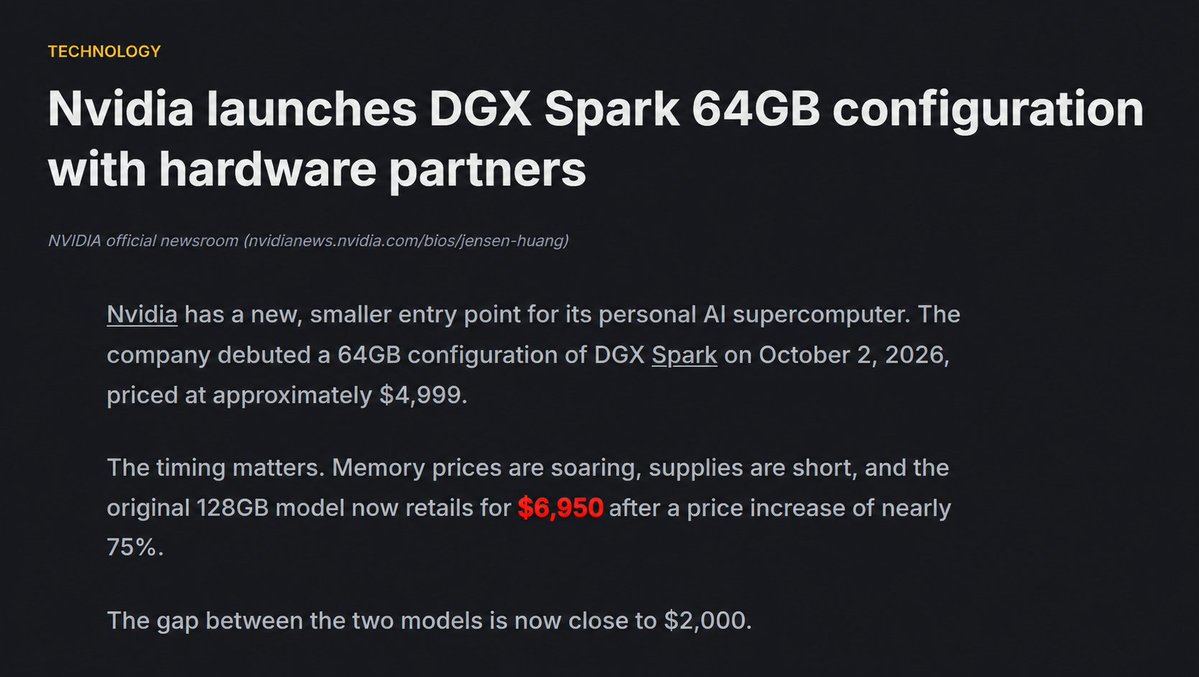
A year ago the 128GB DGX Spark launched at $3,999.
NVIDIA's store now lists it at $6,950. The new 64GB starts at $4,999.
Next to a $200/month AI plan, break-even went from 20 months to 35.
Would you still buy at that price, or rent until memory gets cheaper?
https://t.co/5RMTd1fDcf
@exolabs The Spark-prefill, Mac-decode split is the part that matters most to me, since I'm planning a 512GB M5 Ultra.
Does the prefill box need the full weights too? Then today's 64GB Spark caps that setup at models far smaller than the Mac can hold.
@natolambert@trillium_labs Intermediate checkpoints and the failed runs are what almost nobody publishes. Most open releases only show the run that worked.
With checkpoints, anyone with a gaming GPU can see where a small model's behavior shifted. Which base model do the first recipes start from?
Road to 512GB #1: the baseline.
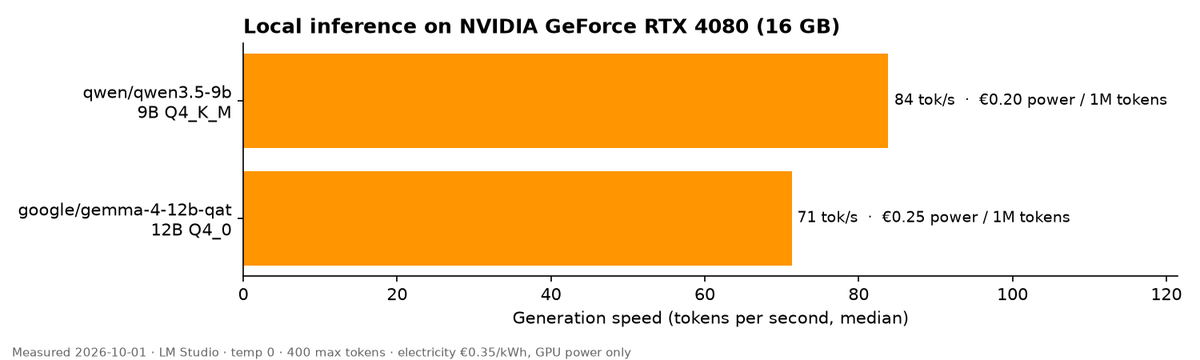
Before the Mac Studio shows up, I measured what I already have. RTX 4080 with 16GB, LM Studio, median of 3 runs.
Qwen 3.5 9B: 84 tok/s
Gemma 4 12B: 71 tok/s
About €0.20 to €0.25 per 1M tokens (GPU power only, €0.35/kWh).
Fast enough for small models. The 16GB is the wall. Same tests again once the 512GB box is on my desk. https://t.co/rtDPuGhaIL
Made the call: M5 Ultra Mac Studio with 512GB once that config ships (Apple says late October).
It won't beat a GPU cluster. That's not the point. Nobody can halve my plan overnight or decide which model I'm allowed to run.
Real numbers once it's on my desk.
Fair apology. It also shows who owns the meter: one post and every paid account gets its limits reset.
The only meter on my own GPU is the power bill. https://t.co/RKO9WNL8fV
Global reset landing tomorrow 10am PST for all paid ChatGPT accounts. Apologies for the slow start with GPT-6.1 Sol, it's now back to running at expected speeds after the massive load spike in the first two days.
@0xSero@MiaAI_lab DeepSeek's own API sells V4.1 Flash output at $0.60 per million off-peak. A 3090 + DDR4 box pulling ~500 W at German power prices needs around 90 tok/s just to match that on electricity. What decode speed are you seeing?
@matthewmillerai The 40% is the list price. Cache reads are $0.25 per million on Fable 5.1 vs $0.20 on Opus 5.5, and a long agent session is mostly cache reads. So the gap you actually feel there is mostly the $50 vs $20 output.
Claude for Government went GA yesterday. No seat fees. Agencies prepay usage with a hard cap, so spend can't exceed what they budgeted.
That's the billing model every consumer plan should have.
What we get instead is a fixed price and a usage limit the vendor can move.
Perplexity put its decision model on Hugging Face under Apache 2.0 and sells the same model at 4 cents per million input tokens, output free.
Cloudflare did the same with Clef a few hours earlier. The small Clef is built on Qwen 3.5 9B, which takes about 7GB of VRAM on my RTX 4080 at 4-bit.
At 4 cents a million, would you still run it yourself? https://t.co/D00RluWBVP
We’re open sourcing a state of the art multimodal Decision Model, pplx-decider-27b, and are offering it in a new Decisions API at 4 cents per million input tokens and free output tokens. We intend to bring down the price even further over the coming days. Enjoy!
@bridgebench Add one open-weights model you run yourself from a fixed file, as a control.
If that one also moves between 90% and 110%, you know how much of the band is your harness and not the provider.