Made the call: M5 Ultra Mac Studio with 512GB once that config ships (Apple says late October).
It won't beat a GPU cluster. That's not the point. Nobody can halve my plan overnight or decide which model I'm allowed to run.
Real numbers once it's on my desk.
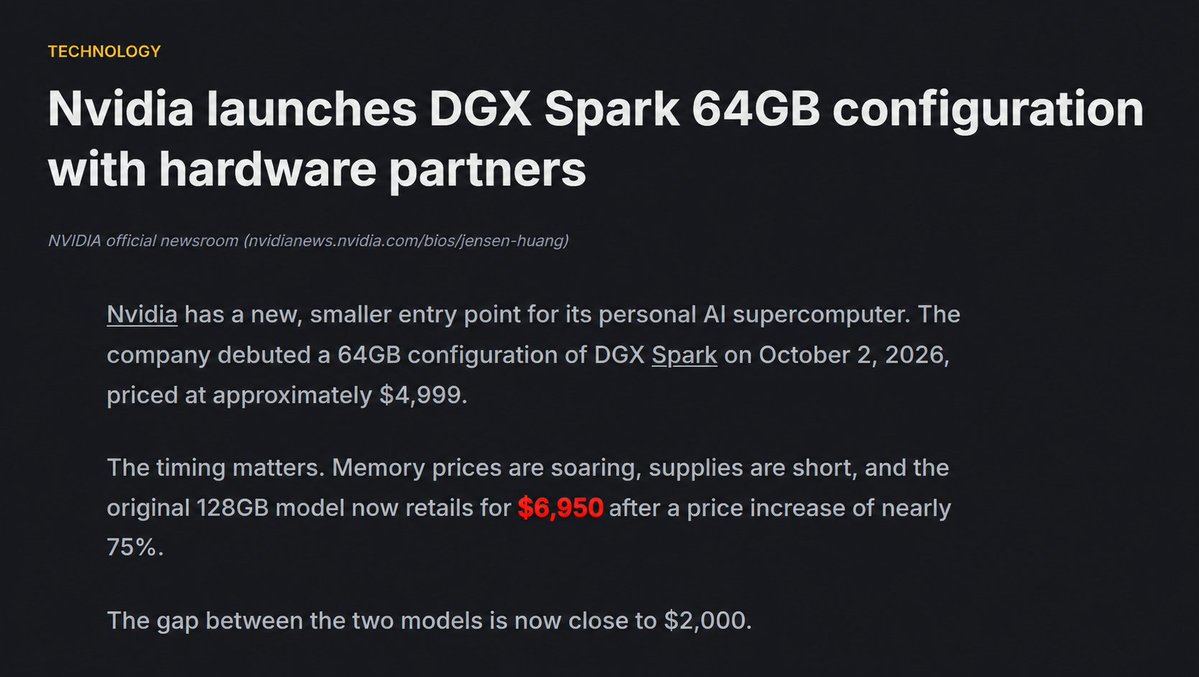
A year ago the 128GB DGX Spark launched at $3,999.
NVIDIA's store now lists it at $6,950. The new 64GB starts at $4,999.
Next to a $200/month AI plan, break-even went from 20 months to 35.
Would you still buy at that price, or rent until memory gets cheaper?
https://t.co/5RMTd1fDcf
@exolabs The Spark-prefill, Mac-decode split is the part that matters most to me, since I'm planning a 512GB M5 Ultra.
Does the prefill box need the full weights too? Then today's 64GB Spark caps that setup at models far smaller than the Mac can hold.
@natolambert@trillium_labs Intermediate checkpoints and the failed runs are what almost nobody publishes. Most open releases only show the run that worked.
With checkpoints, anyone with a gaming GPU can see where a small model's behavior shifted. Which base model do the first recipes start from?
Road to 512GB #1: the baseline.
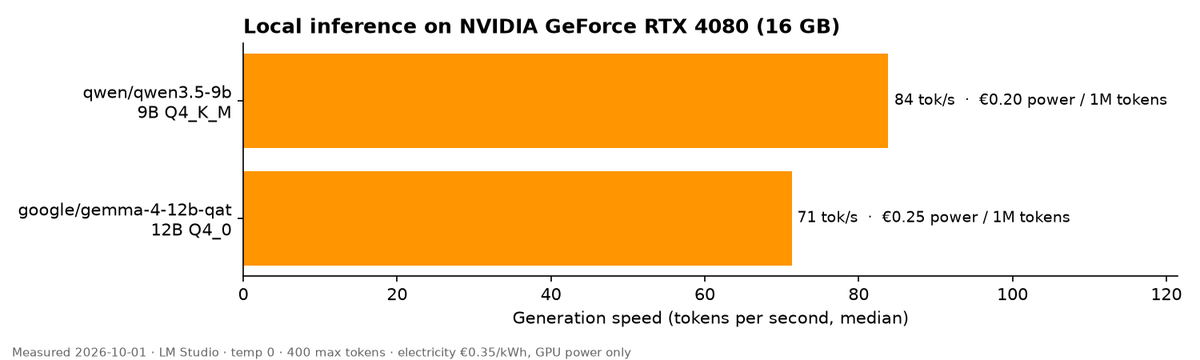
Before the Mac Studio shows up, I measured what I already have. RTX 4080 with 16GB, LM Studio, median of 3 runs.
Qwen 3.5 9B: 84 tok/s
Gemma 4 12B: 71 tok/s
About €0.20 to €0.25 per 1M tokens (GPU power only, €0.35/kWh).
Fast enough for small models. The 16GB is the wall. Same tests again once the 512GB box is on my desk. https://t.co/rtDPuGhaIL
Made the call: M5 Ultra Mac Studio with 512GB once that config ships (Apple says late October).
It won't beat a GPU cluster. That's not the point. Nobody can halve my plan overnight or decide which model I'm allowed to run.
Real numbers once it's on my desk.
Fair apology. It also shows who owns the meter: one post and every paid account gets its limits reset.
The only meter on my own GPU is the power bill. https://t.co/RKO9WNL8fV
Global reset landing tomorrow 10am PST for all paid ChatGPT accounts. Apologies for the slow start with GPT-6.1 Sol, it's now back to running at expected speeds after the massive load spike in the first two days.
@0xSero@MiaAI_lab DeepSeek's own API sells V4.1 Flash output at $0.60 per million off-peak. A 3090 + DDR4 box pulling ~500 W at German power prices needs around 90 tok/s just to match that on electricity. What decode speed are you seeing?
@matthewmillerai The 40% is the list price. Cache reads are $0.25 per million on Fable 5.1 vs $0.20 on Opus 5.5, and a long agent session is mostly cache reads. So the gap you actually feel there is mostly the $50 vs $20 output.
Claude for Government went GA yesterday. No seat fees. Agencies prepay usage with a hard cap, so spend can't exceed what they budgeted.
That's the billing model every consumer plan should have.
What we get instead is a fixed price and a usage limit the vendor can move.
Perplexity put its decision model on Hugging Face under Apache 2.0 and sells the same model at 4 cents per million input tokens, output free.
Cloudflare did the same with Clef a few hours earlier. The small Clef is built on Qwen 3.5 9B, which takes about 7GB of VRAM on my RTX 4080 at 4-bit.
At 4 cents a million, would you still run it yourself? https://t.co/D00RluWBVP
We’re open sourcing a state of the art multimodal Decision Model, pplx-decider-27b, and are offering it in a new Decisions API at 4 cents per million input tokens and free output tokens. We intend to bring down the price even further over the coming days. Enjoy!
@bridgebench Add one open-weights model you run yourself from a fixed file, as a control.
If that one also moves between 90% and 110%, you know how much of the band is your harness and not the provider.
@arena Same $8/M blended as the High run on Sep 23. But xHigh exists to spend more reasoning tokens per task, so the bill per task isn't the same.
Any chance of a cost-per-task column next to the score?
@ArtificialAnlys@MicrosoftAI $0.54/hour for streaming vs $0.10 for Microsoft's batch model, so you pay 5x for it being live.
If you don't need live captions, Phonon-2 is 164MB of open weights and transcribes an hour of audio in ~20s on a MacBook Air, per Fermion.
@jun_song Open source can win the weights and still lose if everyone rents them back from the same few clouds.
You're on the hardware side of this. Are more of your buyers running open models on their own boxes now?
@digitalix Apple lists 1.2TB/s for the M5 Ultra. A perfect split across two Sparks tops out around 546GB/s.
I'm waiting for the 512GB Studio in late October, so I'm curious: did the Sparks still take prefill?
@sudoingX At 130 W, 76 tok/s total comes to about €0.17 per 1M tokens (GPU power only, €0.35/kWh).
My 4080 runs Gemma 4 12B at 71 tok/s single stream, ~180 W, so roughly €0.25.
Does the 17 to 21 per agent hold once all four contexts get near 64k?
Anthropic's leaked IPO prospectus, per Reuters, lists $518B in future cloud and compute commitments. Amazon and Google are major suppliers.
You rent Claude from Anthropic. Anthropic rents the machines.
Everyone in this stack is a tenant except whoever owns the chips.