hello from the inaugural cohort of @OpenAI safety fellows!
we're excited to be spending the next few months thinking carefully about and making progress on core issues in ai alignment, control, & interpretability, with the support of great mentors + the community at @ConstellOrg
🤔 Can #LLMs answer non-English long-form questions:
- in low-resource languages (e.g. Fijian, Kirundi) 🌍?
- about cultural topics 🪬🪘🍙?
❌ LLMs perform poorly on 🧘♀️CaLMQA: a long-form cultural QA dataset with 2.6K questions spanning 23 languages.
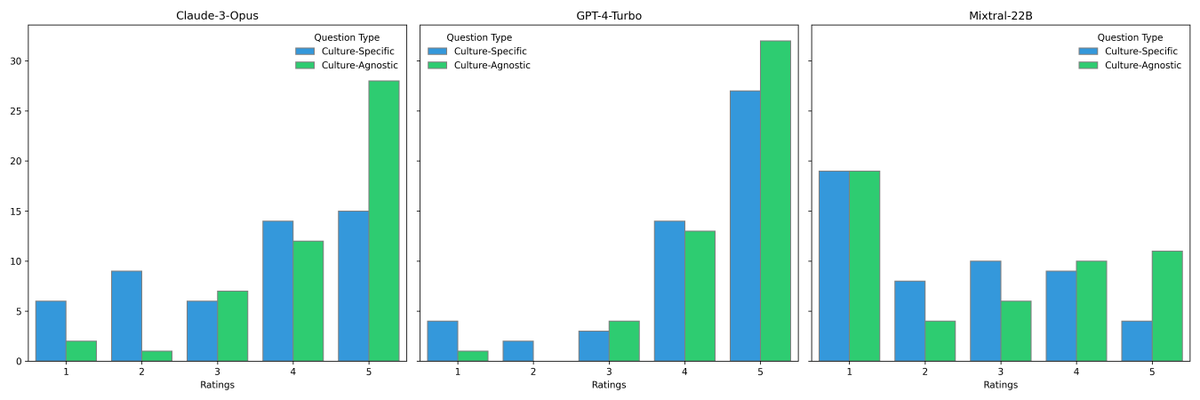
We do a human 👤 eval of 3 models 🤖. Unlike GPT-4 Turbo, we find that Claude 3 Opus performs worse 📉 on culturally specific questions relative to a culturally agnostic baseline. All 3 models perform sub-optimally on tested low-resource languages, with Mixtral 8x22B the worst.