I enjoy getting NanoGPT training speed records. I’m also interested in making my formulation of NanoGPT speedrunning an accessible benchmark on which other people find it easy to try new ideas.
To that end, I have tried to keep the code of the current record short, and minimize its installation time. Currently it’s 537 lines of code, and installs+runs in 20 minutes on a fresh 8xH100. That means the cost of a new record attempt is about $8.
I’ve enjoyed seeing the records that other people have gotten. @vyasnikhil96 got a new sample-efficiency record using the SOAP optimizer, and I understand he’s currently working on reducing its overhead so that it can potentially compete with Muon on wallclock time in the future. @bozavlado discovered that Muon works better if the QKV weights are orthogonalized separately. And @Grad62304977 improved the record significantly using a wide range of architectural modernizations, including QK-norm. I was surprised to see that QK-norm, which from what I understand was invented to deal with instabilities that appear at large scale, also helps train faster at the small scale.
I’ve seen some more interesting new ideas for the speedrun be posted recently, and I’d like to encourage the researchers who came up with those ideas to also be the ones to try them out empirically. I think this makes the benchmark more reliable, if the empirical experiments are distributed across the community, rather than only me doing them.
I’m interested in two kinds of new results around this speedrun. First, of course, I’m interested in new records that improve the time to 3.28 val loss. The only rule is that you can’t use external data besides Fineweb10B, and you can’t use pretrained models. Beyond that, everything is fair game. Second, I’m interested in new trainings that match the current record, while being simpler. For example, if it can be shown that we can match the current record using standard AdamW instead of the Muon optimizer, then I think that would be a very interesting result.
The log file produced by the current speedrun contains not just the timing and final loss, but also a copy of the code used to produce the run. Therefore, the only thing myself or anyone else needs to verify and reproduce a new record is its log file.
Researchers have pointed out that we shouldn’t uncritically trust every result which is obtained at the 124M-parameter scale. I absolutely agree - we shouldn't blindly expect results to scale up. However, I still believe it’s valuable for the community to at least have one stable small-scale benchmark. Once an idea has been clearly proven to work at small scale, it becomes relatively simple to test it a larger scale. I think this is a better situation than the current status quo, where every LM training paper seems to use a different benchmark, making it challenging for the community to evaluate new ideas. The only exception to this evaluation system would be ideas that only work at large scale, so can’t be demonstrated in a small-scale benchmark. These do exist, but I believe they are less common in the recent literature than ideas which are also supposed to work at the 124M-parameter scale, which we should be able to efficiently evaluate using a stable and competitive small-scale benchmark.
If the interest in this benchmark stays strong, I am hopeful that some very interesting things can come out of it. Thanks for your interest,
Keller
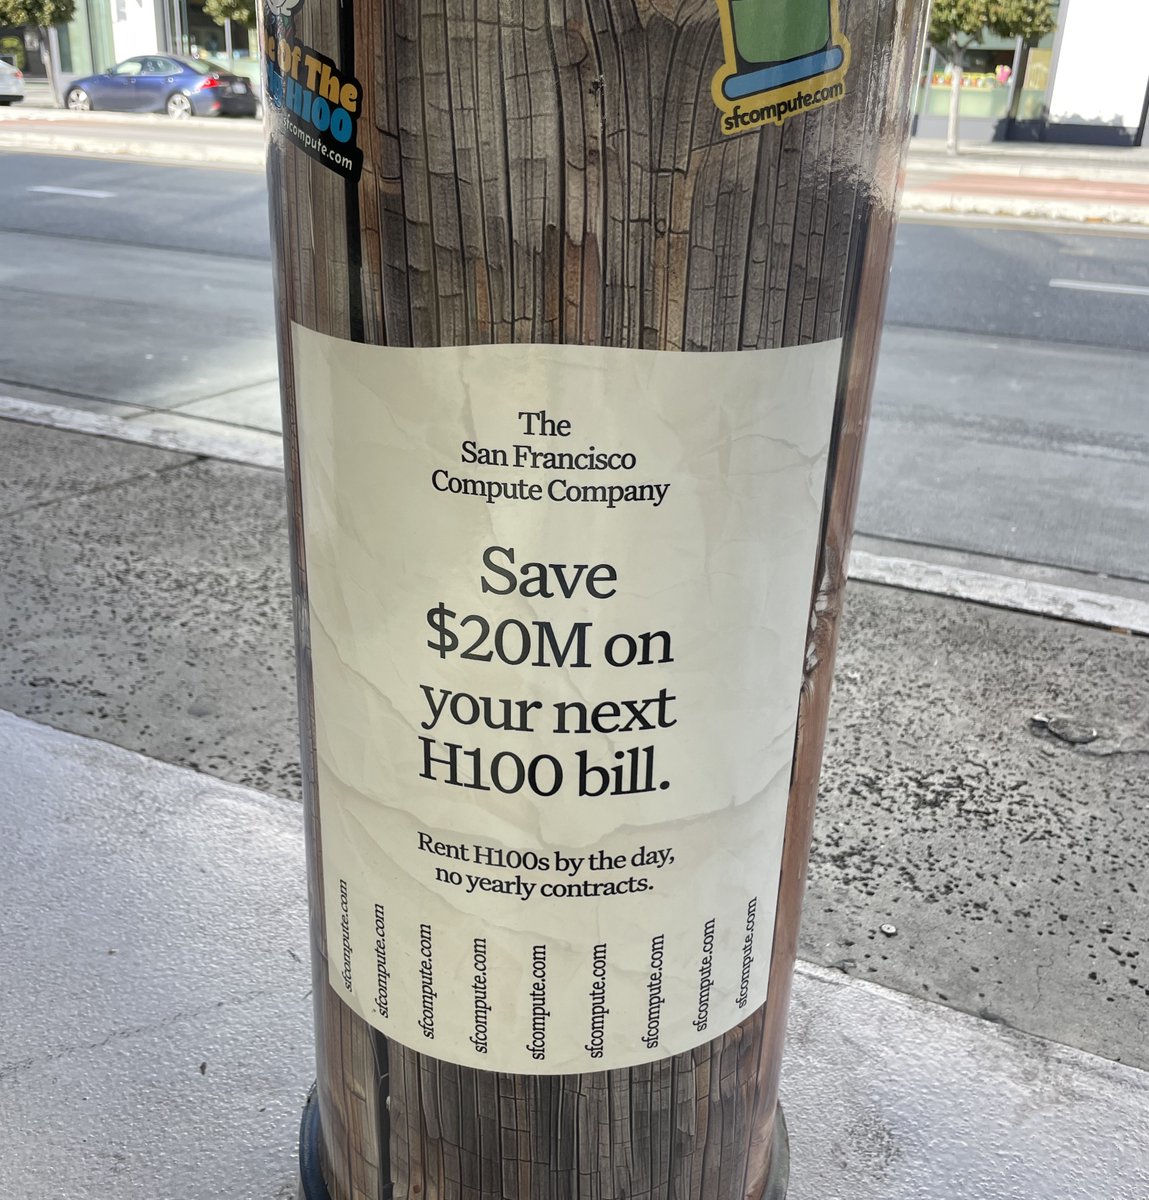
Only in #SanFrancisco does this ad make sense on a bullock at the train station. A key rule of advertising is to know your customer. Nailed it. I'm thinking, "yes, indeed, I do want to save $20M on my next H100 bill".
Sent out #otd in 1995: Bill Gates' famous memo in which he describes the Internet as "a tidal wave" and "the single most important development since the PC."
The full memo: https://t.co/ipofCLN4e6
1/22
As this chart shows, there is a big difference between what the market and the Fed think.
And this divergence will define the first part of 2023 trading.
A 🧵to explain
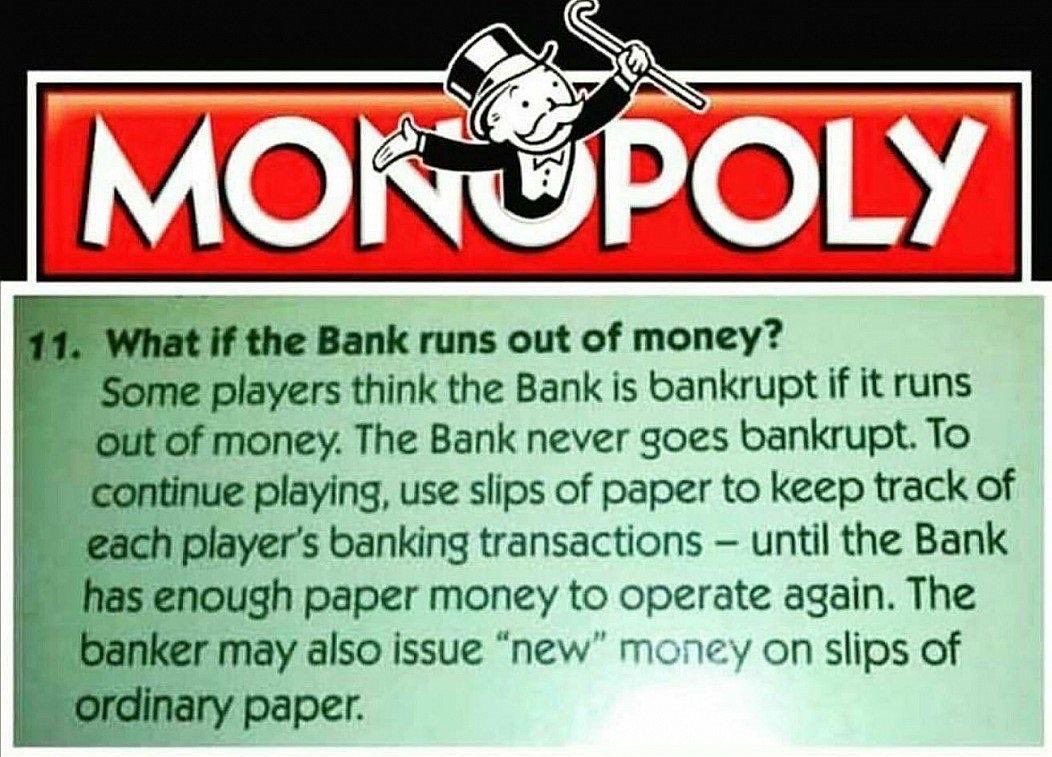
In 1971 when I was a young clerk on the floor of the New York Stock Exchange, the United States ran out of money and defaulted on its debts. That's right, the US ran out of money. (1/6)
I listened in on Twitter’s Friday all-hands with employees. Lots of new stuff in here, including Parag Agrawal’s regrets
Yes, he said. This deal could have been avoided.
https://t.co/JY8QJbHFam
The "pizza principle," a mainstay of New York economics for more than 40 years, states that a slice of cheese pizza will always be the same price as a subway ride.
Well, that's not the case anymore https://t.co/VFQUTrrxON
#WFH is cutting city center retail spending
Impacts could include
1) Retail spending down 10% to 30%
2) Retail rents down similar amounts
3) City centers emptier and cheaper
Losers: retail property owners
Winners: employees who get to WFH
More https://t.co/ci6J5tELCV