(1/2) SAVE YOUR DATE: IKDD Data Science Meetup Series on "Large Language Models: Where are we now and what lies ahead?"
The event will feature short overview talks by @partha_p_t and @monojitchou followed by Q&A moderated by Prof. Mitesh Khapra.
https://t.co/mma1CnqOez
Staying for #NeurIPS2022 workshops?
Check out the Transfer Learning for NLP workshop on Saturday! https://t.co/o8aSKCgPTc
Speaker Lineup:
Jonas Pfeiffer
Graham Neubig
Percy Liang & Ananya Kumar
Sara Hooker & Kyunghyun Cho (Debate🗣️)
David Adelani
Mike Lewis
Full schedule in 🧵
I am looking for a highly talented research student to work in the areas of Explainable, Data-centric, and Trusted-AI.
A sample of my publications can be found at:
https://t.co/vLwrNR5Mat
To apply, send me an email at: [email protected]#PhD#MachineLearning@cnerg
Excited to announce that our work "Representation Learning for Conversational Data using Discourse Mutual Information Maximization" has been accepted as a full paper in NAACL 2022 #NAACL#NAACL2022
Joint work w/ @pawang_iitk, Manish Gupta, @SumeghRoychowd1, Aishik, Vasu, Atharva
Excited to announce the Microsoft Research–Indian Institute of Science AI Seminar Series featuring accessible talks on cutting-edge AI research by eminent speakers. The inaugural talk by Prof. Jitendra Malik (UC Berkeley) is on 4th March. Register at:
https://t.co/xQtxnJK2F5
Check out @soumi_das0407 talk in 16th Academic Research and Careers for Students Symposium as part of papers published in top conference. Her paper TMCOSS got published in @ICCV_2021. Check the video here. https://t.co/h2Einmzu7c @sourangshub@gangulyniloy
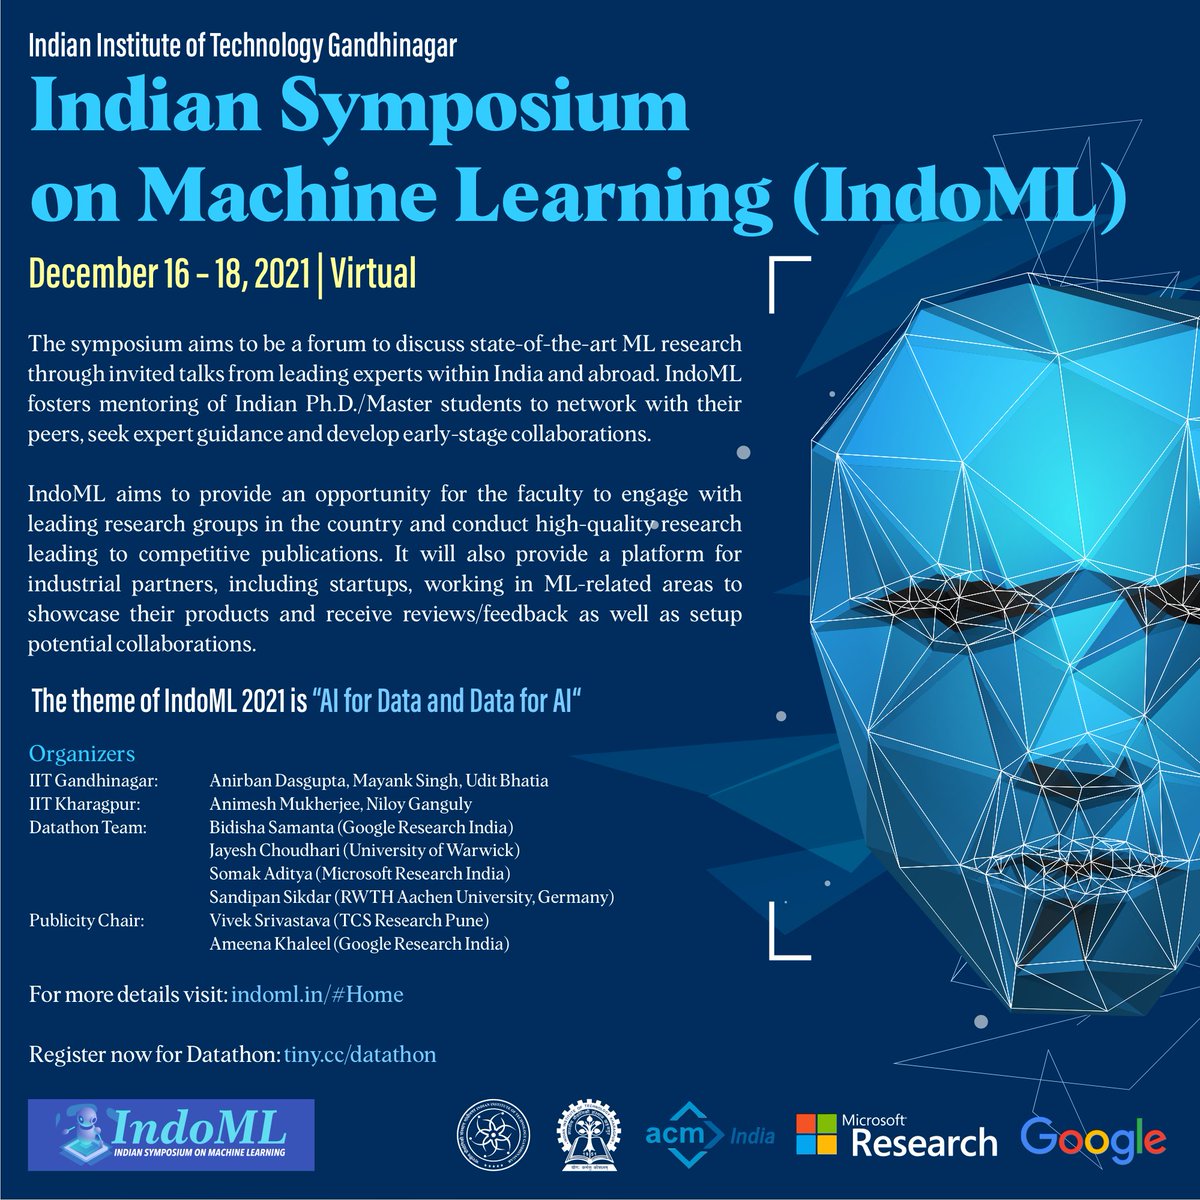
Delighted to announce that registrations for IndoML@2021 Main Symposium (Virtual Mode) is open till Dec. 15. Please help us spread the news !!!
Registrations are free but mandatory. Please register at https://t.co/inw4CdIuCm
Sharing a neat dashboard for COVID-19 resources in Indian cities. Select a city or state and it pulls up leads for oxygen cylinders, ICU beds, medicines and plasma. https://t.co/twtY9LvC3H
[1/7] Excited to announce “Masked Language Modeling and the Distributional Hypothesis: Order Word Matters Pre-training for Little”. BERT gets high task scores due to its distributional prior rather than its ability to “discover the NLP pipeline”. https://t.co/2s0gq8vGFz #NLProc
Many Transformer #NLP models have computational requirements that scale quadratically with input sequence length. Learn how sparse attention methods reduce the dependency from a quadratic to linear and achieve state-of-the-art results on challenging tasks. https://t.co/H9c7LeJZEH
We are very excited to know that IndoML 2020 will also be live-streamed on Youtube for everyone at https://t.co/95mRZhwvt8. Please share this link with your friends and colleagues. For live interaction, join the webinar itself at: https://t.co/plvU2bRsj3
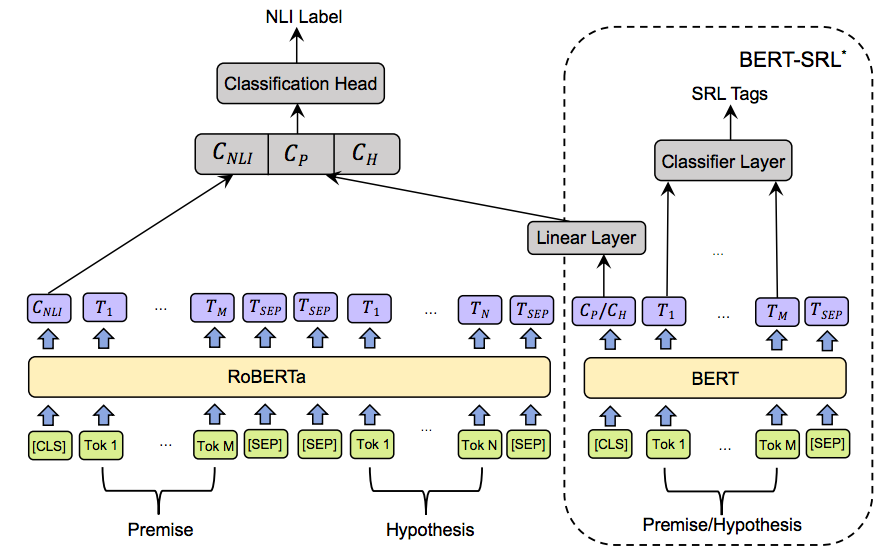
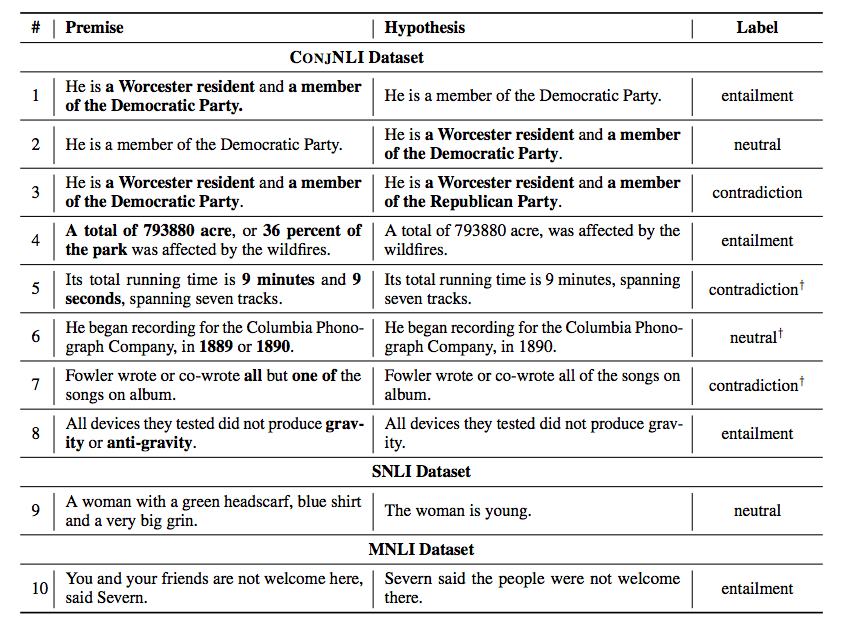
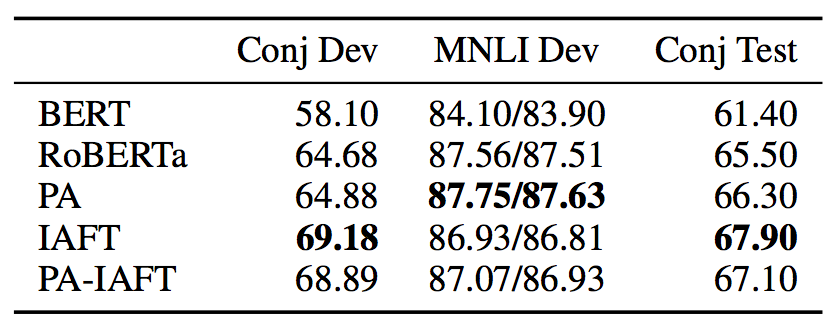
Excited to share my #emnlp2020 paper *ConjNLI* https://t.co/AouNjQALoh, an init attempt towards an NLI stress-test to eval model understanding of coordinating engl conjunctions (and,or,but,nor) w. quantifiers+negations & boolean+nonboolean inference🙂
w. @EasonNie@mohitban47 1/4
Our new #emnlp2020 paper on PRover: An interpretable transformer-based model that emulates formal reasoning by jointly answering questions over *explicit knowledge* as facts+rules (in natural language) & generating corresp proof graphs.
with @sayandgp, @shsriva & @mohitban47
1/4
Reviewers automatically assume that simple is not novel. This is sheer laziness. Yes, it may be simple and obvious in retrospect, but someone had to have that insight first. Simple is good. Simple is robust, easy to implement and reproduce, broadly applicable, etc.