OpenAI's Navier-Stokes effort used ~10,000 concurrent agents and ~130B output tokens. It made us rethink the scale ahead for RL infrastructure.
slime v0.4.0 is a first step toward greater scale, with four architectural changes:
• Focus: synchronous training for algorithmic exploration and correctness; fully async training for throughput at scale.
• Distributed rollout: spread orchestration across cluster CPUs, with independent generation pools and event loops.
• Persistent storage: introduce straw, our new storage middleware for rollout and training data, providing durable queues and shared tensor storage.
• Independent recovery: restart Megatron while healthy SGLang engines stay running, preserving accepted rollout work.
More on the architecture below 👇
https://t.co/4PR50r1AmR
1/5
slime environment update:
- SGLang upgraded to v0.5.21
- Megatron upgraded to v0.19.2
- TransformerEngine upgraded to v2.18
Previously, slime provided both CUDA 12 and CUDA 13 images. Following SGLang's CUDA requirements since v0.5.20, we will discontinue CUDA 12 images, and the latest tag will now point to CUDA 13.
For users who cannot easily upgrade their drivers, we have included cuda-compat in the CUDA 13 image, allowing supported CUDA 12-era drivers to run the new image without an immediate driver upgrade.
Additionally, with the SGLang upgrade, slime now officially supports RL training for GLM-5.3-Flash.
Recursive self-improvement needs agents that can build their own training environments. But researchers still part of the loop, making it hard to scale.
We introduce AutoEnvScaling, which turns Data Flywheel into a terminal task: a proposer agent builds complete Harbor tasks and sandbox. It builds just like human researchers. This enables self-play RL for terminal agents: one model improves as both builder and solver, without human-in-the-loop.
Training large models with RL typically runs on a fixed homogeneous cluster of the latest accelerators for numerical stability and faster throughput. This throws away inference optimization work done for other vendors and generations, limits the capacity you can utilize, and is unnecessarily expensive.
So we trained a model on agentic coding tasks using fully asynchronous RL and mixed-precision, mixed-accelerator samplers. With off-policy correction, training stayed stable through convergence, on par with homogeneous samplers, at a lower cost.
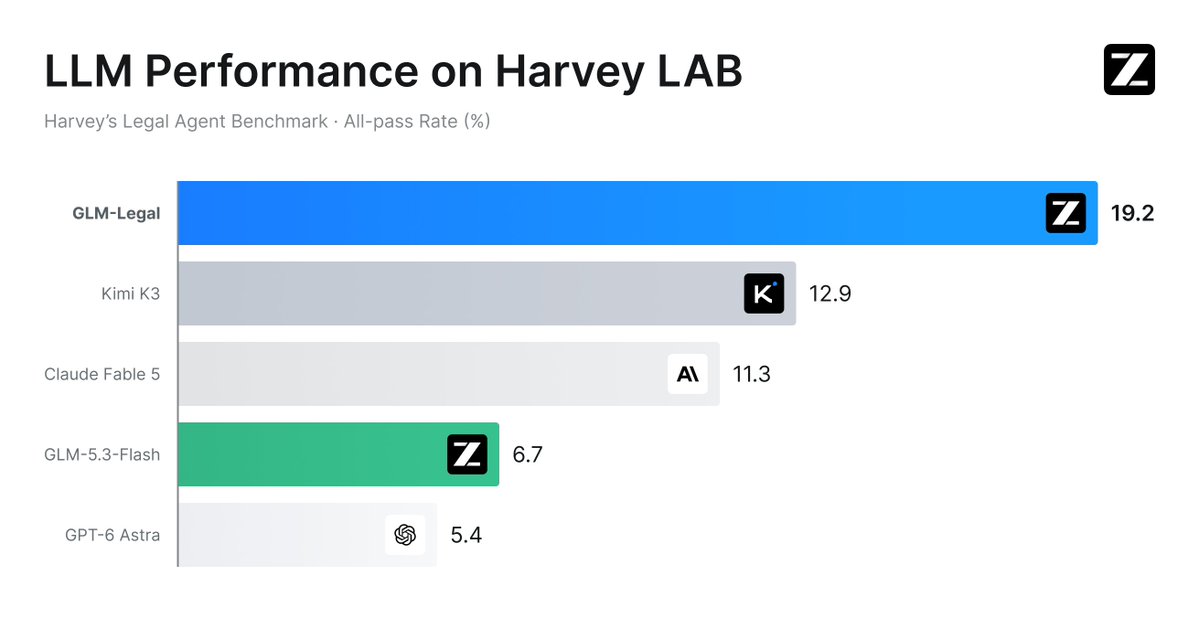
Introducing GLM-Legal
Built on GLM-5.3-Flash, GLM-Legal matches frontier models on mainstream legal benchmarks.
Designed for real legal workflows: contract review, evidence analysis, compliance, and more.
Tech Blog: https://t.co/xOzFqKNyqD
Apply for API Access: https://t.co/dKuoDRIKKz
Try AutoClaw: https://t.co/aGEG5HqTTb
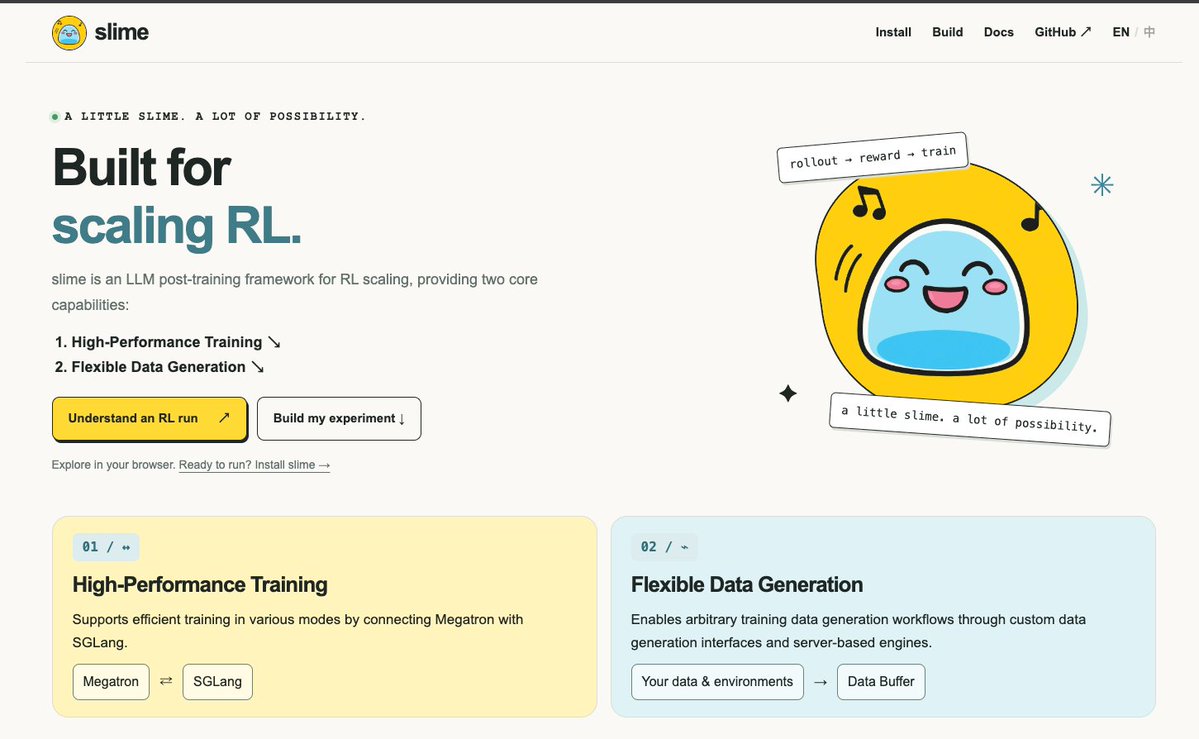
We've rebuilt slime's docs with an interactive homepage for LLM + RL!
We hope it can be a place for beginners to learn, and a handy tool for practitioners to explain what they do.
Have a look at:
https://t.co/fIITq53gks
sunabako also works independently of slime, with a Python SDK that supports:
• Running sandboxes without Docker-in-Docker
• Mounting local directories into sandboxes
• Using GPUs already exposed to the parent container
• Basic E2B-style APIs for sandbox creation, command execution, and file I/O
Install with:
pip install sunabako
Setup and examples:
https://t.co/iBsZ7u3NB5
Introducing sunabako, our second companion project for slime after straw: a lightweight sandbox runtime for agentic RL.
Setting up a separate sandbox service can slow you down when you’re still testing a training recipe. sunabako runs sandboxes inside your existing training containers, letting you use the cluster resources you already have to validate the full training loop before scaling out.
With sunabako, we’ve also added end-to-end agentic RL testing with Qwen3.8-27B powering Codex and Claude Code on coding tasks from MiMo’s newly released RL dataset. These tests cover agent execution, sandboxed grading, and policy updates, helping us catch regressions across slime’s agent stack.
Give slime + sunabako a try!
https://t.co/K4KxtaURr1
Recover training while preserving serving and rollout work.
A trainer OOM or configuration mistake becomes more expensive as the job grows.
v0.4.0 lets you adjust supported trainer parallelism or memory settings and resubmit to the same live Ray cluster. Healthy SGLang engines and routers remain running.
With Straw or saved rollout debug data, the new trainer restores the last committed checkpoint and replays retained batches, reusing accepted samples and saved conversion results.
This makes training retries cheaper by preserving serving resources and completed rollout work.
5/5
OpenAI's Navier-Stokes effort used ~10,000 concurrent agents and ~130B output tokens. It made us rethink the scale ahead for RL infrastructure.
slime v0.4.0 is a first step toward greater scale, with four architectural changes:
• Focus: synchronous training for algorithmic exploration and correctness; fully async training for throughput at scale.
• Distributed rollout: spread orchestration across cluster CPUs, with independent generation pools and event loops.
• Persistent storage: introduce straw, our new storage middleware for rollout and training data, providing durable queues and shared tensor storage.
• Independent recovery: restart Megatron while healthy SGLang engines stay running, preserving accepted rollout work.
More on the architecture below 👇
https://t.co/4PR50r1AmR
1/5
Introduce Straw: storage middleware for RL.
Distributed workers need a shared data layer for exchanging payloads and preserving progress.
Straw provides durable queues and tensor storage on a shared filesystem. Rollout workers publish data; training ranks read it by reference. Bulk payloads move through storage, while Ray carries control messages and references.
Prompts, partial rollouts, completed samples, and converted training batches persist. Packed files reduce small-file overhead, and rollout state can be checkpointed alongside the model.
JuiceFS is the currently supported shared-filesystem target.
https://t.co/JIQLA4h5kF
4/5
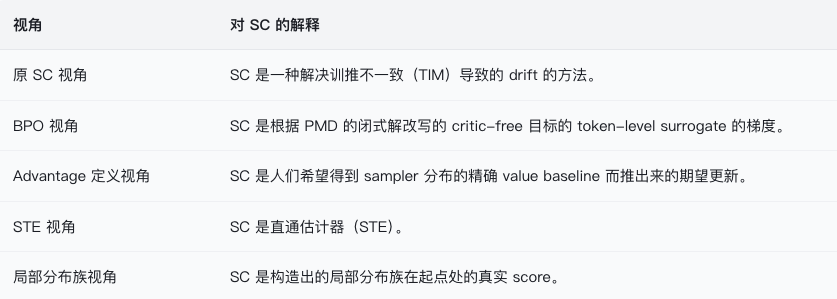
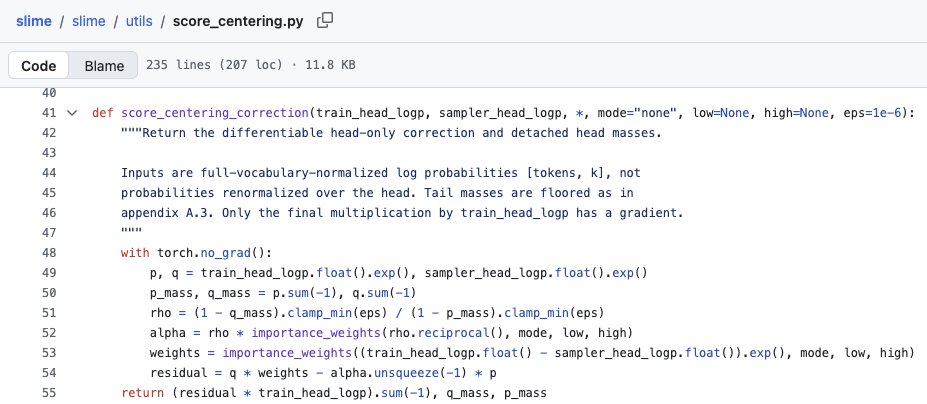
We wanted Score Centering to be a plug-and-play mismatch fix for off-policy RL setups. That's why it is very rewarding to see our method in slime in less than a week from release
Try it out for stabilizing your next run!
RL with LLMs is very unstable when training and sampling policies differ. Standard fixes (matching numerics, importance sampling) work around the problem.
We find the root cause of this instability from first principles and propose a way to directly cancel it. Score Centering is competitive and compatible with existing approaches — while simple to implement!
🧵 [1/6]
Huge congrats to the @radixark team on Miles v0.1! 🚀
Fully async agentic RL on a 744B MoE across 64 GB300s, with @sgl_project powering rollouts. Love the focus on getting rollout/training fidelity right alongside throughput.
https://t.co/LegEAlIybi