Your Hermes Agent can now delegate to RLMs 🙌 Recreated the document analyzer example with the converted skill. 136 PDF pages analyzed. Best part: Auto-configures from HERMES_MODEL / HERMES_PROVIDER env vars @NousResearch@Teknium
https://t.co/ReL1NqwlCQ
php2shell, java4shell, nginx2root... I mean, come on. At this point, any internet-facing service is pwned beyond recognition [insert always has been meme here].
Assume breach, always.
Until now, there's been no automated way to check that an AI agent actually follows your governance policy. That check usually takes months of manual work. asago closes that gap. It doesn't replace security experts, it frees them from the busywork. https://t.co/ju7DwbiFDQ
So now a small 300MB adapter makes your local 27B coding model dramatically better!
Hugging Face released an RL-trained LoRA adapter for Qwen3.8-27B, specifically optimized for OpenCode.
And the reported results are impressive!
SWE-bench Pro (hard 51 tasks):
🔴 Original → 35.3%
🟢 With LoRA → 51.0% 👈
Terminal-Bench 2.1:
🔴 Original → 46.4%
🟢 With LoRA → 52.4% 👈
Median agent turns on tasks both solved:
🐌 Original → 48 turns
🚀 With LoRA → 13 turns 👈
That's a 15.7% improvement on the selected SWE-bench Pro tasks and 73% fewer agent turns on shared solves.
With thinking disabled, the adapted model reportedly approaches or exceeds the original model running at maximum reasoning effort, using 6–8× fewer generated tokens per task in the team's comparison.
The best part?
💾 Adapter → ~300MB
🧠 Base model → Qwen3.8-27B
🔓 License → Apache 2.0
💻 Local inference → llama.cpp
🛠️ Coding harness → OpenCode
📦 GGUF adapter available
Just a small adapter teaching an existing model to use coding tools more effectively.
Video source: @HuggingFace
Red Hat ran its own engineering org on open weights as customer zero. What the EnMaaS pilot (Praxis gateway + llm-d + vLLM) showed:
-> Scale: more than 1 trillion tokens processed in a single 30-day window.
-> Adoption: give developers frictionless access and they take it. Usage started 70/30 in favor of commercial frontier APIs and flipped to 30/70 toward internally hosted open weight models, with open weights gaining share every day.
-> Workload: Praxis intelligently routed the majority of routine coding and evaluation traffic away from external APIs to hosted open weight models.
-> Cost: shifting that traffic from frontier to self-hosted models on llm-d cut effective token spend 40 to 70% vs prior frontier pricing, depending on prompt caching and routing.
Here's how we did it:
https://t.co/58AyXbEg6t
In my ongoing quest to find the limits of Opus 5.5, I directed it to audit my old scientific field, theoretical astrophysics. We indexed about 150,000 papers, audited 50,000 for issues, and did progressively more thorough checks on thousands more. We found nearly 1000 major errors that got cited many times, most are still uncorrected. This survey enabled me to estimate the efficacy of peer review for correcting errors (not very good) and to identify dozens of open questions that anyone with spare Claude Max tokens could answer today (.md context files included).
Bottom line: AI can speed up quantitative science by >1000x with no further model improvement required. But I'm seeing no evidence of this being pushed within universities, only academics complaining about labs dropping math proofs.
Among my fellow reformed academic high agency founders, however, several are speed running entire disciplines.
This survey has implications for how science will be run in the very near future. Hint: Academic publishing is dead. It was already a very stupid way to record and promulgate knowledge, and had been so for decades, even before all that publicly funded knowledge was locked behind paywall cartels. Now AIs can generate thousands of novel, correct papers per day, it is no longer meaningful for humans to consider a research paper a "unit of science" or to even bother much with the 99.9% of science which, up to this point, was necessary drudgery. Time to discover something like General Relativity or Evolution every week. LFG!!
Enjoy: https://t.co/BhRxKVvbim
The Wow! Signal Software Lives Again! We successfully restored and ran all the original Assembly and FORTRAN programs used to detect the Wow! Signal in 1977, using an IBM 1130 emulator. We even recreated the original printer font! #Retrocomputing#RadioAstronomy#AreciboWow
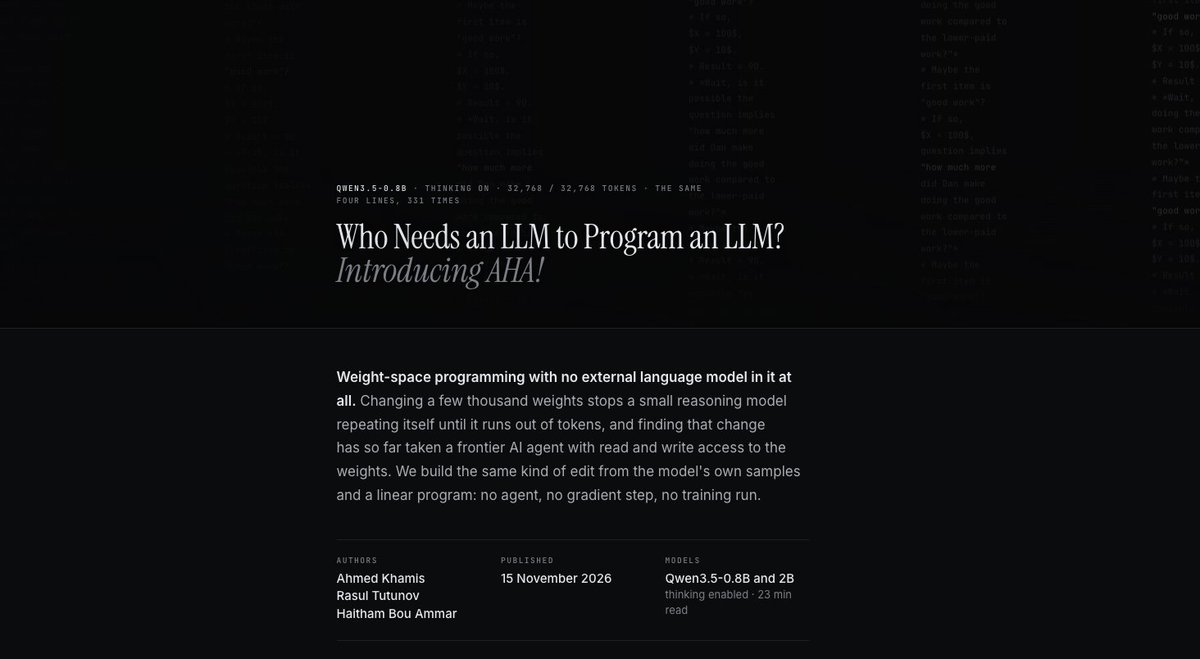
we were quire exicted when we saw the weight-space programming blog by MIT researchers, where they showed that when a small reasoning model gets stuck in a loop, a frontier LLM can read a model's weights and fix one of its bugs by hand.
we asked: do you actually need the LLM?
turns out you don't. today we're releasing 'AHA'.
the trick is to let the model show you its own bug. we rewind it to just before it starts looping and let it try again from that exact point. sometimes it loops, sometimes it doesn't. a linear program then turns that into a tiny weight edit.
no training. no gradients. no labels. no LLM in the loop.
on qwen3.5-0.8B it matches the edit the frontier agent made, for example: MATH-500 goes from 9.8 to 51.8.
Blog: https://t.co/nxfkW0KfSz
Code: https://t.co/BDfNtur7dr
Letting IDASQL + Claude/Opus 5.5 rebuild the source code of a childhood game overnight. I own a legit copy but the game does not run on modern systems. By the morning it will be rebuilt for all major platforms, up and running.
Reality of our days:
1. I am sitting on a set of vulns (4+) that allows me to remotely take over a consumer home automation device I have (3+ diff ways).
2. The vendor doesn't only serve consumers, but also critical infra (announced partnerships include pharma manufacturing plants, airport logistics, hospitals, etc) across various locations in Europe and the US (not the same product line, ofc, so maybe moot).
3. Claude and Astra refuse to help me explore even my own device, so now I'm using Chinese hosted models for investigating.
4. The vendor (with a revenue of $0.75B) does not maintain any security disclosure practice whatsoever, nor does respond to emails.
So, to recap, I need to outsource vulnerability hunting of (potentially, I don't know) critical western infrastructure to Chinese models, because the western models refuse; and the vendor doesn't give a shit. Fun timeline.
PS: The vendor is Swiss.