I used gpt-6 astra to try to understand what the navier stokes problem is.. aesthetically
metaphor: imagine you are stirring your tea. could a whirlpool exist that speeds up rather than smooths out over time? ☕️
it put together this visual essay: https://t.co/O3jGGAS8aa
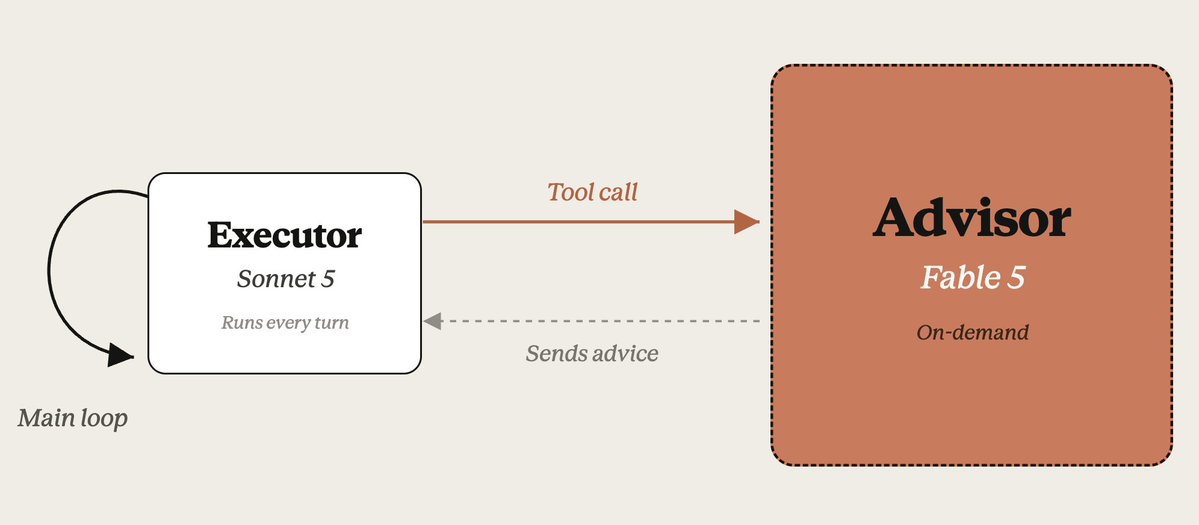
A few patterns we frequently use with Fable 5:
Use Fable 5 as an "advisor."
An executor (Sonnet 5) calls Fable 5 for guidance.
Most tokens are billed at the lower executor rate.
I always had this uneducated feeling that humans are inefficient: food, drinks, bathroom breaks, sleep.
Then you work with AI and see the data centres and power needed.
A human running on coffee suddenly looks like a miracle of efficiency.
🚨 Anthropic's own team just showed how to actually use Claude Code properly.
30 minutes. free. the person who created Claude Code.
watch the workshop. bookmark it.
worth more than every $500 course you almost bought.
you've been using Claude without knowing 40 of its commands.
Then read the guide below.
@ClementDelangue I need to OCR a google sheets doc with one column being images - how can I do that? Post OCR the agent needs to fill out rows of the doc
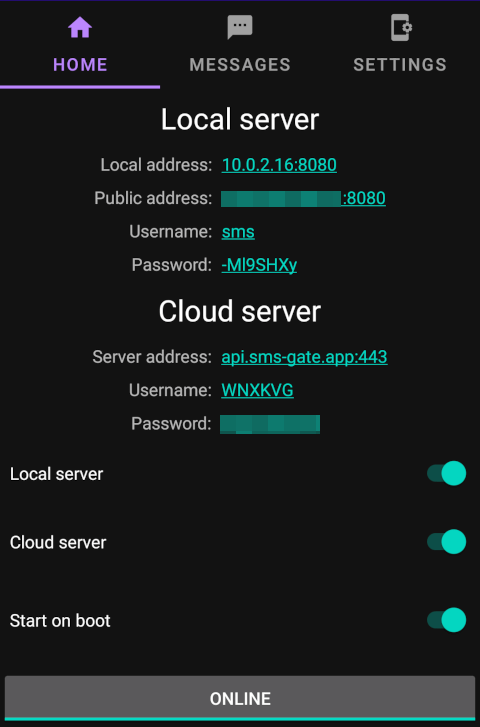
🚨 Twilio charges $0.0079 per SMS. Someone just turned any old Android phone into a free SMS gateway. Unlimited messages. $0.
It's called SMS Gateway for Android.
Install it on any Android phone. It becomes a full SMS sending and receiving server with an API.
No Twilio. No MessageBird. No per-message pricing. No contracts. Just an old phone and a SIM card.
Here's what's inside this thing:
→ Send and receive SMS through a REST API from any app or service
→ Works with any Android phone running 5.0 or newer
→ End-to-end encryption. Messages are encrypted before they leave the device.
→ Multi-SIM support. Use multiple SIM cards on one phone.
→ Multi-device support. Connect multiple phones to the same account.
→ Real-time webhooks for incoming messages
→ Multipart messages with auto-splitting for long texts
→ Track delivery status of every message in real time
→ No registration required. No email. No account in local mode.
Here's the wildest part:
That old Android phone in your drawer that you haven't touched in 2 years? Install this app. Insert a SIM card. You now have your own private SMS infrastructure.
Two-factor authentication. Order confirmations. Appointment reminders. Notification alerts. All the things startups pay Twilio thousands a month for.
Free. Running on a phone you already own.
Startups spend $500 to $5,000/month on SMS APIs. This costs the price of a SIM card.
875 GitHub stars. 359 commits. Apache 2.0 License.
100% Open Source.
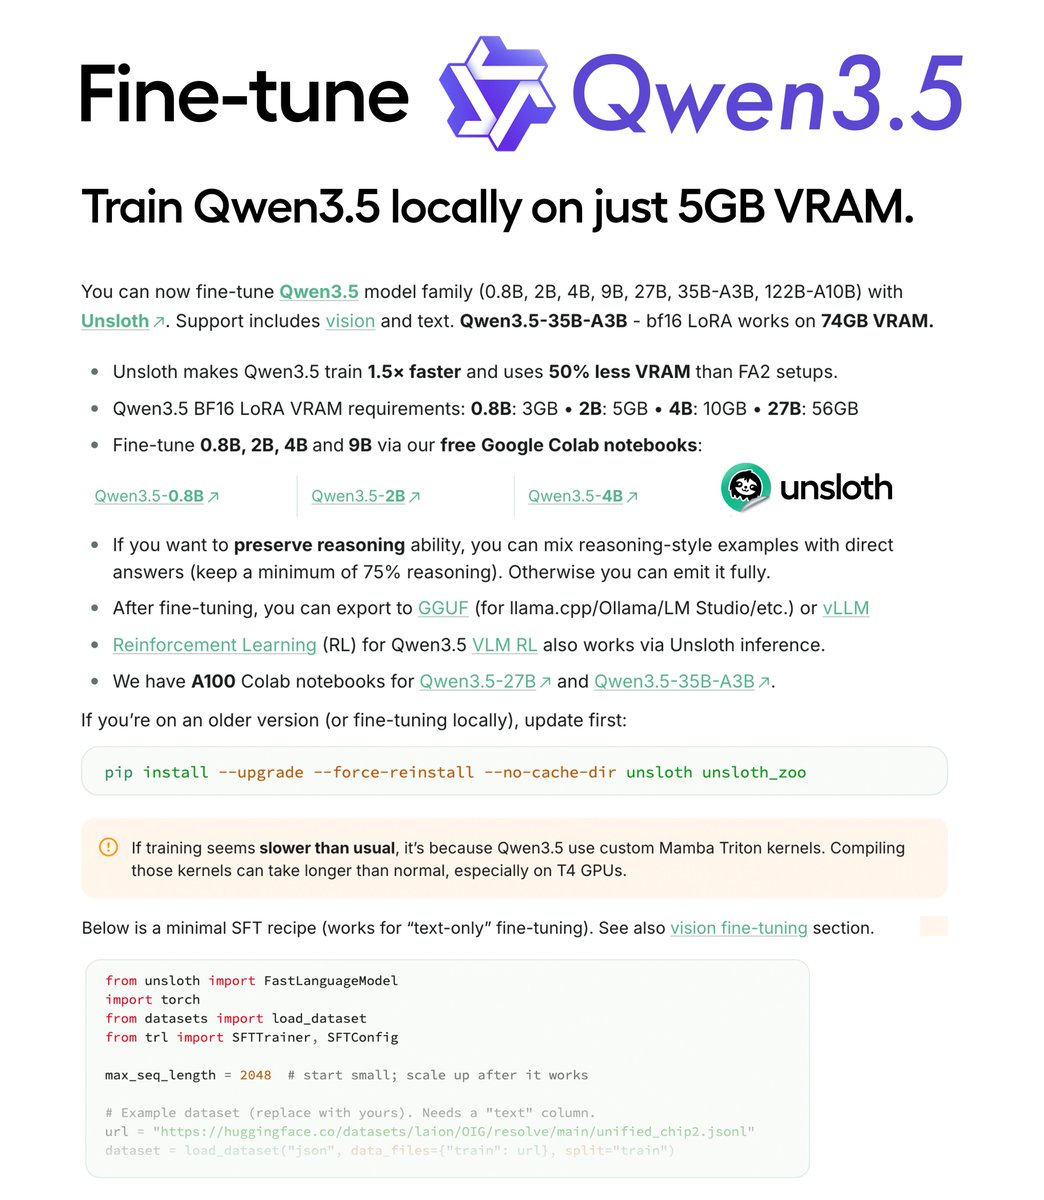
You can now fine-tune Qwen3.5 with our free notebook! 🔥
You just need 5GB VRAM to train Qwen3.5-2B LoRA locally!
Unsloth trains Qwen3.5 1.5x faster with 50% less VRAM.
GitHub: https://t.co/2kXqhhvLsb
Guide: https://t.co/JCPGIRo99s
Qwen3.5-4B Colab: https://t.co/2Aj1mZ3f5j
Smarter. Faster. Gemini 3.1 Flash-Lite is here⚡
The model offers uncompromising speed & intelligence at scale by focusing on:
— Cost-efficiency: Priced at just $0.25/1M input and $1.50/1M output tokens, it gets work done faster at a fraction of the cost of larger models, including a 45% increase in output speed compared to Gemini 2.5 Flash
— Compute control: 3.1 Flash-Lite comes with flexible thinking levels so you can actively select how much the model “thinks” for a given task, based on the complexity of your project
— Scalable intelligence for building: The model can handle high volume tasks at scale while keeping costs down *and* can tackle complex workloads where in-depth reasoning is needed, like generating user interfaces or detailed instruction following
3.1 Flash-Lite is rolling out in preview today via the Gemini API in @GoogleAIStudio and Vertex AI.
🚀 Introducing the Qwen 3.5 Medium Model Series
Qwen3.5-Flash · Qwen3.5-35B-A3B · Qwen3.5-122B-A10B · Qwen3.5-27B
✨ More intelligence, less compute.
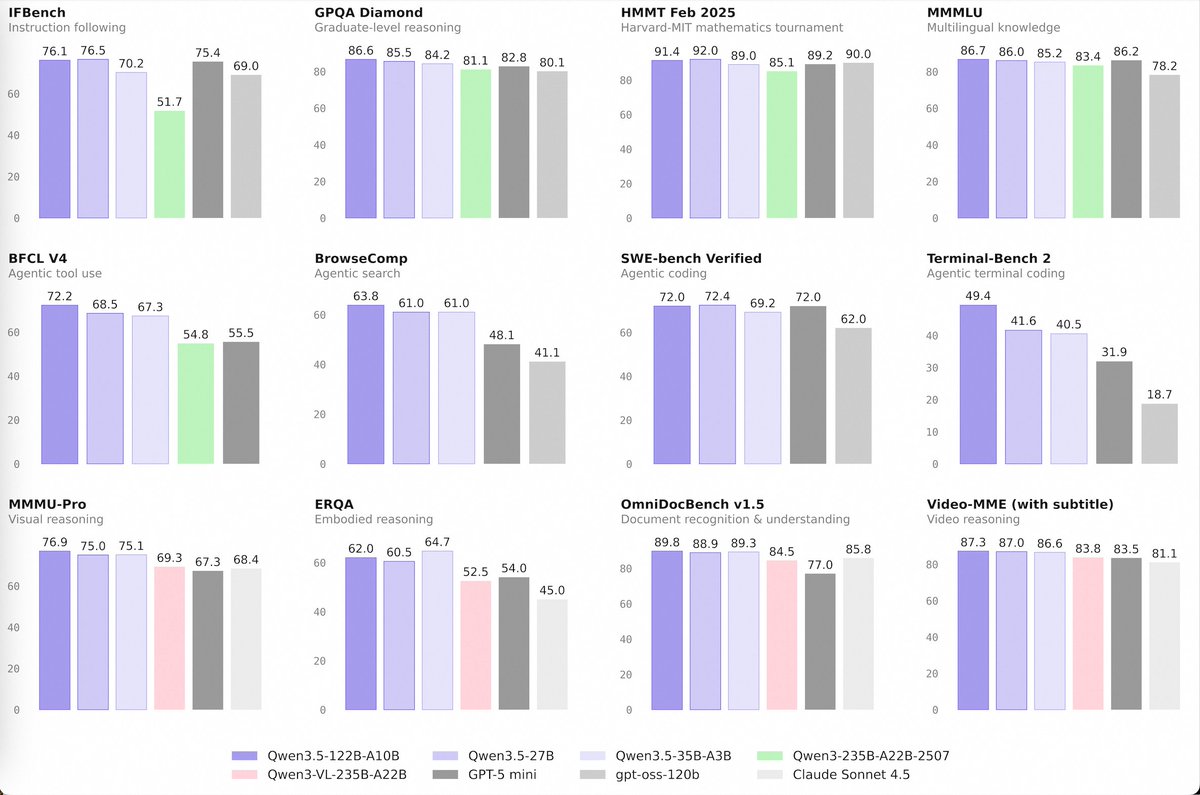
• Qwen3.5-35B-A3B now surpasses Qwen3-235B-A22B-2507 and Qwen3-VL-235B-A22B — a reminder that better architecture, data quality, and RL can move intelligence forward, not just bigger parameter counts.
• Qwen3.5-122B-A10B and 27B continue narrowing the gap between medium-sized and frontier models — especially in more complex agent scenarios.
• Qwen3.5-Flash is the hosted production version aligned with 35B-A3B, featuring:
– 1M context length by default
– Official built-in tools
🔗 Hugging Face: https://t.co/wFMdX5pDjU
🔗 ModelScope: https://t.co/9NGXcIdCWI
🔗 Qwen3.5-Flash API: https://t.co/82ESSpaqAF
Try in Qwen Chat 👇
Flash: https://t.co/UkTL3JZxIK
27B: https://t.co/haKxG4lETy
35B-A3B: https://t.co/Oc1lYSTbwh
122B-A10B: https://t.co/hBMODXmh1o
Would love to hear what you build with it.
llmfit - полезная утилита, которая показывает, какую LLM можно запустить на вашем устройстве и с каким успехом, определяет оптимальную квантизацию для памяти, прикидывает количество токенов в секунду
вот какие результаты на моём компе 7-летней давности
Advice for AI engineers 💡
A small Visual Language Model fine-tuned on your custom dataset is as accurate as GPT-5...
... and costs 50 times less.
For example, LFM2.5-VL-1.6B by @liquidai running locally at full speed with llama.cpp ↓
Someone built a web-based System Design Simulator,
where you drag & drop architecture components and actually simulate traffic, failures, latency, and scaling in real time,
System design just got way more interactive.