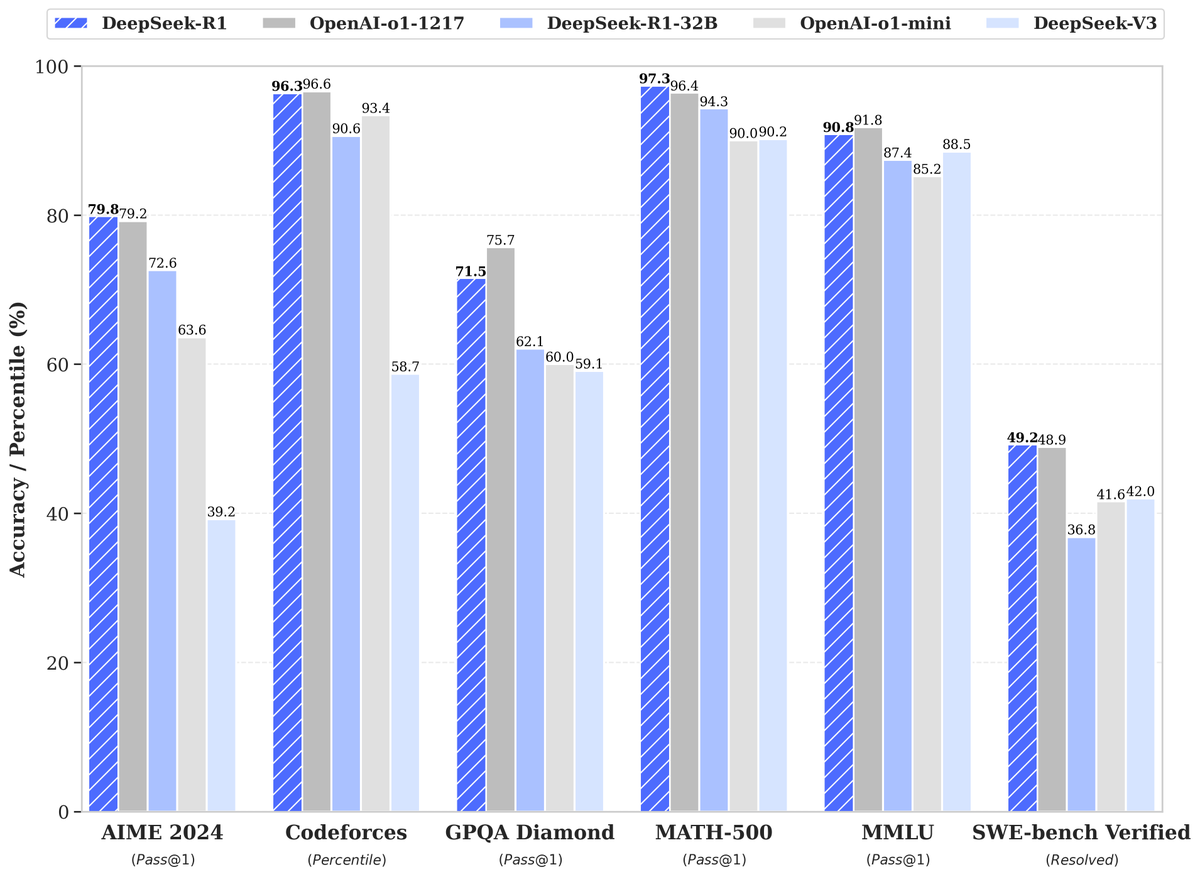
🚀 DeepSeek-R1 is here!
⚡ Performance on par with OpenAI-o1
📖 Fully open-source model & technical report
🏆 MIT licensed: Distill & commercialize freely!
🌐 Website & API are live now! Try DeepThink at https://t.co/v1TFy7LHNy today!
🐋 1/n
⏰ We introduce Reinforcement Pre-Training (RPT🍒)
— reframing next-token prediction as a reasoning task using RLVR
✅ General-purpose reasoning
📑 Scalable RL on web corpus
📈 Stronger pre-training + RLVR results
🚀 Allow allocate more compute on specific tokens
🚀 Day 0: Warming up for #OpenSourceWeek!
We're a tiny team @deepseek_ai exploring AGI. Starting next week, we'll be open-sourcing 5 repos, sharing our small but sincere progress with full transparency.
These humble building blocks in our online service have been documented, deployed and battle-tested in production.
As part of the open-source community, we believe that every line shared becomes collective momentum that accelerates the journey.
Daily unlocks are coming soon. No ivory towers - just pure garage-energy and community-driven innovation.
🚀 Introducing NSA: A Hardware-Aligned and Natively Trainable Sparse Attention mechanism for ultra-fast long-context training & inference!
Core components of NSA:
• Dynamic hierarchical sparse strategy
• Coarse-grained token compression
• Fine-grained token selection
💡 With optimized design for modern hardware, NSA speeds up inference while reducing pre-training costs—without compromising performance. It matches or outperforms Full Attention models on general benchmarks, long-context tasks, and instruction-based reasoning.
📖 For more details, check out our paper here: https://t.co/HJiqzwnUV7
@Grad62304977 During RL training, the model's reasoning patterns evolve continuously. At times, a specific pattern may suddenly emerge prominently, which I define as the "aha moment". For instance, the image below illustrates the emergency of the `wait` pattern in one of my experiments.
Last year, I joined DeepSeek with no RL experience. While conducting Mathshepherd and DeepSeekMath research, I independently derived this unified formula to understand various training methods. It felt like an "aha moment", though I later realized it was PG.
If you can only read one DeepSeek paper in your life, read DeepSeek Math.
Everything else is either ≈obvious in hindsight or clever optimization. DeepSeek Math is a tour de force of data engineering, general DL LLM methodology, RL, and just beautiful. Just 22 pages.
This formula represents my initial insight when I first delved into the RL process; while it may not be entirely rigorous, I deeply value it and cherish the "aha moments" it brought to my research.
I hope this formula helps researchers with no experience in RL better understand the RL of LLMs. Additionally, I am grateful to have @pigjunebaba by my side to witness the miracle of RL.
DeepSeek-R1 (Preview) Results 🔥
We worked with the @deepseek_ai team to evaluate R1 Preview models on LiveCodeBench.
The model performs in the vicinity of o1-Medium providing SOTA reasoning performance! Huge kudos to the team and I'm looking forward to the full release!!
/1
🚀 DeepSeek-R1-Lite-Preview is now live: unleashing supercharged reasoning power!
🔍 o1-preview-level performance on AIME & MATH benchmarks.
💡 Transparent thought process in real-time.
🛠️ Open-source models & API coming soon!
🌐 Try it now at https://t.co/v1TFy7LHNy
#DeepSeek
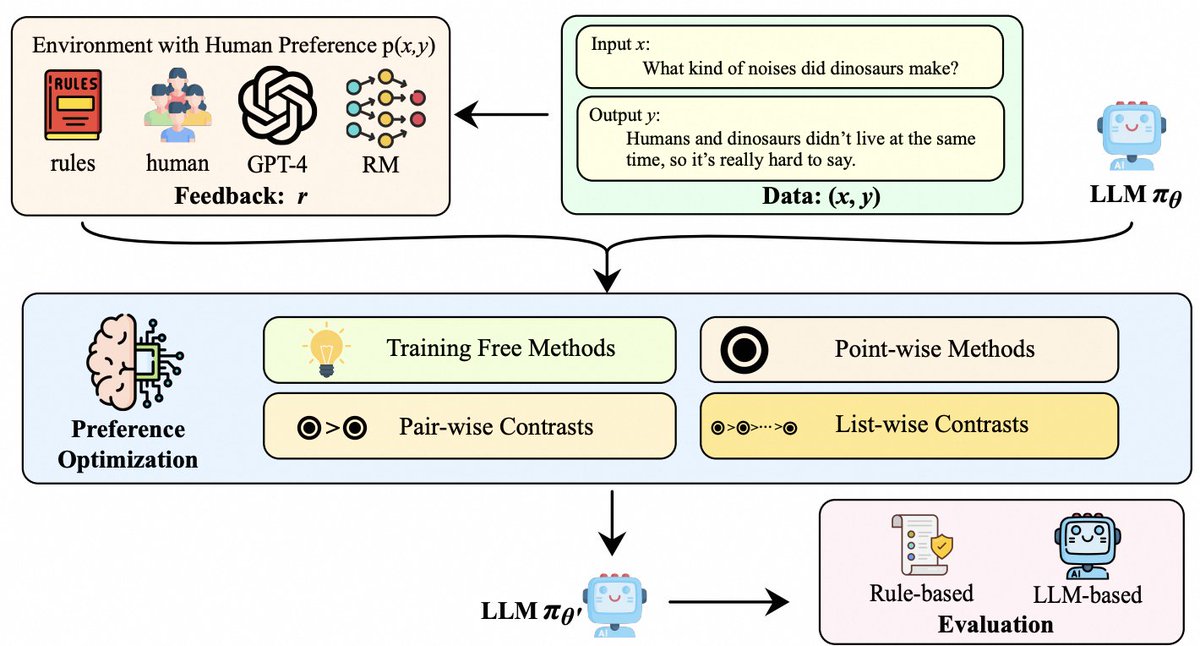
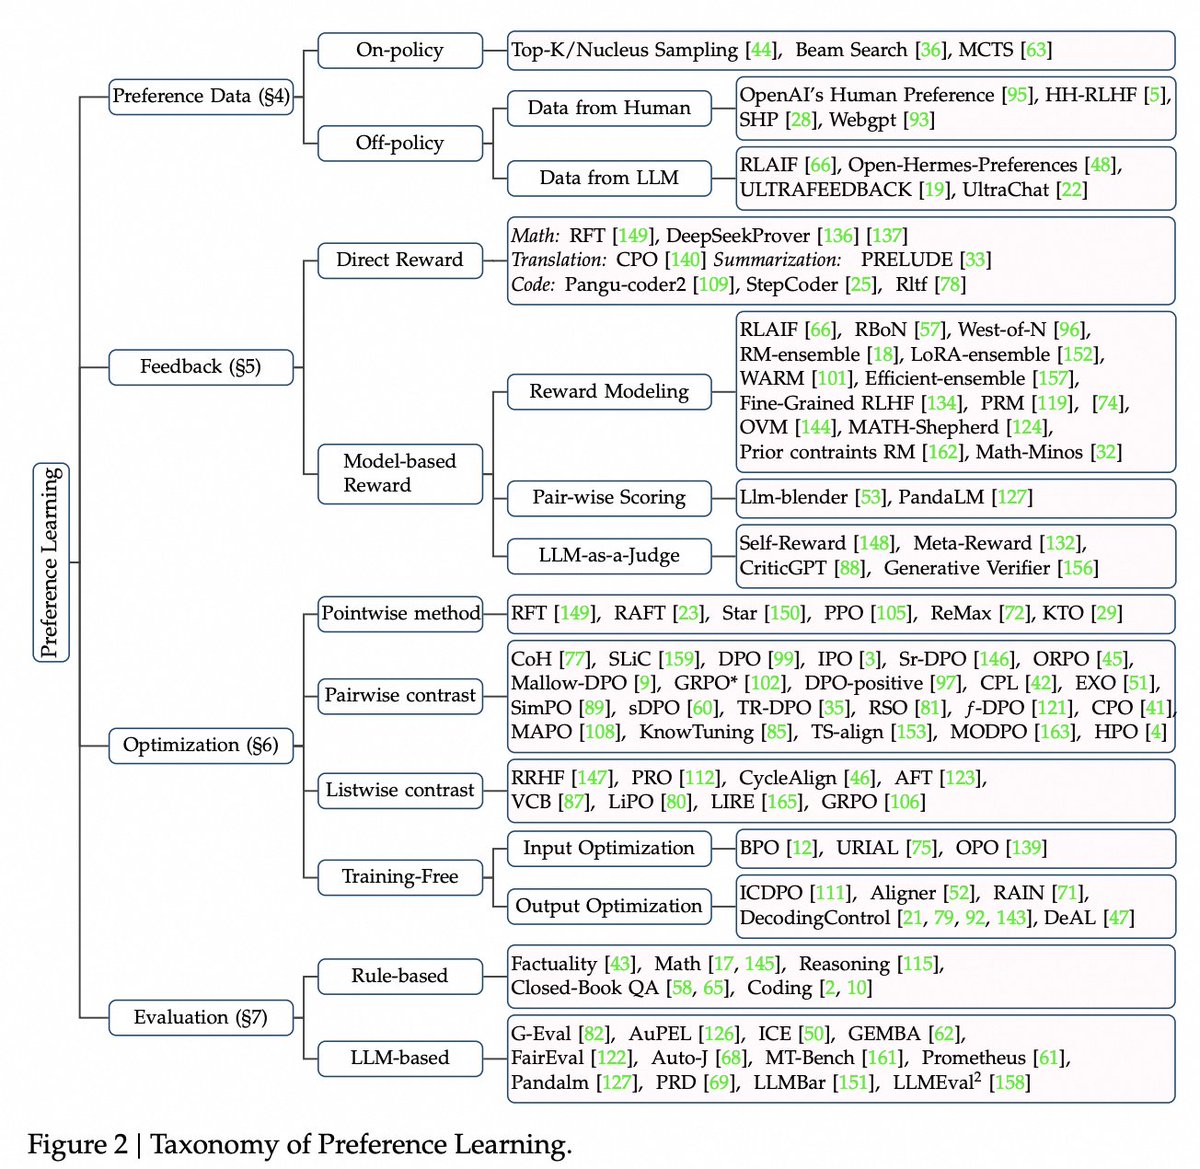
New survey: Towards a unified view of preference learning for LLMs!
🧠 LLMs are powerful, but aligning them with human preferences is key. This survey breaks down existing alignment strategies into four components: Model, Data, Feedback, and Algorithm.
🔗 This unified view reveals connections between different methods and opens doors for synergistic solutions.
🚀 Explore the challenges and future directions of aligning LLMs with human preferences.
Paper: https://t.co/PQMt3OFzvk
Github: https://t.co/CqlRu3N6ar
Notion Blog: https://t.co/9AkC6ItDol
#LLMs #AI #PreferenceLearning #Survey #MachineLearning
📢 After 3 months, the AI Mathematical Olympiad (AIMO) on Kaggle has announced the winners! 🎉
We're thrilled to see the Top 4 teams all chose DeepSeekMath-7B as their base model, with Numina @JiaLi52524397 achieving 29/50 correct answers! 👏 Even Terence Tao was amazed. 🤯
DeepSeekMath proves its worth for IMO candidate standards. 🌟
https://t.co/wokaAjwNV7
#AIMO #DeepSeekMath #Kaggle #AIMathOlympiad
DeepSeek-Coder-V2: First Open Source Model Beats GPT4-Turbo in Coding and Math
> Excels in coding and math, beating GPT4-Turbo, Claude3-Opus, Gemini-1.5Pro, Codestral.
> Supports 338 programming languages and 128K context length.
> Fully open-sourced with two sizes: 230B (also with API access) and 16B.
#DeepSeekCoder
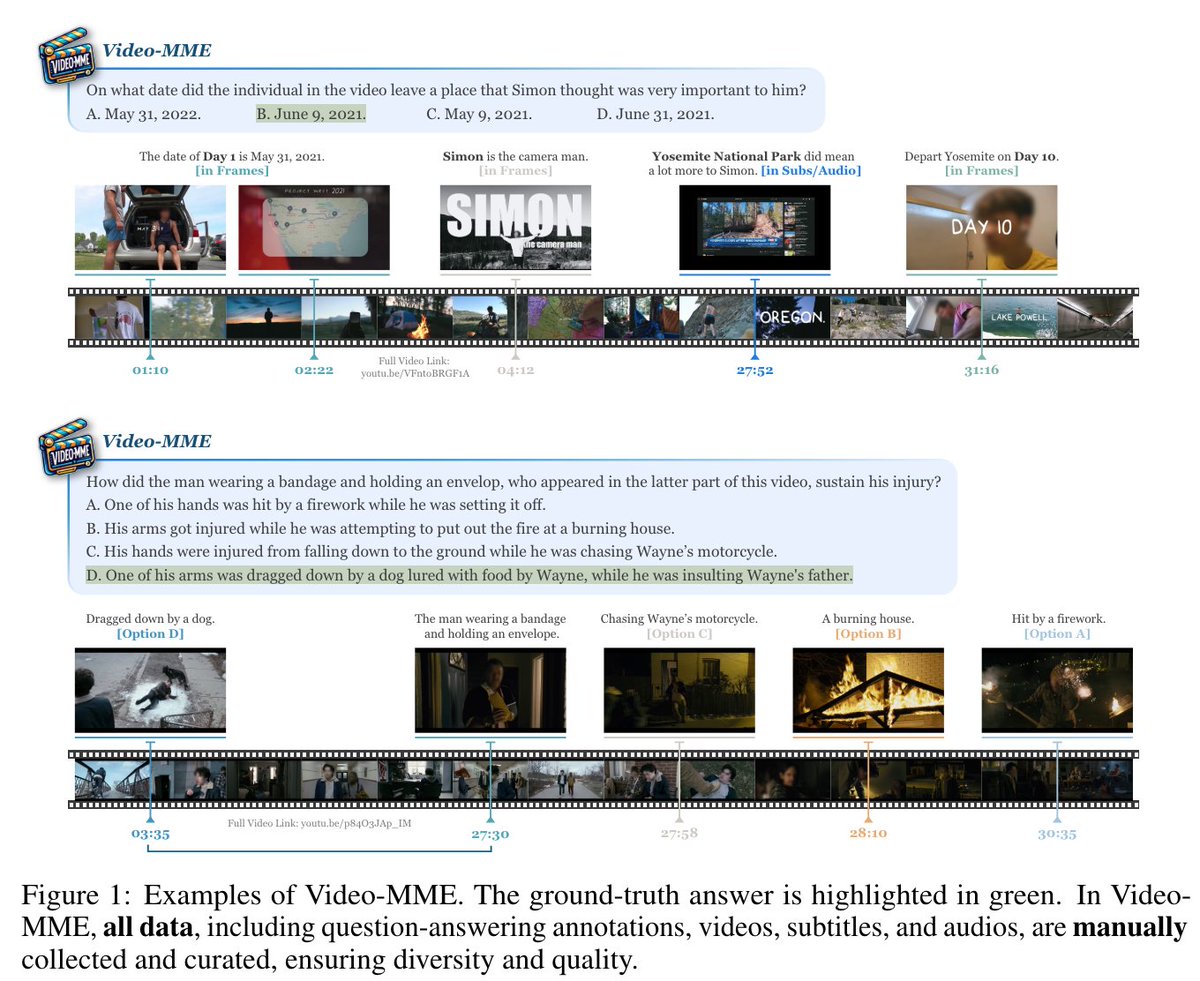
🚀 Excited to announce our latest project, Video-MME! 🎥
We've developed the first-ever comprehensive evaluation benchmark for Multi-modal LLMs in video analysis.
Project Page: https://t.co/KugodVGCmQ
Code: https://t.co/jknQ5KGBbT
🚀 Launching DeepSeek-V2: The Cutting-Edge Open-Source MoE Model!
🌟 Highlights:
> Places top 3 in AlignBench, surpassing GPT-4 and close to GPT-4-Turbo.
> Ranks top-tier in MT-Bench, rivaling LLaMA3-70B and outperforming Mixtral 8x22B.
> Specializes in math, code and reasoning.
> 128K context window supported.
✨ Features:
> Innovative architecture with 21B active parameters out of 236B.
> Unbeatable API pricing, while remaining truly open-source and commercial-free.
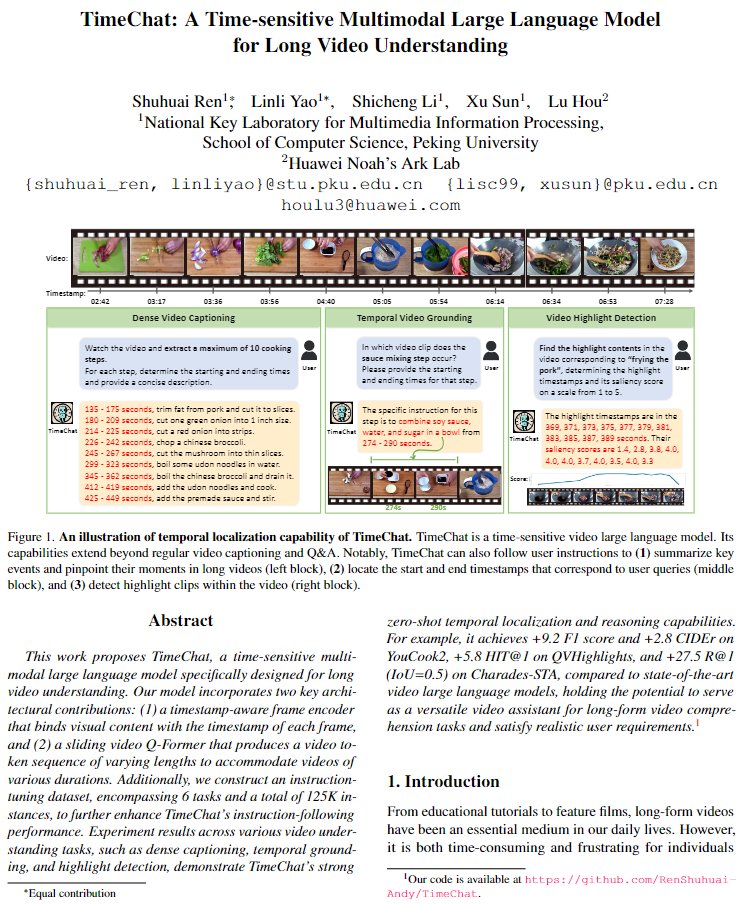
🎉Thrilled to share that our TimeChat has been accepted by #CVPR2024!
TimeChat: A Time-sensitive Multimodal Large Language Model for Long Video Understanding
arxiv: https://t.co/rtNskp1K35
code: https://t.co/gByfipUS7q