@bengalurupost1 This is only for commuters for travelling towards Hebbal. Sometimes I take the BMTC buses towards KR Puram/Tin Factory whose stop is down, alight down at the stop after Nagwara flyover, take the pedestrian bridge to cross the Ring Road, and then take the bus towards Hebbal.
Writing this as an Indian who works on AI in leadership role for one the largest companies in the world (though strictly my personal opinion, but based on verifiable data).
You heard it first here:
—————————-
First some more shocks:
You heard DeepSeek.
Wait till you hear about Qwen (Alibaba), MiniMax, Kimi, DuoBao (ByteDance) all from China.
Within China, DeepSeek is not unique and their competition is close behind (not far behind).
IMHO, China has 10 labs comparable to OpenAI/Anthropic and another 50 tier 2 labs.
The world will discover them in coming weeks in awe and shock.
AI is not hard (I am not high)
————————————
Ignore Sam Altman.
Many teams that built foundation models are below 50 persons (e.g. Mixtral).
In AI, LLM science part is actually quite easy.
All these models are “Transformer Decoder only models”, an architecture that was invented in late 2017.
There are improvements since then (flash attention, ROPE, MOE, PPO/DPO/GRPO), but they are relatively minor, open source and easy to implement.
Since building foundation models is easy and Nvidia is there to help you (if not directly, then by sharing their software like “Megatron” that is assembly line to build AI models) there are so many foundation models built by Chinese labs as well as global labs.
It is machines that learn by themselves…if you give them data & compute. This is unlike writing operating system or database software. Also, everyone trains on same data: internet archives, books, github code for the first stage called “pre-training”.
What is part is hard then?
———————————-
It is the parallel & distributed computing to run AI training jobs across thousands of GPUs that is hard. DeepSeek did lot of innovation here to save on “flops” and network calls. They used an innovative architecture called Mixture of Experts and a new approach called GRPO. with verifiable rewards both of which are in open domain through 2024.
Also, there is lot of data curation needed particularly for “post training”
to teach model on proper style of answering (SFT/DPO) or to teach them learn to reason (GRPO with verifiable reward). STF/DPO is where “stealing” from existing models to save cost of manual labor may happen.
LLM building is nothing that Indian engineers living in India cannot pull off. Don’t worry about Indians who have left. There are plenty in the country as of today.
Then why India does not have foundation models?
———————
It is for the same reason India does not have Google or Facebook of its own.
You need to able to walk before you can run.
There is no protected market to practice your craft in early days. You will get replaced by American service providers as they are cheaper and better every single time. That is not the case with Chinese player. They have a protected market and leadership who treats this skillset as existential due to geopolitics.
So, even if Chinese models are not good in early days they will continue to get funding from their conglomerates as well as provincial governments. Darwinian competition ensures best rise to the top.
Recall DeepSeek took 2 years to get here without much revenue. They were funded by their parent. Also, most of their engineers are not PHDs.
There is nothing that engineers who built Ola/Swiggy/Flipkart cannot build. Remember these services are second to none when you compare them to their Bay Area counterparts. Also , don’t trivialize those services; there is brilliant engineering to make them work at the price points at which they work.
Indian DARPA with 3B USD in funding over 3 years
———————-
What we need is a mentality that treats this skillset as existential. We need a national fund that will fund such teams and the only expected output will be benchmark performance with benchmarks becoming harder every 6 months . No revenue needed to survive for first 3 years.
That money will be loose change for GOI and world’s richest men living in India.
@protosphinx@balajis@vikramchandra@naval
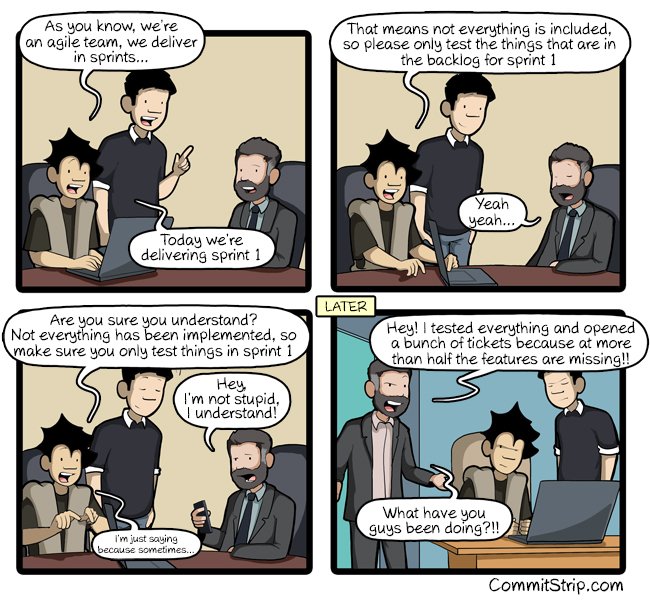
Absolutely! "The teams behind the product" should rethink on strategies if it can grow big on complex features. Focused feature centric products are built on lot of assumptions and extending these for new frontiers is an invitation to failure!
Products start small and focused:
They do one thing really well — and that’s the reason they succeed..
Years later, the team behind the product comes to the conclusion it has to do more. Features are added, new use cases covered, more sophisticated functions.
And then...
Happy #PiDay! #DidYouKnow: Rajveer Meena holds the record for reciting the most number of decimal places of pi. He was able to recite 70,000 decimal places over ten hours.
How many digits of pi can you recite?
“Hello World & Happy New Year!”
Today, we celebrate the birth of Brian Kernighan, Bell Labs alumnus who created the 1st Hello World software program. Retweet if you use Hello World & share your most creative #HelloWorld examples! #OTD#ThisDayinSTEM #2019 https://t.co/WsJwbczX6B
The @OnePlus#clipboard app contains a strange file called badword.txt 🤔
In these words, we can find: Chairman, Vice President, Deputy Director, Associate Professor, Deputy Heads, General, Private Message, shipping, Address, email, ...
https://t.co/ePQvD1citn
The world's smallest GSM BTS back in 1995, Nokia PrimeSite supported 1 GSM TRX & required a maximum of 256kbps of backhaul, assuming 64kbps each for O&M & TRX signalling. This one was installed as a test node in an Orange switch site, operating on ARFCN 865 #historyoftechnology