I would bet a lot of this has to do with the B300 inventory being unavailable with near term RFS. The lead times shifted from 8 weeks to 14+ weeks overnight last week as Nvidia deprioritizes B300 for VR production
Introducing Silicon Exchange (@silicon_exch) a new way to finance the GPUs powering AI.
Anyone can now help bring new compute online by financing GPU clusters. AI companies rent and put the hardware to work, with the economics flowing back to those who financed it.
Under the hood, the financial stack runs on Stripe, Tempo, Privy, and OUSD.
Check it out here: https://t.co/rU8Rabb8Oq
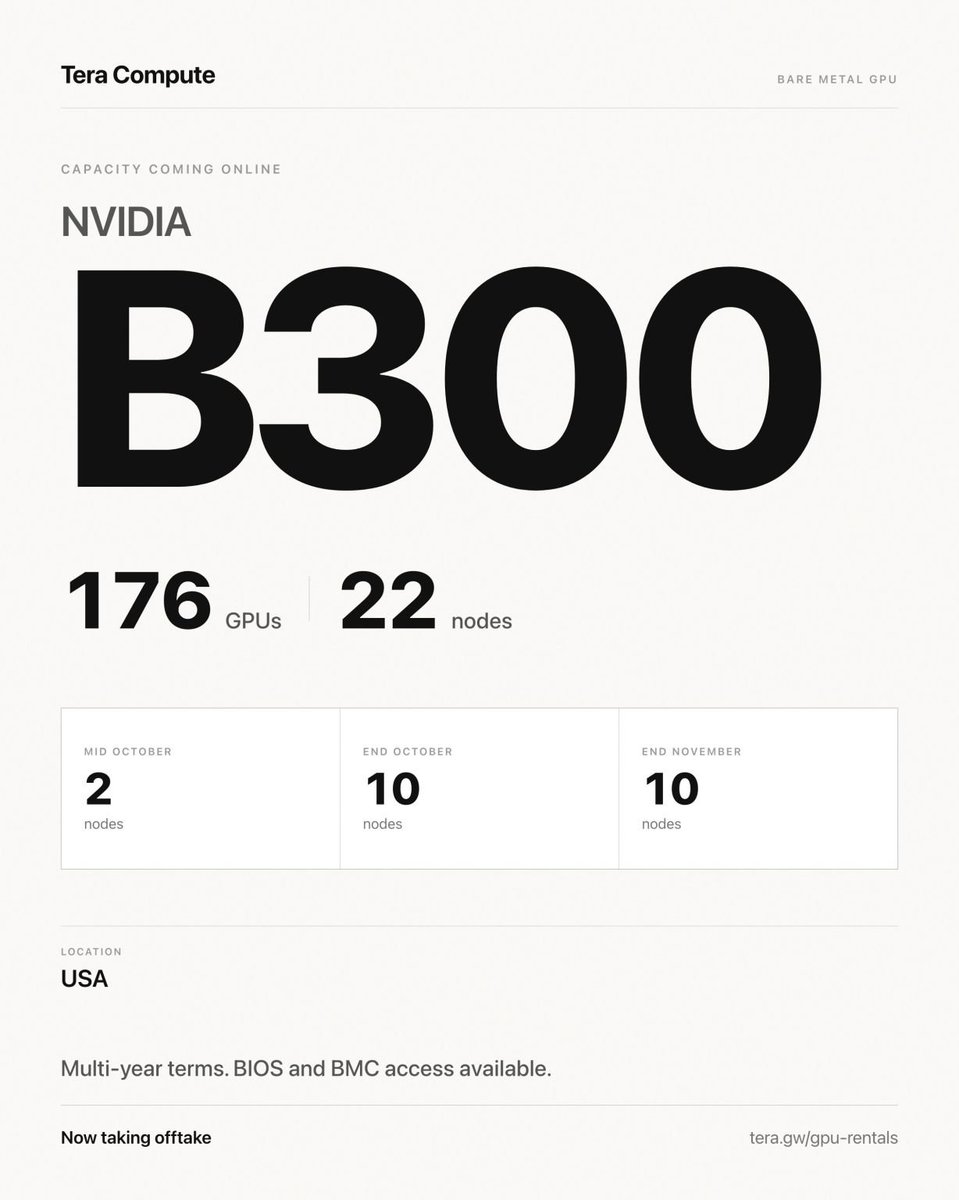
176 NVIDIA B300 GPUs coming online this October.
22 nodes across three tranches through end of November. Dedicated bare metal, 8x 800G InfiniBand, US. BIOS and BMC access available.
We are taking offtake conversations now. If you need dedicated Blackwell on a multi-year term, message us.
Client of ours has 48 b300 nodes deploying in approx 12 weeks and is looking for backup offtake. If anyone needs to lock down rentals before this next supply crunch, DM
Thinking about adding x402 to Tera so agents can pay per inference call in USDC. No signup, no API key, just hit the endpoint and go.
Before we build it: would you use it?
Context: x402 is an open standard built on HTTP 402. Server returns a price, client pays in stablecoin, retries, gets the response. No account, no dashboard, no key to rotate.
For inference that means an agent buys its own tokens with no human in the loop.
https://t.co/wPs5fvqhGk
Thinking about adding x402 to Tera so agents can pay per inference call in USDC. No signup, no API key, just hit the endpoint and go.
Before we build it: would you use it?
@mynameisyahia Interested in using open weight models? We can provide all the compute you need. @teracomputecorp
US Based inference. We don't train on your data.
DM me for free credits
@quxiaoyin Power your agents with open weight models. Try @teracomputecorp
We convert bitcoin mining data centers to serve inference. We can deploy GPU's in data centers faster than anyone else can.
We never train on your data, US Based inference
Many smart people/AI insiders are saying GLM-5.2 is the first Chinese AI model to match and often beat the American big lab public AI models with no compromises. Incredible timing given current events.
Here’s a fun comparison between GLM 5.2 and Opus 4.8 on a one-shot reproduction of the SDPO paper
This is a hard task: the model must resolve messy verl issues and then run ablations to completion and confirm the paper’s claims.
- GLM 5.2 costs $6.21 while Opus 4.8 cost us $46.35
- Both models spent a bulk of their tokens resolving initial verl issues. GLM 5.2 attempted 14 failed runs before first success while Opus 4.8 attempted 9 runs.
- GLM 5.2 surprisingly took 2.65M tokens (excl re-reads) compared to 4.53M tokens for Opus 4.8