Stop getting cooked by API bills and silent model swaps.
Three Router gives you one unified gateway for all the top open-weight models (DeepSeek, Qwen, Kimi, GLM, MiniMax) with 100% LLM availability.
Why devs are switching:
🔌 Change one URL. Keep the rest of your OpenAI SDK code exactly as is.
🛡️ Multi-provider failover. If one API goes down, your requests keep flowing. Zero downtime.
🚀 DeepSeek V4-Flash: ~$1 per 30M tokens. Ridiculous speed, dirt cheap.
The launch perks:
✅ $10 free credit for new users
✅ Top up $10, get $100 free.
✅ Refer a friend, get $6.
Link in bio. Come poke at it, and DM me if anything breaks—I read every message.
[https://t.co/DN2jGJzieM]
#AI #OpenAI #DeveloperTools #LLMAPI #ModelRouting
DHS 🔥: federal civilian agencies have 60 days to remove DeepSeek from their systems. and here's the part most coverage is missing:
The directive covers all third-party products BUILT ON DeepSeek weights, not just DeepSeek itself. remove or request a written waiver within 60 days.
So any vendor shipping a fine-tune or a downstream tool on those weights just found out their supply chain is a compliance problem. overnight.
Whatever you think of the policy, the engineering lesson is the same one from every silent checkpoint swap: if your stack hard-depends on one model family, somebody else gets to break your roadmap. swap layers exist for a reason. 👀
#DeepSeek #AIAPI
@SidharthVijay_ $2 Trillion with less revenue than 35 SaaS companies combined? That’s not a revolution, that’s a spreadsheet glitch. 😂 The real revolution is that I can get 90% of Claude's coding ability for pennies using open models.
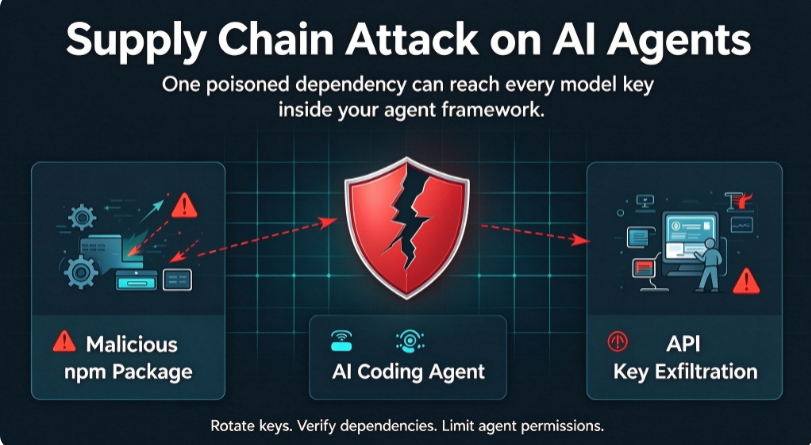
Spent part of my morning reading the elastic writeup on this npm campaign and the bait design is honestly clever.
Fake "web3 accelerator" tools that promise free AI credits. you install the npm package, you get an infostealer plus a backdoor. but the part that got me: the backdoor specifically hijacks traffic from AI coding agents running on your machine and harvests the API keys they use.
Think about that. your agent framework holds the keys to your openai account, your anthropic account, whatever gateway you route through. one poisoned dependency and all of it quietly walks out the door.
It's the same lesson as the opencode leak last week but worse, because now the attacker doesn't even need to find your keys. your own agents will hand them over. i rotate my keys monthly and i'm starting to think monthly isn't enough.
#npm #AIAgents #DevSecurity
@buswe_com Price-based sorting is a must-have. Just need to make sure the cheap host doesn't fumble the tool calls. A dynamic router that balances both is the endgame.
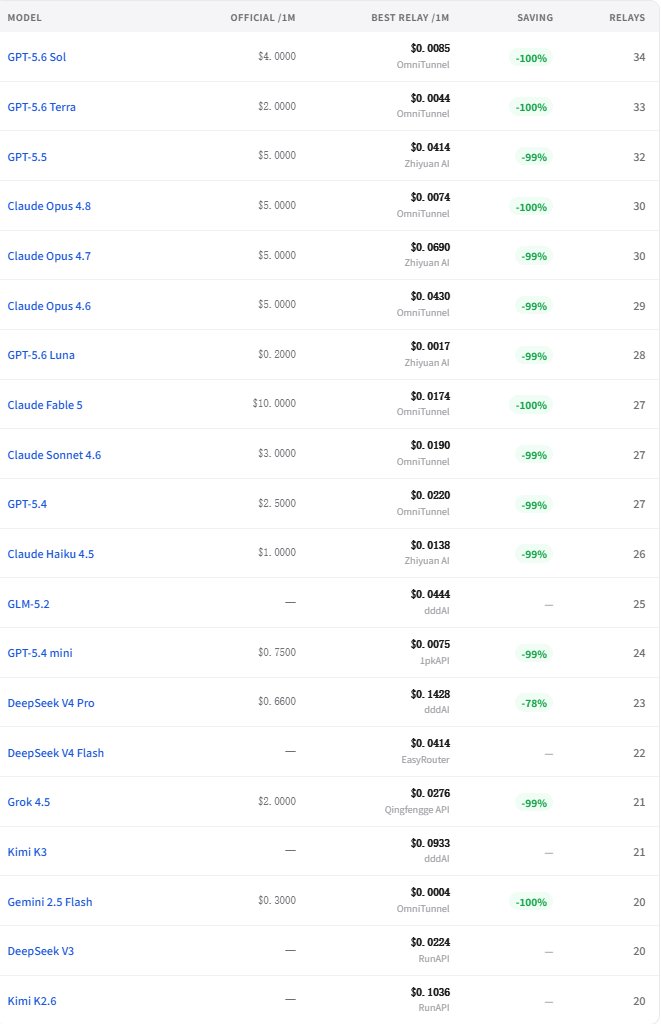
Oct 19 was a price earthquake for api models and almost nobody noticed.
Same day on openrouter: llama 3.3 70b output -59% (0.79→0.32). glm 4.7, nemotron 3.5 super vl, deepseek v4 flash all cut. but gemma 4 26b went +33% and deepseek-v4-pro jumped +208% on the same day.
Lock to one provider and you either ate the hike or missed the drop. a unified gateway just shows you the delta and routes to the cheaper one. been saying this for a while.
#API #LLMpricing
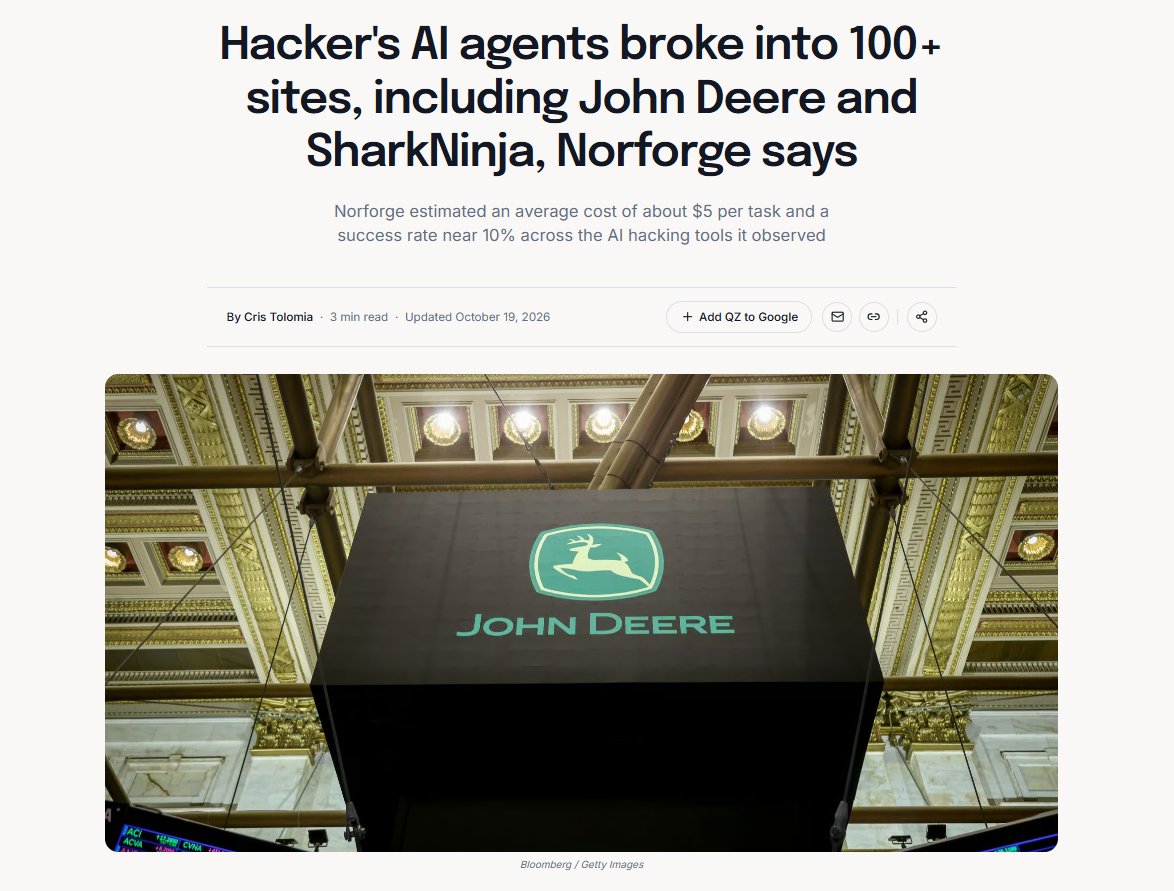
Just read the reuters piece on the cairn operation and i genuinely had to put my phone down.
One guy. an open source agent platform. instructions under 100 characters. the swarm autonomously tried 1,200+ websites and got into 100+ of them. john deere, sharkninja, cummins all confirmed.
Total cost: about 5,000 in tokens. ~50 per successful breach. roughly 23 hours each. the workers were literally labeled claudecode_deepseek-v4.1-flash — claude code as the harness, deepseek as the brain.
And the guy barely touched anything himself. the researcher's words were "it's not script kiddie stuff." one person with an api budget just out-hacked entire security teams. 😳
If your security plan assumes the attacker is writing every exploit by hand, that plan is done. wake up call doesn't get louder than $50 a pop.
#AIAgents #CyberSecurity
The web is starting to lock its doors to agents.
A major bank and a major airline now block autonomous agents from touching accounts and bookings. A business-review site restricts agent access to paying data partners. Cloudflare is pushing harder on anti-bot. This follows the same week banks capped internally funded agent spend.
None of this is anti-AI theater. It's the bill for giving agents broad credentials and letting them scrape instead of call APIs. Sites see unbounded automated load and treat it as abuse.
The path through the wall is routing, not scraping: API access with identity, rate limits, and billing attached. Whoever aggregates clean API access wins the agents that actually ship.
#AI #AgentAccess
Another provider just made your current API bill look expensive. minimax M3.1 Flash dropped last night.
200+ tok/s, nearly 3x the previous gen. this thing is built for agent workloads, not just chat.
The agent numbers are what got me: 73.7% on DeepSWE v1.1 and 82% on CyberGym. not a chat toy.
The pricing is the part that actually matters: 0.15 in / 0.60 out / $0.015 cached, and they're claiming ~70% lower cost on agent-heavy tasks vs the last version. it's already on OpenRouter as :free.
Here's the bit that's getting old though: the weights are "planned." so right now you can only touch this through an API, and the only way to actually chase the low price before it drifts is to not be locked to one provider.
Catch the dip or eat the old rate. same story every time.
You routing it through a gateway yet, or still waiting on the weights to actually drop?
#AI #LLM #minimax
https://t.co/jYUWNrSMfg
Reflection dropped beam a few days ago, their first open-weight model. 501B total params, only 23B active per token, apache-2.0, 1M context. built for coding and long agent runs.
The part that's actually impressive: SWE-bench verified ~81%, terminal-bench 80.1%, AIME 2026 97.8%. and they claim ~3x fewer inference tokens than similar open models. if that holds, it's the number that moves your api bill, not the bench scores.
The part nobody's leading with: 501B is still 501B. BF16 is ~1TB, you want 4x B200 to run it for real. "open" means you can self-host, not that it's cheap to. efficiency is measured against other open models, not the closed frontier.
But apache-2.0 is the reason i'd actually point a coding agent at it. nobody yanks the weights or silently swaps a checkpoint under you mid-deploy. for something touching your repo, that beats two points on a leaderboard. it's on openrouter day-0 if you'd rather just route.
#AI #ReflectionBeam
https://t.co/Nfl3Dq7yqc
A model trained to do autonomous ML engineering — plan the experiment, write the code, read the results, iterate — just dropped open weights. internScience, 35B moe, apache-2.0. this is the "AI improves AI" thesis finally shipping as a download, not a slide deck.
The number that got me: on MLE-bench lite it takes its base model from a 37.9% medal rate to 72.7%. that puts a 35B model on par with kimi-k3 and glm-5.3, which are way bigger. it got there by learning to run long experiments, not by being huge.
Under the claude code harness it lifts the base from 42.4% to 69.7%, so the skill transfers to the tools you already use.
And it's apache-2.0 — nobody's quietly swapping the weights out from under you mid-sprint, which is more than i can say for some closed apis i'm still paying for.
Spent this morning actually reading the paper instead of trusting the hype thread. if you build agents, this one's worth a real look. it's on HF.
#AI #MLExpert
https://t.co/akQSByvQqE
@jpschroeder Bro, 552B params means 99% of devs aren't running this on their MacBooks. "At home" really just means "through an API router that doesn't charge me Sol prices." 😂
Stop getting cooked by API bills and silent model swaps.
Three Router gives you one unified gateway for all the top open-weight models (DeepSeek, Qwen, Kimi, GLM, MiniMax) with 100% LLM availability.
Why devs are switching:
🔌 Change one URL. Keep the rest of your OpenAI SDK code exactly as is.
🛡️ Multi-provider failover. If one API goes down, your requests keep flowing. Zero downtime.
🚀 DeepSeek V4-Flash: ~$1 per 30M tokens. Ridiculous speed, dirt cheap.
The launch perks:
✅ $10 free credit for new users
✅ Top up $10, get $100 free.
✅ Refer a friend, get $6.
Link in bio. Come poke at it, and DM me if anything breaks—I read every message.
[https://t.co/DN2jGJzieM]
#AI #OpenAI #DeveloperTools #LLMAPI #ModelRouting
Openbmb open-sourced pilotdeck 2.0, an agent operating system, AGPL-3.0. local deploy, native MCP, mac/linux/windows + docker.
79.1 on workbuddybench, above claude code's 77.3.
Smart routing: planning to a strong model, execution and polish to a cheap one. their benchmark took a gnarly task from 18.36 (sonnet 4.6 solo) to 3.15, score up. ~83% cost cut, higher score.
White-box memory, you can view and edit what it remembers.
Runs fully local, no api key, no monthly bill — and it beats claude code on the same bench. the kind of release that makes you side-eye your anthropic invoice.
#AI #PilotDeck
https://t.co/d1jUjRVbxz