New paper! 📷
The brain's Multiple Demand (MD) network ramps up when tasks get hard, so its activity gets read as "effort", while meaning is left to the language network. But when you're following a tough lecture, is MD just working harder, or is it tracking the content?
🚨 New preprint!
One idea, many ways to say it – does your brain track those options before you speak?
Using LLMs, we put this to the test:
https://t.co/rCRvuPwDtT
We show for the 1st time that the brain represents many alternatives simultaneously in both listening & speaking 🧵
📢Paper release📢
What computation is the Transformer performing in the layers after the top-1 becomes fixed (a so called "saturation event")? We show that the next highest-ranked tokens also undergo saturation *in order* of their ranking.
Preprint: https://t.co/ovwI9JpiAQ
1/4
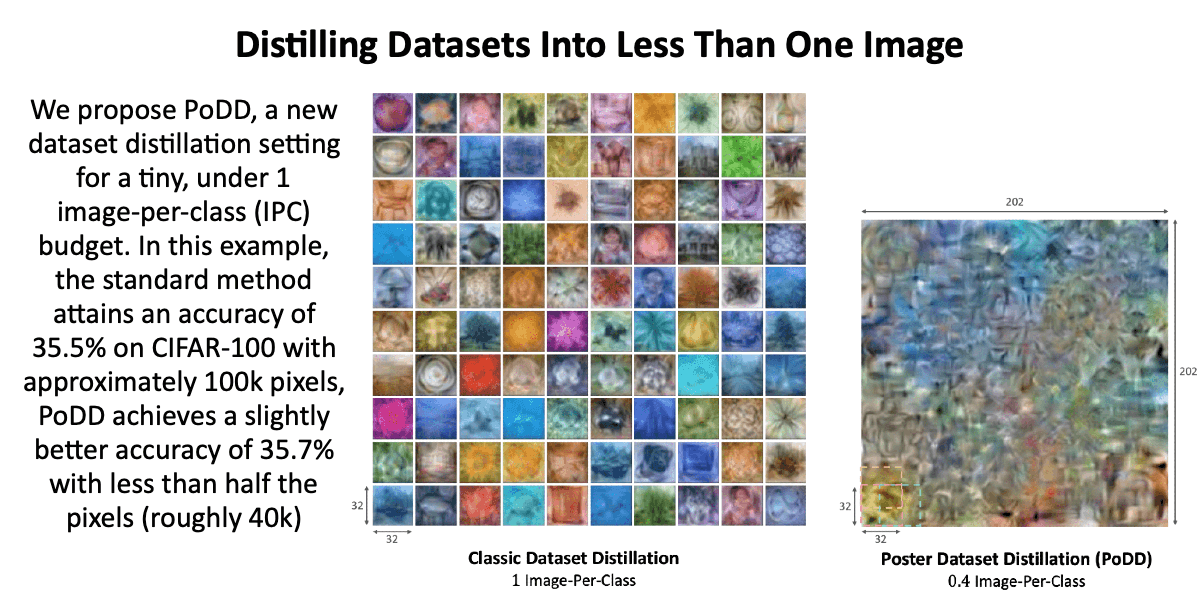
🚨New Dataset Distillation paper 🚨
We propose PoDD, a new dataset distillation setting for a tiny🤏under 1 image-per-class (IPC) budget❗In this CIFAR100 example, current SoTA is 35.5% acc using ~100k pixels, PoDD gets 35.7% with ~40k pixels
Project: https://t.co/8ZI2qBI7bl
🧵👇
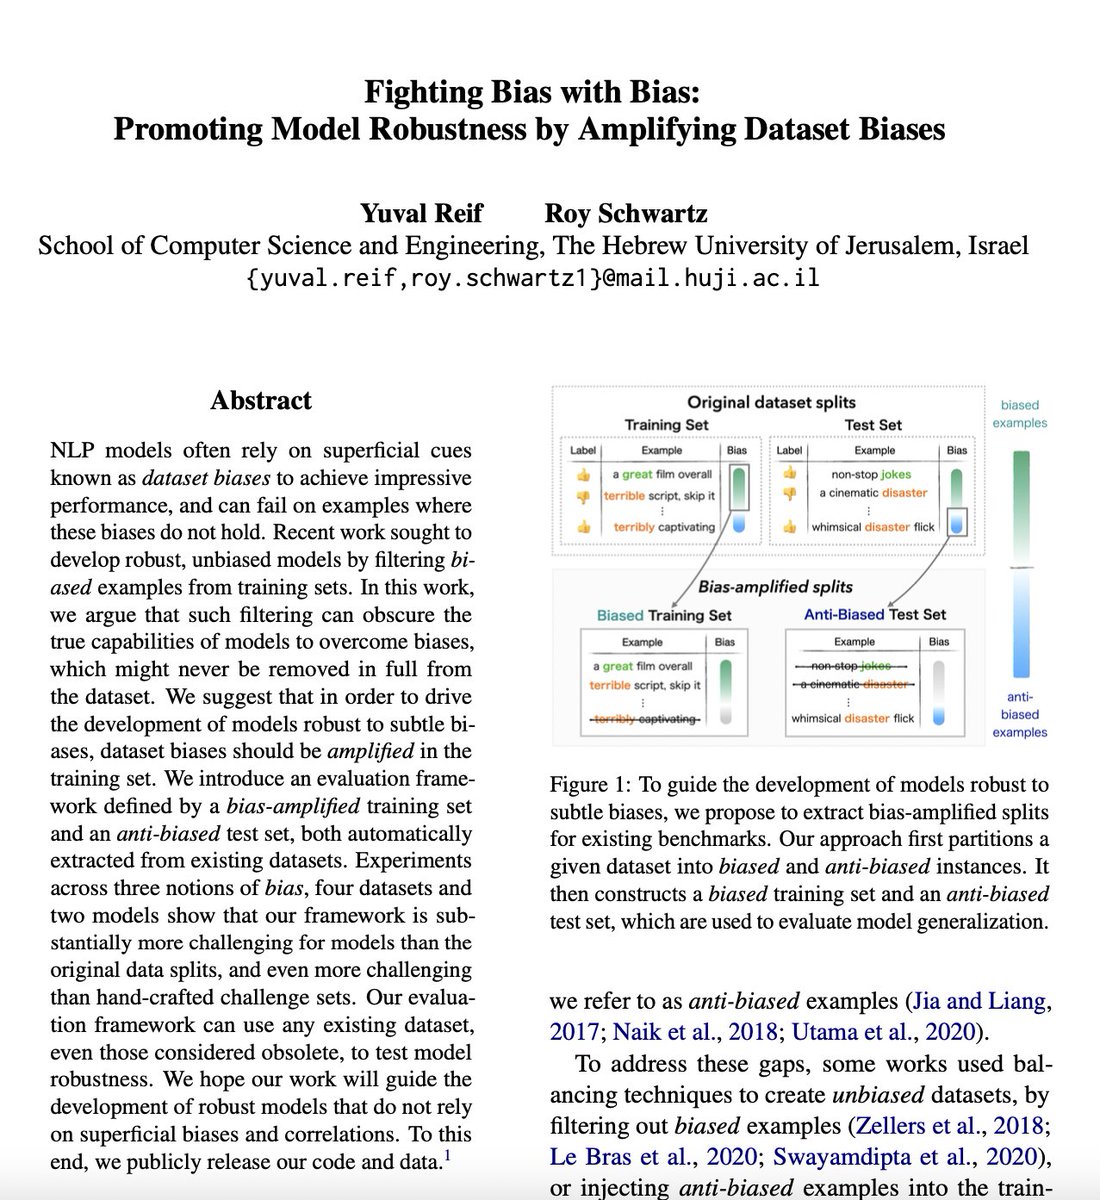
Is dataset debiasing the right path to robust models?
In our work, “Fighting Bias with Bias”, we argue that in order to promote model robustness, we should in fact amplify biases in training sets.
w/ @royschwartzNLP
In #ACL2023NLP Findings
Paper: https://t.co/zYP6FuVpe9
🧵👇
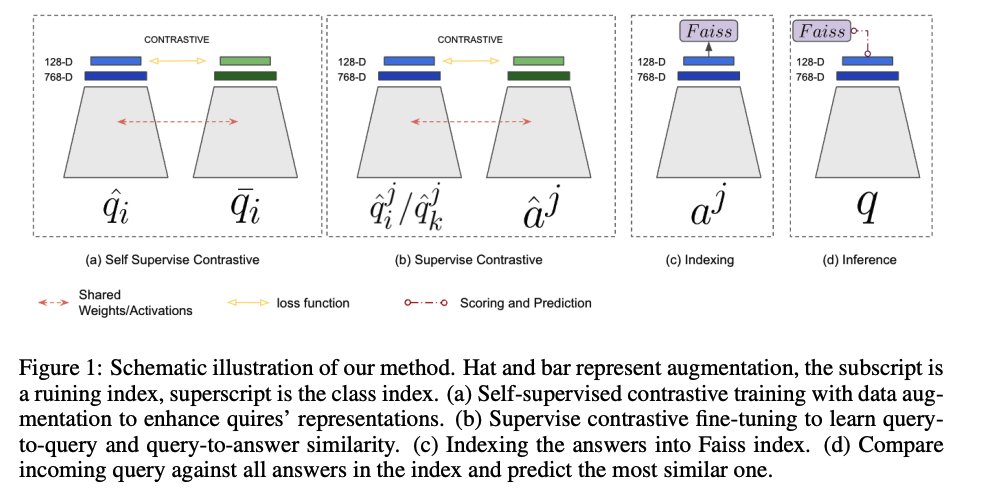
Looking for a new SOTA few-shot classifier?
We present QAID!
QAID uses batch contrastive learning with BERTScore &
classifies by retrieving the intent name.
SOTA on few-shot Intent Detection! 🎉
https://t.co/bMxNHwO0gc
Accepted to @iclr_conf 2023 🥳
#NLProc#NLP#ML
Google announces Dreamix: a model that generates videos when given:
- video + prompt (Video editing)
- input images + prompt (Subject Driven Generation)
- input image + prompt (Image-toVideo
Dreamix: Video Diffusion Models are General Video Editors
abs: https://t.co/It6BuYHU8c
project page: https://t.co/Tks6bU4kmb
present diffusion-based method that is able to perform text-based motion and appearance editing of general videos
Happy to share our paper "DeepSIM: Image Shape Manipulation from a Single Augmented Training Sample" was accepted as an 𝗼𝗿𝗮𝗹 presentation at #iccv2021
Paper: https://t.co/jbScyR81KM
Project: https://t.co/s3fCOtuVil
Code: https://t.co/0hxeja8Vvy
@YVinker Nir Zabari @YHoshen