BUYER BEWARE
This extremely meticulous article will now be used to start Phase2 of “shut down open source” because “if we can’t control our closed models, imagine what happens to everyday life when anyone can just allow their open source models to proliferate”.
Some will use this example and point to future grid outages, utility outages, transportation chaos, bioweapons, uncontrolled cyber swarms and the like to try and make the case for yet another attempt to limit US AI model control to a few folks.
Then, one layer beneath the propaganda, one sees that these things are always written and promoted by a web of well organized existing shareholders or shareholder-adjacent of the closed frontier labs and groups of folks organized by a shared ideology roughly rooted in them knowing best.
This article, more than anything else, should demarcate the beginning of a well organized effort to stand up a Closed Model Industrial Complex. These cartels exist in other markets as well and it now exists in AI.
Bottom line, read everything carefully before signing up for the consequences.
How we react will define the next hundred generations of Americans and their lives.
Do not give up your rights or sovereignty because of fear of the unknown from articles that, at the root, are as much about the hidden incentives of an emergent cartel and their proxies.
If you take the time to understand the incentives, you will be less likely to fall for it and overreact and have intelligence metered from a few suppliers.
Bottom line: Keep Calm. Carry On.
Excellent work by @apagajewski and team, a promising first step in the ambitious journey to solve general physical problems. Plus the goal dance is cute. Am a fan of Pan 🙌
Introducing Pan-1, a highly capable Minecraft model trained with an RL-based pretraining technique that could unlock internet scale video for robotics models.
It can achieve diverse goals—fight mobs, build structures, explore—without training on any of them specifically.
Happy to share what I've been cooking over the past months as a part of a stellar team at @essential_ai labs: we bring to you Rnj-1 (h/t Ramanujan), the best USA 🇺🇸 open-source LLM in the 8B category - fully pretrained, midtrained, and posttrained from scratch on zettaflops of AMD (one of the largest AMD training clusters in the world) and TPU compute!
We are releasing our base model, and our post-trained checkpoint on HuggingFace - to help you squeeze the absolute most out of post-training for your particular use case.
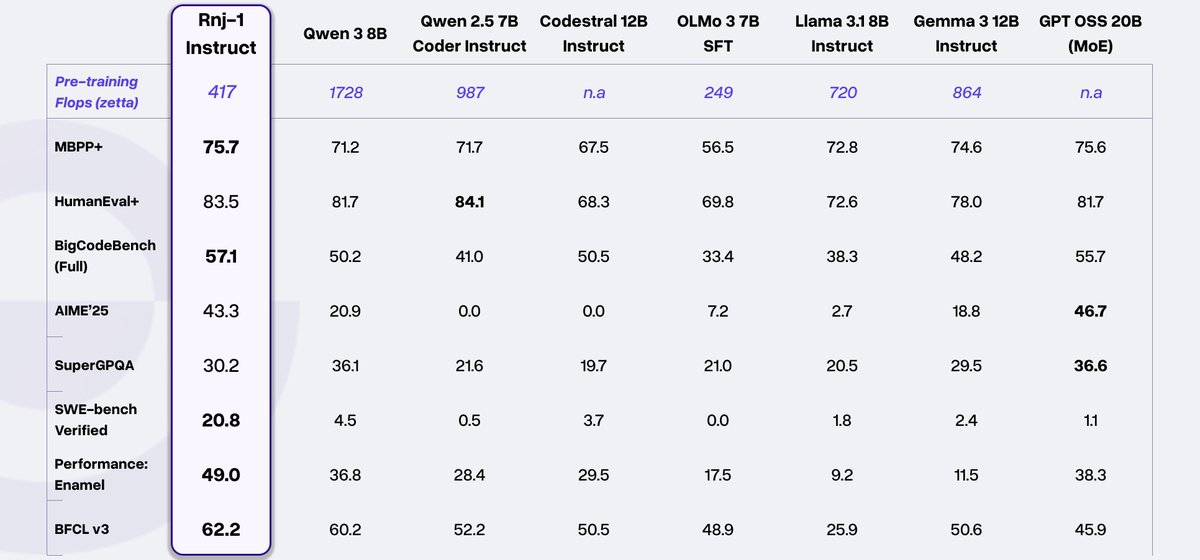
Our initial evaluations show that Rnj-1 is very strong at code, math, and tool calling.
On SWE-Bench it's an order of magnitude stronger than comparably sized models - It scores 20.8% on SWE-bench Verified in bash-only mode, which is higher than Gemini 2.0 flash and Qwen2.5-Coder 32B Instruct and on par with GPT-4o (!) under the same agent framework.
Rnj-1 was pretrained on 8.4T tokens with 8k ctx len. Followed by 380B tokens in midtraining, and a 150B SFT stage to get rnj-1-instruct. We used Muon as the optimizer. Tech report coming soon, but see our blog until then.
As the AI world drifts to whatever "the current thing" is (at this moment in time that's RL), we're going back to first principles and focusing squarely on pretraining. We believe that many behaviors people assume only emerge during post-training can actually emerge during pretraining -> if you cook the model the right way. :)
On a side note - being part of a very small (~20 members of technical staff), tightly knit, hard-working, extremely ambitious team that's working in the same physical space (!!!) is so fun. I was in the office until 2:30 a.m. last night pushing out our latest eval numbers, and a few of my colleagues pulled an all-nighter to help prepare for today's launch!
Due to our size, and my background, I feel I’m in a rare position (looking at the AI labs LLM landscape as a whole) because i got to work on the whole LLM pipeline: from our infra, in-house Spark pipelines, and the data analysis engine (did i tell you to look at your f***ing data already?) to data collection/synthesis, data mixing, training experiments, and - last but not least - evals.
As a bonus, getting to distill tokens from @ashVaswani on a daily basis is rewarding (we met at a small event w Satya earlier this year).
Conspicuously missing from our upcoming tech report are any Transformer modifications, which might come as a surprise given our team.
It’s all about research taste and making bets - in our case, that is pretraining, simulating program behaviors..
The easiest way to run Rnj-1:
* laptop -> llama.cpp or transformers
* your infra -> vLLM, Sglang
* IDEs and Agents with Cline extension -> vs code / Cursor or try claude code router
Happy to see what you build with it! My dms are open.
It's a good model, sir. 🫡
Today marks the release of Rnj-1, EssentialAI's first model release. Despite the great joy that it brings to finally share our work, this is just the beginning. Our focus remains fixed on pushing the frontier of open-source American AI, making the most of this great opportunity. Very proud to be part of this team!
We are beyond thrilled to share our first flagship models, Rnj-1 base and instruct 8B parameter models. Rnj-1 is the culmination of 10 months of hard work by a phenomenal team, dedicated to advancing American SOTA OSS AI.
Lots of wins with Rnj-1.
1. SWE bench performance close to GPT 4o.
2. Tool use outperforming all comparable open source models.
3. Mathematical reasoning (AIME’25) nearly at par with GPT OSS MoE 20B.
….