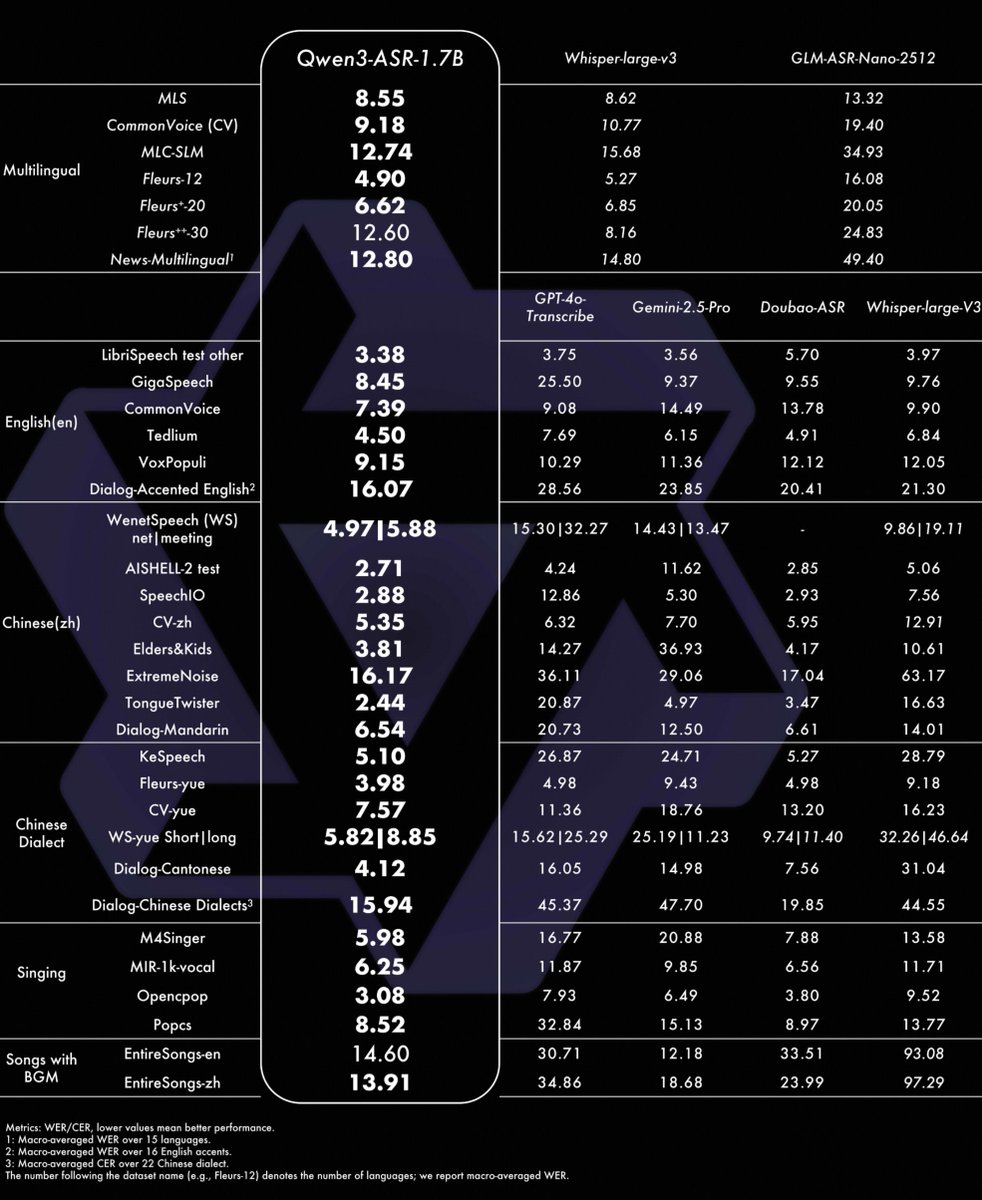
Qwen3-ASR and Qwen3-ForcedAligner are now open source — production-ready speech models designed for messy, real-world audio, with competitive performance and strong robustness.
● 52 languages & dialects with auto language ID (30 languages + 22 dialects/accents)
● Robust in noisy and complex settings (yes, singing and songs too)
● Long audio support: up to 20 minutes per pass
● Word/phrase-level timestamps: high-precision alignment for 11 languages via Qwen3-ForcedAligner, stronger than MFA/CTC/CIF-style aligners
Also included: a full open-source inference & finetuning stack with vLLM batch, streaming, and async serving.
GitHub: https://t.co/yxxUTTIjLr
Hugging Face: https://t.co/38fny0K2Qz
ModelScope: https://t.co/0fAIFksAwv
Hugging Face Demo: https://t.co/GbLHOn7hdD
ModelScope Demo: https://t.co/Jvb2kfnHr5
Blog: https://t.co/yP6VbGc7bg
Paper: https://t.co/zzlFgwcP1E
🔉 Introducing SAM Audio, the first unified model that isolates any sound from complex audio mixtures using text, visual, or span prompts.
We’re sharing SAM Audio with the community, along with a perception encoder model, benchmarks and research papers, to empower others to explore new forms of expression and build applications that were previously out of reach.
🔗 Learn more: https://t.co/FPnfv66UCP
Again very happy to see launches powered by Gemini Native Audio Output capabilities, where Google DeepMind team members in Tokyo🗼 made significant contributions!
Text-to-Speech: https://t.co/mGqMFJ5Ejq
Dialog: https://t.co/xdjV1EPR1V
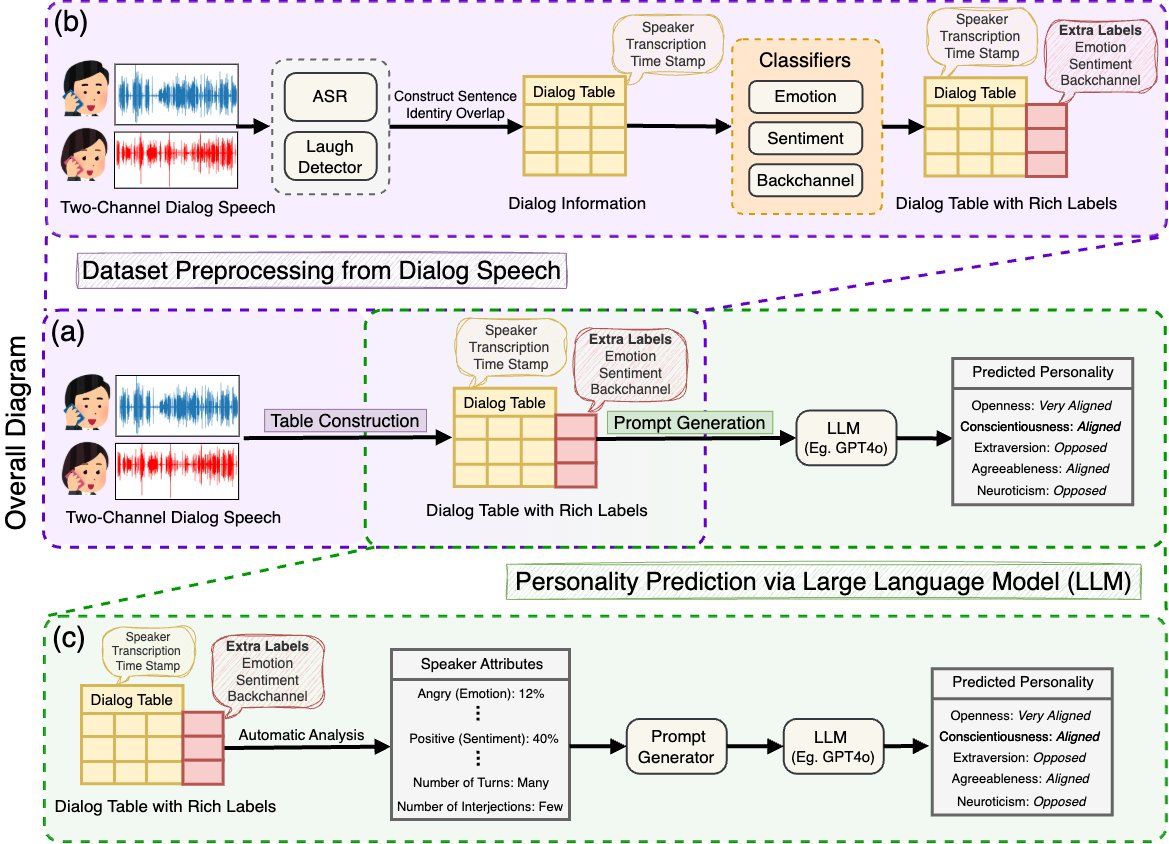
Our paper has been accepted to #INTERSPEECH2025! We propose an automatic pipeline to predict conversation personalities from fully-duplex speech dialogs.
Hope to see you in the Netherlands, Hoi 🇳🇱
Project Page: https://t.co/Jai0psWFjP
Paper: https://t.co/vjL5PEfhyw