@QuinnyPig@max_spero_@ByrneHobart I dunno. I'm neither for or against anything or anyone mentioned here. But I feel the prose does a good job humanizing what's being said. I never thought when reading it that the portrayal made him look dumb. I quite liked this style of reporting. It feels more authentic.
@mikejulian Having worked in DX for a while, I can sense from the outside whether a product team knows what it's doing and where they are going strategically. Once I saw Codex passing that bar, I stopped looking elsewhere for a harness. But I see shallow AI DX all over the place elsewhere.
@mikejulian Very happy using Codex, no real special sauce beyond that. Except notifications back to my phone don't work, so I had it make a hook to notify my via slack. But otherwise, it's been great.
How many people run an AI coding assistant on their laptop while their live cloud creds are *just sitting there*, available for use. I've scared a number of eng leaders just by pointing this out as a threat vector they never considered...
How many of you out there are letting AI agents run privileged commands against your production infrastructure?
Be honest, I see enough "AI dropped my DB" posts to know that it's happening.
My engineering colleagues who built the original New Relic Browser were, I think, history and english grads. We were doing groundbreaking DOM instrumentation, stuff you'd think might be driven by CS grads. Diversity of thought / experience is so valuable!
One of the things I loved working at Google was asking about the oldtimers’ fascinating backgrounds.
The guy who led one of the Cloud OSS teams had been a circus trapeze artist, iirc.
Alas, over time the standard-elite CV (ivy, internships) has become more prevalent there
@QuinnyPig I typed dreambeans in safari on my phone. It autocompleted to dreambeans .net (had to add a space to make sure it didn't link). It appears NSFW (I bailed at the age verification popup). How does Google launch an app with these kinds of branding problems?!
@cyber_rekk Building network-layer AI sandboxing for assistants and workloads. Think MITM TLS proxy for all outbound connections, but not actually a MITM proxy via "magic sauce" :). Private engagements with pilot customers as we iron out the early stage kinks at https://t.co/wwKGosvd8X.
@QuinnyPig@lydiahallie@AnthropicAI I've also heard usage from OTel may not match up with what's reported by AI vendors? Not sure if that's true for Anthropic when used directly. We've also seen different levels of fidelity between emitted OTel and what's in requests/responses on the wire...
@mikejulian Sure, but code changes quickly, too?
I think the important point is that you have a repository for these docs, and that assistants can access them. If putting them in git doesn't make sense for your processes, that's ok. Just have them somewhere organized and accessible.
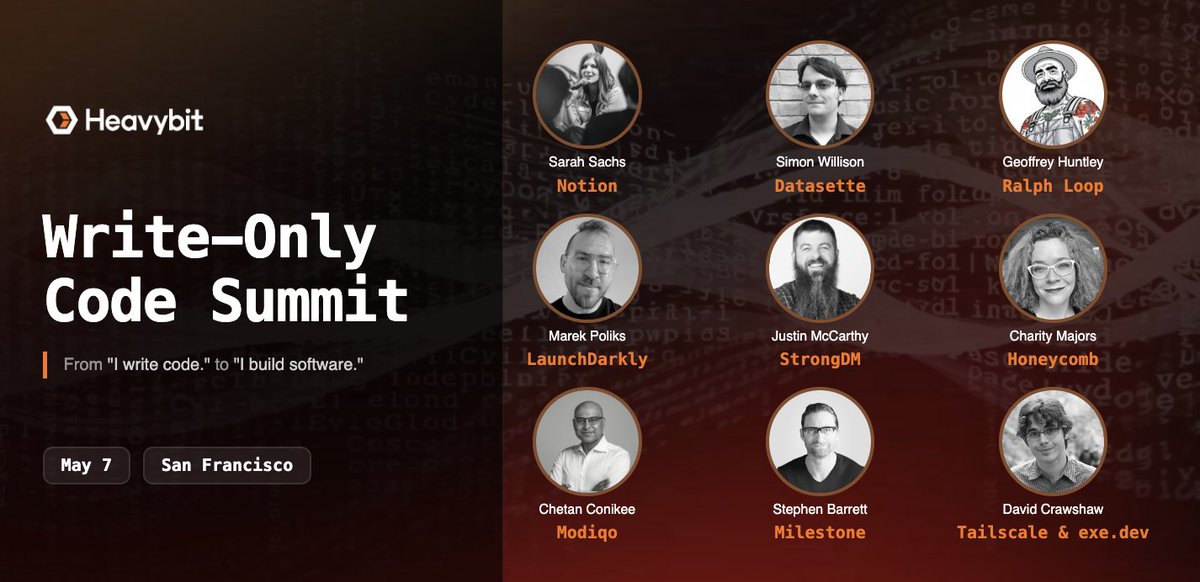
Announcing #DevGuild: Write-Only Code Summit. On May 7, we're bringing together 200 technical founders and infrastructure leaders for a day of talks, panels, and closed roundtables on how to build and lead in this new era. 🚨 Early bird pricing ends April 7: https://t.co/rMsffsWgKC
@chrismunns@amazon Maybe last-mile is more energy efficient because only one truck is dispatched to your house, but to get this item to that truck it now has to travel over a much less efficient mechanism (eg flight between distribution hubs)?
That said, it's probably way more likely a logic bug.
We're hiring a Head of Engineering at @DuckbillHQ.
We think the entire cloud cost management industry is solving the wrong problem. While everyone else is building tools for making bills smaller for startups, we're building a data platform for making them more predictable and less complex across an entire enterprise.
Given we're early days, this is a builder role. You'll be in the code every day and setting the pace for the team. You'll be leading the team on foundational decisions from day one.
The engineering problems are interesting. We're processing hundreds of millions of rows of billing data per customer per month. We're modeling pricing schemes and contract structures for every provider we support. The dimensionality reaches into the thousands of columns when you combine provider billing data with customer data and the datasets hit terabytes easily. The customer needs to not just query this data, but modify it too--faster than a traditional data pipeline allows.
We're ~12 people, based in SF, well-funded through revenue and our investors, and have the kind of customer list and brand awareness most seed-stage companies spend years trying to build.
Feel free to DM me. Job post and more details about our point of view are linked below.