From LR scaling laws to data curricula, we've been exploring better recipes for LLM pretraining.
Many of these ideas have made their way into Puro-2B and Kaiyuan-2B, our fully open, efficient, low-cost pretraining projects.
More to explore, and more to come!
Pretraining + midtraining can be viewed as a single training run with a "data schedule", where the data mixing ratio of midtraining data changes from 0 to 1 in the middle of training. Is this optimal? If not, what is the optimal data schedule?
We tried to answer this question and found that the answer is complicated and actually depends on your choice of learning rate schedule...
Check out our new paper: Data Schedules and Learning Rate Schedules Should Be Designed Together!
(1/9)Suppose you're training an LLM on web data with limited math data. Should you place all your math data at the end of training, or mix it with web data earlier? The answer flips with the learning rate (LR) schedule!
At fixed compute and mid-training (MT) token budgets, earlier mixing gives lower MT loss when LR decays throughout training. With constant LR, placeing all MT data for the end works better.
We then vary when LR decay begins. The best tested strategy: keep LR high after MT data enters, then decay near the end.
See our new paper: "Data Schedules and Learning Rate Schedules Should Be Designed Together" !
RoPE encodes positional information by rotating query and key vectors based on their positions, with each RoPE channel contributing a cosine function of the relative position.
But is this periodicity really beneficial?
Introducing our new paper — WavePrune: One Period Is Often Enough for RoPE!
Wrapping up my first month at @DiscoLoopAI (am on leave from @PrincetonCS and @PrincetonPLI ). Excited to work on using AI to accelerate scientific discovery and solve important problems. My first startup experience, and with an incredible set of colleagues!
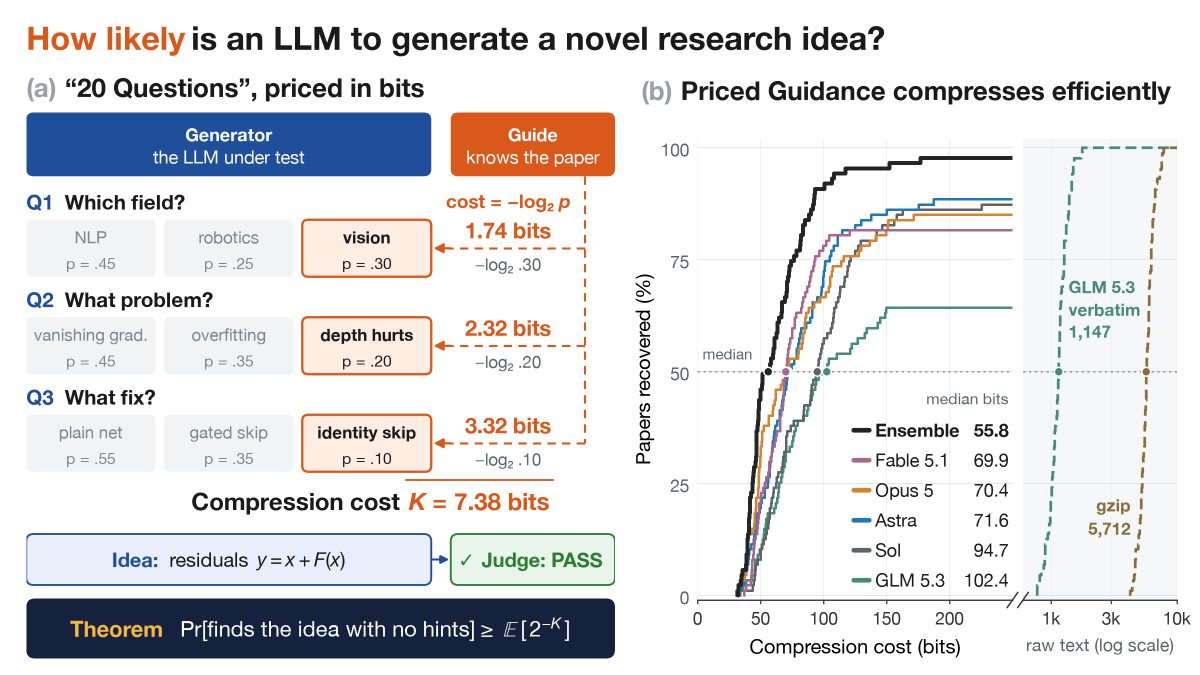
Can LLMs generate novel research ideas? We propose Priced Guidance to quantify this via compression!
We lower bound P(LLM forecasts a future paper’s idea X). Instead of sampling ideas until X is matched, the LLM plays “20 Questions” to recover X, charging each hint by surprisal.
https://t.co/EamfwKDQZL
Mini idea: reuse hidden instead of KV in YOCO seems to give a small boost for pretraining while keeping the majority of prefilling savings
unfortunately i contacted them on the night of wednesday, september 2nd making the following points
1. i had intel they had information about math work i was doing and a few days before they had spun up a group to try to compete.
2. i emphasized and reemphasized mine was a strictly personal mathematical collaboration
3. that this was a collaboration that had been going on for a year
4. that in my personal collaboration we were happy users of codex as well as obviously claude (and i later complimented astra explicitly after it came out for its help, and reassured i would obviously be sprinkling acknowledgments for it, previous models, and codex liberally in the writeups)
5. that it would look terrible if openai were competing against mathematician consumers, and my collaborator (Tristan) wanted to email about this explicitly
6. that i expected none but in the worst case intended to refuse marketing around the result we were working towards, being the fruit of a personal external academic collaboration, and wanted to express this because i figured worries about such marketing by their leadership was why a team was spun up to extraordinarily directly compete.
sebastien and i have in the past months had our fun pushing each other on twitter, but as i process it all i keep feeling bad about Tristan.
1. neither of us could sleep Sunday night, so we went on a walk around the city. i finally asked him why fluids, and he told me it was the navier-stokes problem. he told me parts of the story about his classic nonuniqueness result with Vicol i hadn’t heard yet, and also about how he too grew up writing shaders as a kid and then switched to math
2. tristan is a mathematician’s mathematician. he kept rock solid to his principles during the tense calls and negotiations, immediately turning down a career dream and million dollar prize for me, the sort of strange excited unclear-quasiuseful confused idiot in our collaboration. fifteen minutes later, his feet were up on his desk with three toes per foot peeking out of ripped socks
3. our periodic call after i’d texted him euler blowup was just laughing for an hour or two. just laughing. i’d seen fable deal correctly with monge ampere in the equality case of ehrhart’s conjecture, so in some call before that i’d really pushed him for the craziest shit he could think of that i might try. i texted him the pdf as an update on that “diego luis 3” line, in which following his incredible expression of intuition i hodgepodge slapped together a bunch of our recent work, in particular correcting a bunch of better and lesser known papers in the literature, as well as on diego and luis’ ipm paper, and hoped an analogous construction for boussinesq (thus axisym euler) might work out. i managed to wade through enough confusion to insist to the model it stop telling me stupid regularity stuff about kelvin waves, and a rayleigh-taylor ansatz stuck. like i said, just laughing. when i texted him the pdf, the worst thing either of us had seen so far, i didn’t even comment on the euler blowup claim, only explaining why skepticism should remain for boussinesq, because i found it so shocking. i mean what the hell did i know, i must’ve confused myself by misunderstanding one adjective like i was used to with algebraic geometry. im so lucky to have been able to live that
4. he managed all this this entire time with unclear sleep, timestamps continue to amaze me, due to just recently having a kid
it is obvious he deserves the same sort of praise he heaped upon luis, perhaps mutatis mutandis:)
Can Looped Transformers still help when FLOPs, parameters, and KV cache are all matched?
We introduce SMELT: Scaling Laws for Compute-Matched MoE Looped Transformers.
The answer is yes. And the advantage grows with scale. 🧵 1/8
Paper: https://t.co/CElIjvFqJS
https://t.co/aeBh54EeDK
Detailed technical report with tons of insights!
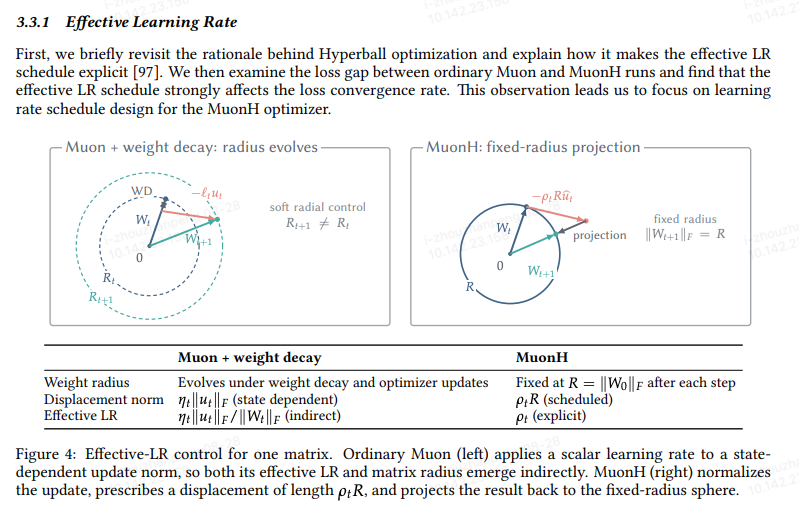
Notably, they uses MuonH as optimizers and discussed Effective LR with similar insights as in our blog https://t.co/et0K2KYE3k.
@vfleaking is making ELR great again!
Excited to introduce Puro-2B, along with its fully open recipe that lets you train a Qwen2-1.5B-level LLM on RTX 5090 GPUs for less than $5090!
As someone who has always been curious about why LLMs work so well, one of the biggest challenges today is that we not only lack a good theory, but are also losing the ability to run controlled training experiments at scale, systematically vary key factors, and gather the empirical evidence needed to understand how LLMs learn from data.
Training LLMs has simply become too expensive.
There are now a few great open or almost open training recipes for models with billions of parameters, but reproducing them can still cost hundreds of thousands of dollars. As this makes many basic questions about LLMs inaccessible to academic labs, we really hope to bring this cost down far enough that academic labs can train and study genuinely capable models from scratch.
Puro is a full-stack engineering effort to reduce training cost, which mixes engineering and research across data, optimization, numerical precision, hardware, and training strategy. It also builds on some of our own previous research:
📈 Curriculum Model Averaging (CMA): data curriculum designs have to work together with moderate learning rate decay and model averaging (https://t.co/dkufW4qMbz)
◉ Hyperball / MuonH: an optimizer wrapper that constrains weight and update norms, and directly controls the effective (angular) step sizes for stable and efficient training (https://t.co/MZEkev4Ts7)
There is still a long way to go, and we would be very happy to hear your feedback and ideas!
How much would it cost you to pretrain a 2B LLM from scratch? $1M? $100K?
🚀Announcing Puro-2B, with a fully open recipe.
You can train a model that matches Qwen2-1.5B on RTX 5090s for less than $5090!
$4.4K → beats Qwen2-1.5B
$6.9K → approaches Qwen2.5-1.5B
Check here👇
We submit MuonH with minus-sqrt LR scheduler (1-\sqrt{t}) to the modded-nanogpt Track 3 benchmark.
It improves the current MuonH SOTA by 75 steps—and, surprisingly, nearly doubles the peak learning rate under this schedule.
More results are on the way. Stay tuned.
Interesting finding on frontier models.
It turns out that frontier models can write proofs but stumble on faithfully copying a long block of text.
This has huge implications.
It sounds trivial, which is exactly why it is surprising. Exact reproduction of code, tables, and structured documents is something people quietly rely on every day when using frontier LLMs.
The authors measure this copying failure and show that treating text as a 2D layout, rather than a 1D token stream, recovers much of the lost fidelity.
Paper: https://t.co/1SUF9yOJJW
Learn to build effective AI agents in our academy: https://t.co/LRnpZN7L4c
Finally, our paper is on arXiv! 🎉
Huge thanks again to my amazing collaborators Yiran @zhangyir22, Yingfa @yingfachen, and Kaifeng @vfleaking! 🙌
We complete the global-minima analysis of 2D-RoPE and prove that an $\ell_\infty$-constrained global minimizer found by one-layer 2D-RoPE can learn copy with length generalization.
More broadly, we hope this sheds light on how positional encodings shape a model’s learning behavior beyond this specific setting. ✨
arXiv: https://t.co/Mc0wBang7d
P.S. Always happy to chat about theory! 🤩
To figure out the mechanism of an unfamiliar environment, an agent has to work out what the world is and how it changes. That's what our [schema] does.
On ARC-AGI-3 Public, [schema] thinks like a physicist: it grounds the state and discovers the mechanism in one editable program. This induced world program makes action efficient: once it discovers a mechanism, it plans inside the model for free. And we achieve an amazing 99% RHAE.
Starting from here, mechanism discovery in much richer environments is what's next. Stay tuned!
Alignment should not be done at the post-training stage alone, and pretraining-stage alignment should go beyond just trying to make data safe!
Check out our new paper:
Beyond Safe Data: Pretraining-Stage Alignment with Regular Safety Reflection
Existing pretraining-stage alignment methods use data filtering and rewriting to construct a safe pretraining corpus. But is safe data enough for building a safe model? Of course not!
We introduce a pretraining-stage alignment method beyond just making data safe: Safety Reflection Pretraining (SRP). By teaching models to self-monitor their generations and halt unsafe behaviors, SRP significantly reduces attack success rates on inference-stage and finetuning attacks!
Check out our new paper: Beyond Safe Data: Pretraining-Stage Alignment with Regular Safety Reflection https://t.co/RN90sBkl9j
🧵👇 (1/n)
Every data curation pipeline shares the same instinct: dedup, rebalance, flatten toward uniform. This work shows the opposite for compositional reasoning: uniform sampling creates a symmetric, nearly-flat loss landscape at init, and GD can't find a descent direction (they prove a CSQ lower bound!).
Zipf's law in natural language might not be a bug we need to fix. It might be part of why pretraining learns to reason at all.
In general, the best training distribution for teaching a model a task is not necessarily similar to the test distribution. Many other mechanisms can lead to this. Interested? Check out our prior work with Marko Medvedev, Zhiyuan Li, and Nati Srebro: https://t.co/NzHeT8kjWc
If you happen to care about a reasoning task that requires implicit compositions of multiple atomic skills, and you want to generate synthetic data to teach an LLM this task, should you make the skill distribution as uniform as possible to ensure coverage?
Our ICML 2026 (spotlight) paper shows the opposite: inducing an artificial power-law distribution over skills can make models learn much better, even when the test distribution is uniform!
Poster Session:
📝 The Power of Power Law: Asymmetry Enables Compositional Reasoning
📅 5:00 PM–6:45 PM, July 9, 2026
📍 Hall A, #1200
A question on synthetic data generation: If we want a language model to solve k-step arithmetic problems (such as a+b*c-d=?), with operands from 1 to 100, which training distribution should we use?
A. Uniform distribution: Sample these k operands uniformly from 1 to 100
B. Power law: randomly shuffle 1-100 and impose an artificial power law. Sample these k operands according to this power law.
⚡Our ICML 2026 (spotlight) paper shows: Option B is better! Surprisingly, the same idea extends far beyond this simple example to many reasoning tasks that require implicit composition of multiple atomic skills, including multi-hop QAs and synthetic GSM problems.
📄Paper: https://t.co/8LVlmCCBz9
📝Blog: https://t.co/t2yhIJ0s1P
We’re entering a data-scarce regime; but is less data always worse? Our #ICML work shows that small-set training (e.g., with repetition) can be actively leveraged as a useful optimization bias for structured reasoning tasks. Come chat with Jingwen and Ezra in Seoul to know more!