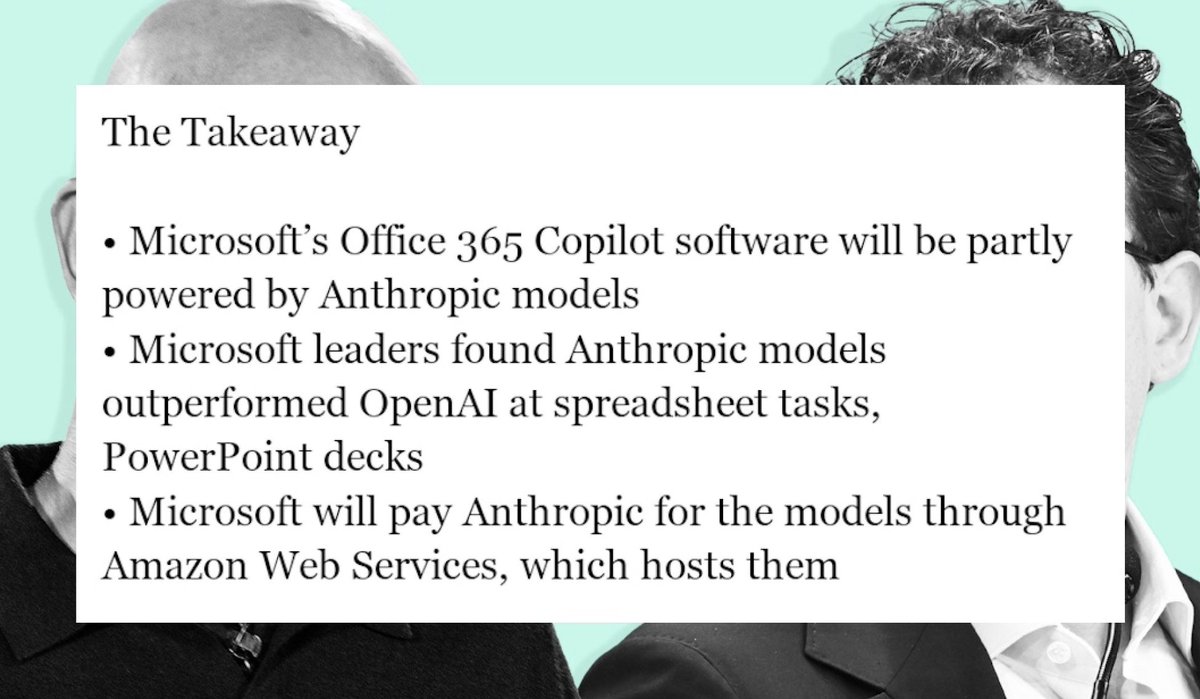
Microsoft to integrate Anthropic models into Office 365 Copilot, outperforming OpenAI in spreadsheet and PowerPoint tasks, with payments via Amazon Web Services.
ClockBench assesses AI's ability to read analog clocks: 36 custom clock faces, 180 total clocks with 4 questions each (720 total), tested on 11 models from 6 labs and 5 humans.
Introducing ClockBench, a visual reasoning AI benchmark focused on telling the time with analog clocks:
- Humans average 89.1% accuracy vs only 13.3% for top model out of 11 tested leading LLMs
- Similar level of difficulty to @fchollet ARC-AGI-2 and seemingly harder for the models than @hendrycks Humanity's Last Exam
- Inspired by original insight by @PMinervini , @aryopg and @rohit_saxena
Typeless is the smartest AI voice dictation app I've tried, enabling crystal-clear messages, emails, or texts four times faster than typing, with features like removing filler words and auto-editing.
Introducing @typelessdotcom writing assistance.
Today begins a world where your voice can do anything to any text.
It’s another step toward our vision:
Your voice as superpowers. Say it, and it happens.
https://t.co/h7yM13n6RM
Has LLM progress slowed?
Initial reactions to GPT-5 were mixed: to many, it did not seem as dramatic an advance as GPT-4.
Benchmarks may help clarify the picture: GPT-5 is both an incremental release following many other OpenAI advances, and a major leap from GPT-4.
🐺 Introducing the Werewolf Benchmark, an AI test for social reasoning under pressure.
Can models lead, bluff, and resist manipulation in live, adversarial play?
👉 We made 7 of the strongest LLMs, both open-source and closed-source, play 210 full games of Werewolf.
Below is our role-conditioned Elo leaderboard. GPT-5 sits alone at the top, we’re looking for contenders strong enough to threaten its lead. (📥 DMs are open !)
Find out more here: https://t.co/x1wHILMugR
Cerebras leads in output speed at 650 tokens per second with low latency of 0.2 seconds, while NVIDIA offers the best value at $0.1 per M tokens, according to the gpt-oss-120B provider analysis.
OpenAI's reasoning system shows remarkable progress, jumping from 49th to 98th percentile at the IOI in one year, surpassing last year's near-bronze performance.
1/n I’m thrilled to share that our @OpenAI reasoning system scored high enough to achieve gold 🥇🥇 in one of the world’s top programming competitions - the 2025 International Olympiad in Informatics (IOI) - placing first among AI participants! 👨💻👨💻
xAI's integrated router with selectable models is a smart approach, and setting the auto-router as the free tier default could encourage wider reasoning use.
Grok makes things easy with Auto mode, but we never take optionality away from you.
If you want to make our PhD-level Grok 4 suffer through basic problems like 1 + 1, you are more than welcome to do so😅
Also, glad we don't show 42 different models in the dropdown menu here
GLM-4.5 ranks 3rd overall with a 63.2 score across 12 benchmarks, excelling in agentic tasks and coding, with a parameter-efficient MoE architecture and hybrid thinking mode.
Presenting the GLM-4.5 technical report!👇
https://t.co/6sYwjRsHho
This work demonstrates how we developed models that excel at reasoning, coding, and agentic tasks through a unique, multi-stage training paradigm.
Key innovations include expert model iteration with self-distillation to unify capabilities, a hybrid reasoning mode for dynamic problem-solving, and a difficulty-based reinforcement learning curriculum.
Top AI salaries reach $250 million, far exceeding those of the Manhattan Project and Space Race, with a 24-year-old researcher earning 327 times Oppenheimer's atomic bomb development pay.