At @WaveFormsAI we are #hiring in SF for:
1) Software Engineer, LiveKit/FastAPI Engine
2) Software Engineer, Full-Stack (React/FastAPI)
3) Research Engineer, Multimodal LLMs
Join us to hear the AGI ! 🤖🎙️🪄
https://t.co/Flf5FHL7xS
Excited to announce the creation of WaveForms AI (https://t.co/KGWcqftNIy) – an Audio LLM company aiming to solve the Speech Turing Test and bring Emotional Intelligence to AI @WaveFormsAI
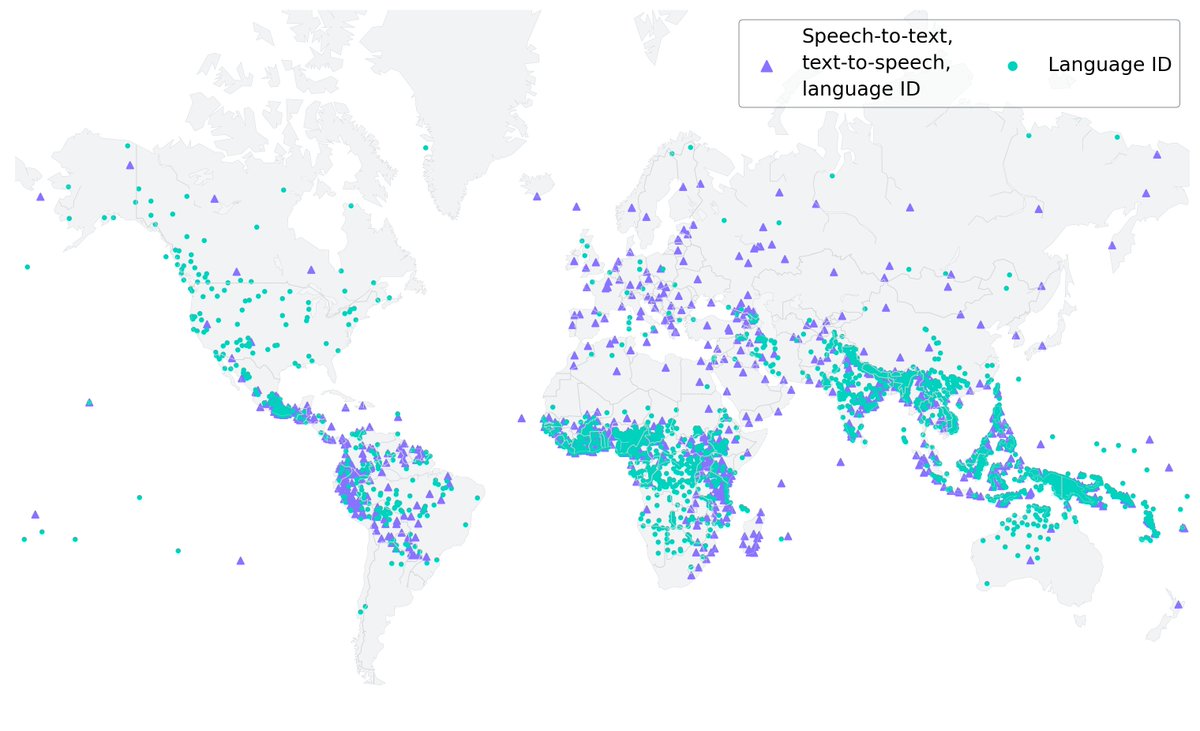
We are releasing MMS Zero-shot: a model to transcribe the speech of almost any language using only a small amount of unlabeled text in the new language.
Paper: https://t.co/aRoLtZSkpP
Demo: https://t.co/tFwhwTZpWO
Code/model: https://t.co/IxC8b7A9Ah
Just in time for the holidays, we are releasing some new software today from Apple machine learning research.
MLX is an efficient machine learning framework specifically designed for Apple silicon (i.e. your laptop!)
Code: https://t.co/Kbis7IrP80
Docs: https://t.co/CUQb80HGut
@reach_vb This benchmarking seems to be a bit unfair since some models use these evaluation datasets in their training, while others do not. It might be better to use an out-of-domain test dataset for all models.
MMS TTS models have just been released through the Transformers library 🤗. Stay tuned for our upcoming finetuning recipe!
Huge thanks to @sanchitgandhi99 and the amazing HuggingFace team for making MMS models accessible and user-friendly. 🌐
🤗 Transformers just got 1100+ new TTS checkpoints 🚀
You can now run any of @MetaAI's MMS TTS checkpoints using the Transformers library in 3 lines of code⚡️
MMS is a the largest democratizer of TTS globally to date 🌎
Try it in your language now: https://t.co/JcrylGZrKm
Happy to be releasing Code Llama! We've built it on Llama 2 and improved it for code use cases. In particular it supports infilling out of the box, and was trained with sequences up to 16k tokens.
Looking forward to what the community will build with it! 1/7
PaLM + AudioLM = AudioPaLM !
We start from PaLM pretrained on text and extend its vocab w/ audio tokens. This model can then be finetuned on a mix of any (speech, text) task e.g. ASR, TTS, MT and speech2speech translation in one's voice! 🧵1/4
https://t.co/l2z2tWie7C
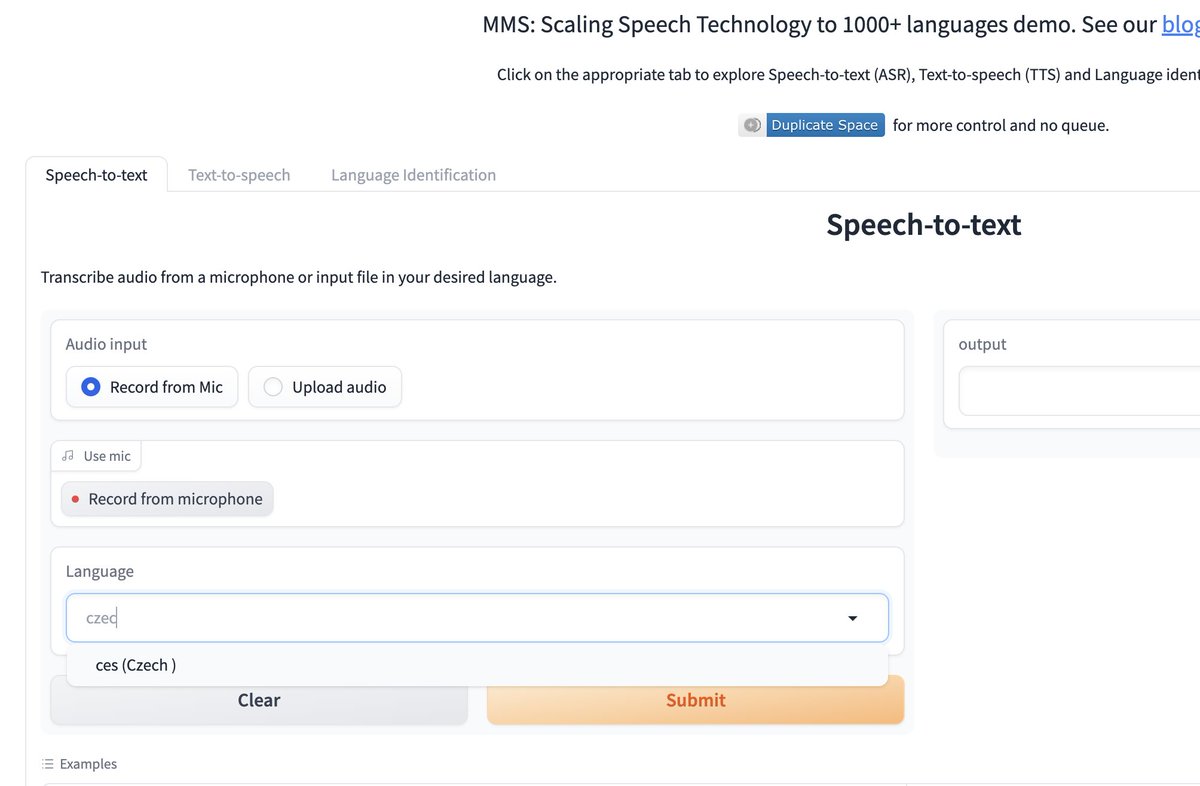
Massively Multilingual Speech (MMS) demo is now on @huggingface Spaces! Try out speech-to-text and text-to-speech in over 1,100 languages!
Demo 🤗
https://t.co/A2NwWhEteS
Docs 📝 https://t.co/OtQyHH85nS
5 / 5
We've integrated MMS into 🤗Transformers making the models very easy to use for both inference and fine-tuning.
Demo 👉 https://t.co/FGBhFraxtk
Docs 👉 https://t.co/E9Fg2Fygiu
Fine-Tuning 👉 https://t.co/vmeguZfuHM
Introducing Voicebox, a new breakthrough generative speech system based on Flow Matching, a new method proposed by Meta AI. It can synthesize speech across six languages, perform noise removal, edit content, transfer audio style & more.
More details on this work & examples ⬇️
We've just released MusicGen, and there is a @huggingface demo now, here is a thread about me playing with it just right now. https://t.co/kAE7mSMjrw
A 🧵👇
Excited to share the ToolBench, an evaluation suite for LLM tool manipulation capabilities.
- Paper: https://t.co/VJgJvuTxoy
- Code: https://t.co/w4HjHsxWTf
- Hugging Face leaderboard: https://t.co/KOi8Z00ReK
We do open source many tools for CTC forced alignment as part of the MMS project.
API: https://t.co/Y8dsrkxipF (implemented for both CPU & GPU)
Tutorial: https://t.co/8aEEYu6q0M
Working with long audio files: https://t.co/3EGzH7Lss9 (Compatible with any input language)
@bnjmn_marie In Table 5, all numbers are comparable except for Whisper where we added asterisk(*). For our own results, we do not apply any normalization to the data before computing error rates. We added Whisper for completness but clearly marked that the results are not strictly comparable