Fine-tuning 100B Model Really Needs Expensive GPU Servers? NO, Adding SSDs is All You Need to enable fine-tuning 100B model on a single GPU: https://t.co/7yo7wb8DIA
Our recent FCCM‘20 work "Shuhai: Benchmarking High Bandwidth Memory on FPGAs" enables accurate benchmarking of memory via FPGAs, rather than via CPUs/GPUs that are noisier systems due to their complex control logic, TLB and cache. @_onurmutlu_
Code: https://t.co/cFoYx8eGO1
@amyhu1919@5thAlphabet@mcarney@falcfans I will say no. At my university, just checking the temperature and the green code (e.g., have not gone to the place at high risk in the last 14 days).
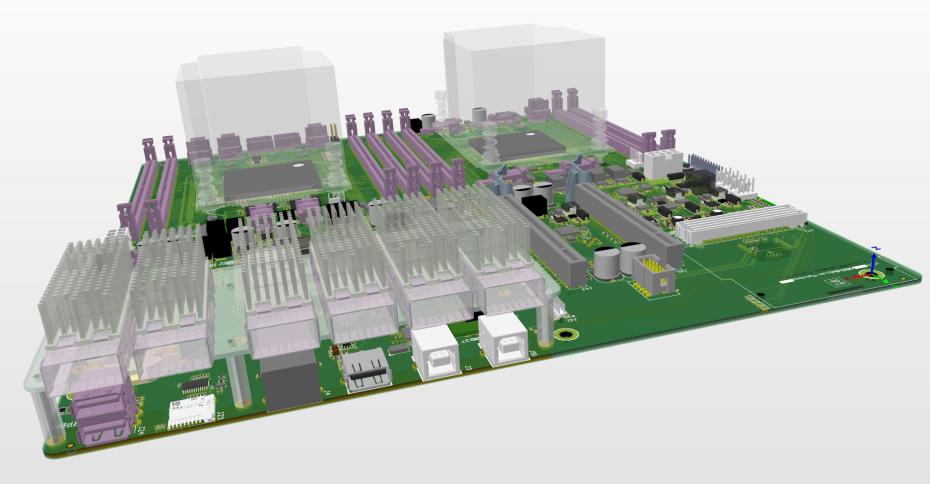
Prof. Timothy Roscoe and his @SystemsGroupETH team built their own #ComputerScience research computer for a multitude of applications. Learn more about #Enzian: https://t.co/xoWSldgRxM
Our recent @VLDB2019 work MLWeaving: arbitrary-precision linear model training. MLWeaving needs less amount of time and memory traffic with the use of lower precision, while using only one hardware design and one index. The full version of the paper: https://t.co/cK6GLuKLQu
#VLDB2019 When integrating ML into DB, can those data structures designed to accelerate relational queries also be used to accelerate ML? Zeke's MLWeaving (w/ Gustavo & @_onurmutlu_) show how a Bitweaving-like data structure support flexible precision (e.g., 5bit) GLM training
Today, we release an alpha version of ThunderGBM which supports GBDTs and Random Forests on GPUs. ThunderGBM can beat existing libraries such as XGBoost, CatBoost and LightGBM by over 10 times in many cases. Please use, comment and feedback. More details: https://t.co/ko80k1u0o0