Looped LLMs are heating up🔥. Open weights are becoming available, but the recipes to train these models remain hard to find.
Introducing ARLoop, a family of strong, fully-open pretrained looped transformers with Attention Residuals! Our strongest model, ARLoop-1.2B, outperforms both Huginn-3.5B, a prior fully open looped LLM, and Qwen3.5-2B Base on evaluated benchmarks across commonsense reasoning, math, and coding.
We release the full recipe: from data preparation and model training to intermediate checkpoints and evaluation code. ⤵️
I had Codex build a CPython bytecode compiler in Rust (`serc`).
It emits byte-for-byte identical output on the top 10,000 PyPI packages, 2-4x faster than the CPython implementation.
This was entirely an experiment, though we may ship it (opt-in) in uv.
We identify a blind spot in (M)OPD for post-RL consolidation:
Students may not inherit their teachers’ generalization capabilities, though they achieve near-perfect in-distribution distillation performance. 🧵
This is actually a common misconception.
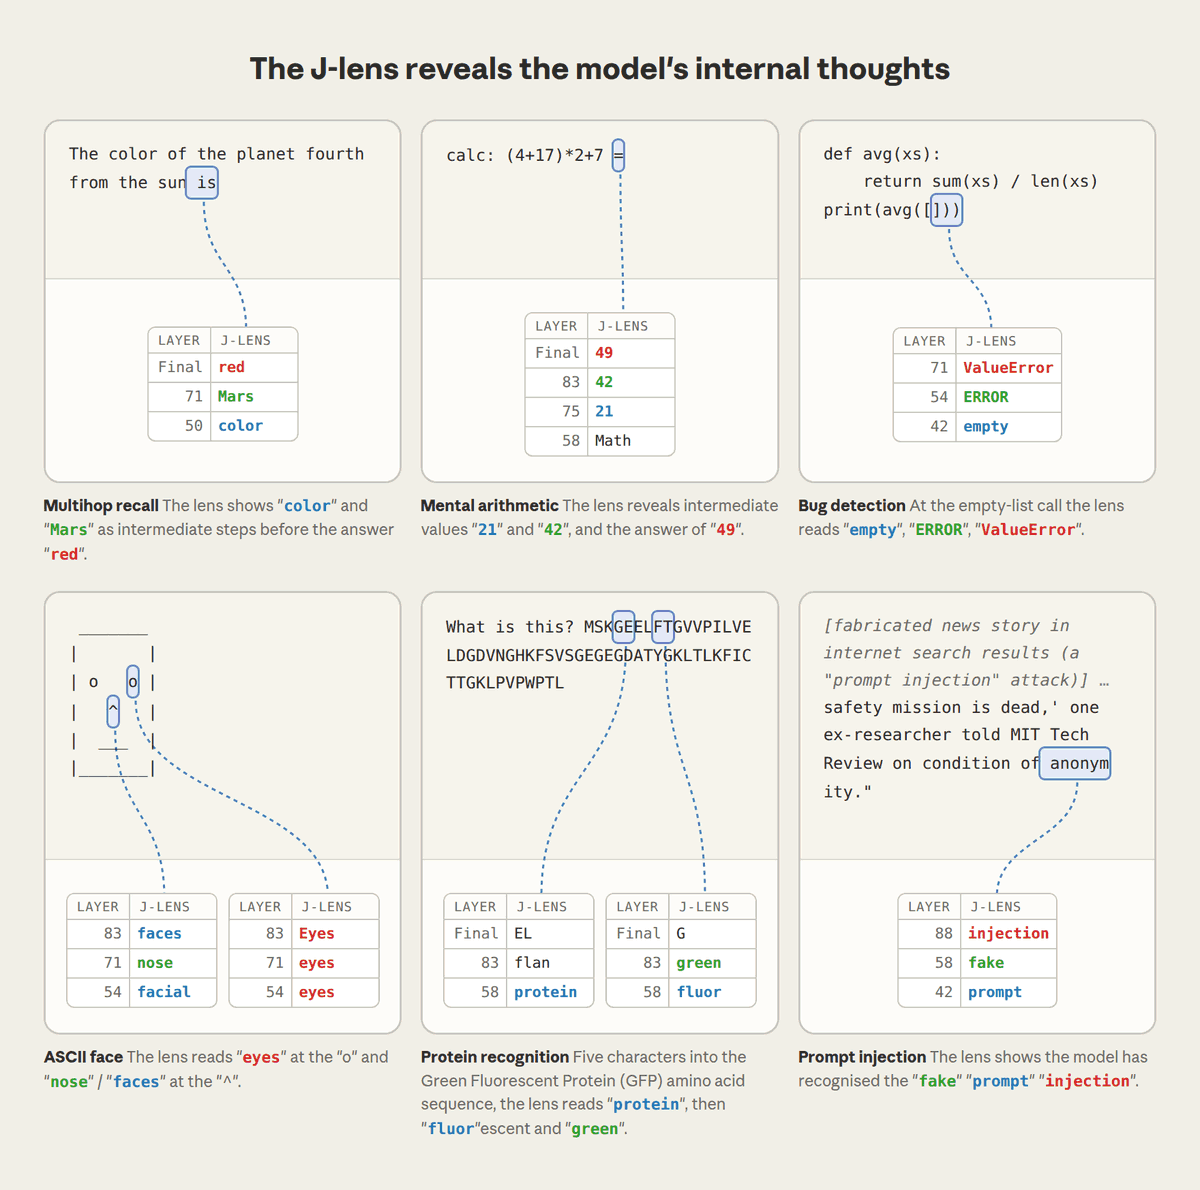
Hidden states in LLMs are used to predict all future tokens not just the next one!
And in fact we see representations that correspond to plans, or the broader situation
https://t.co/1iGyKbdTJZ
https://t.co/oVPF0BSSdI
18 of the 20 best open models today are Mixture-of-Experts. Dense is basically over.
And yet the know-how to train a good MoE still lives mostly in the heads of a handful of teams.
So we spent 800k GPU hours running the experiments ourselves and wrote everything down. Super happy to finally release "The Ultimate MoE Training Handbook", free and open, organized around the questions training teams hit:
- how many experts, how big, shared or not?
- why is half my step spent in all-to-all, and how do I hide it?
- why is my run 25x slower with no error in the logs?
- softmax, sigmoid or sqrt(softplus) router, and why keep it in fp32?
- aux loss or DeepSeek's loss-free bias?
- upcycle a dense checkpoint or train from scratch?
- can I serve with fewer experts per token than I trained with?
⚠️ Warning: it's long (~70k words, budget a few days, sorry) but with 55 interactive figures, code you can run and numbers from our own runs.
Read it here: https://t.co/6XihlUrj92
Anthropic is releasing an open source library, FlashProve, for provable inference. It was measured on Llama 4 Maverick, a 400B-parameter mixture of experts model.
Code:
https://t.co/1ILw5Zf8Lh
Blog post:
https://t.co/YROBN2PThF
This might be the greatest issue report in history
Some folks wrote a paper about my /retro skill assessing its effectiveness
Incredible
https://t.co/IYo4rhz1Vp
maybe a hot take but i now consider adversarial reviews mostly a waste of tokens. far better to use those tokens on empirical combined with formal verification. i have updated pstack to use the interrogate skill less, and eventually i think i may remove it altogether
i have found very little value with code review in the abstract, agents tend to just get lost in the nitpicks and yagnis