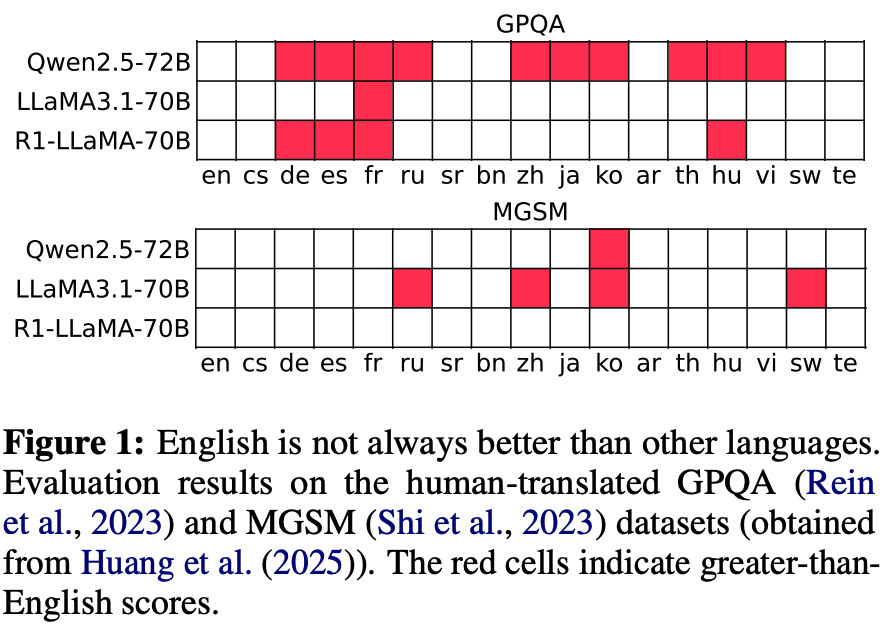
📢 Happy to bring our new paper! 🤩
> Non-En can exceed En in reasoning tasks
> Ensembling 4+ langs in inference can bring about 10% more theoretical gain than En
> Gain robust to lang choice and translation quality
Paper: https://t.co/u2aTV9UBfc
Repo: https://t.co/36Fbikvn1S
🎉 Excited to share “Generalizing from Short to Long: Effective Data Synthesis for Long-Context Instruction Tuning” 📄 (https://t.co/XalrVjmxg7)
We propose "context synthesis": instead of generating instructions from long texts, we synthesize contexts for instructions—drawing inspiration from "back-translation" in MT.
This ensures high-quality instruction-output pairs while enabling control over context length, difficulty, and composition, boosting long-context learning. Results show it outperforms prior methods and approaches human-annotated data! 🚀
Here’s the thread 🧵 (1/n)
🤩Excited to announce our new work BenchMAX!🥳
BenchMAX: A Comprehensive Multilingual Evaluation Suite for Large Language Models
Paper: https://t.co/g3VQ5W6tzn
Repo: https://t.co/olxFagOlGa
Datasets: https://t.co/PZUm1tu3SM
We find while scaling model size enhances multilingual performance consistently, the gap between English and other languages persists, highlighting the need for further efforts to achieve balanced multilingual capabilities.
(3/3)
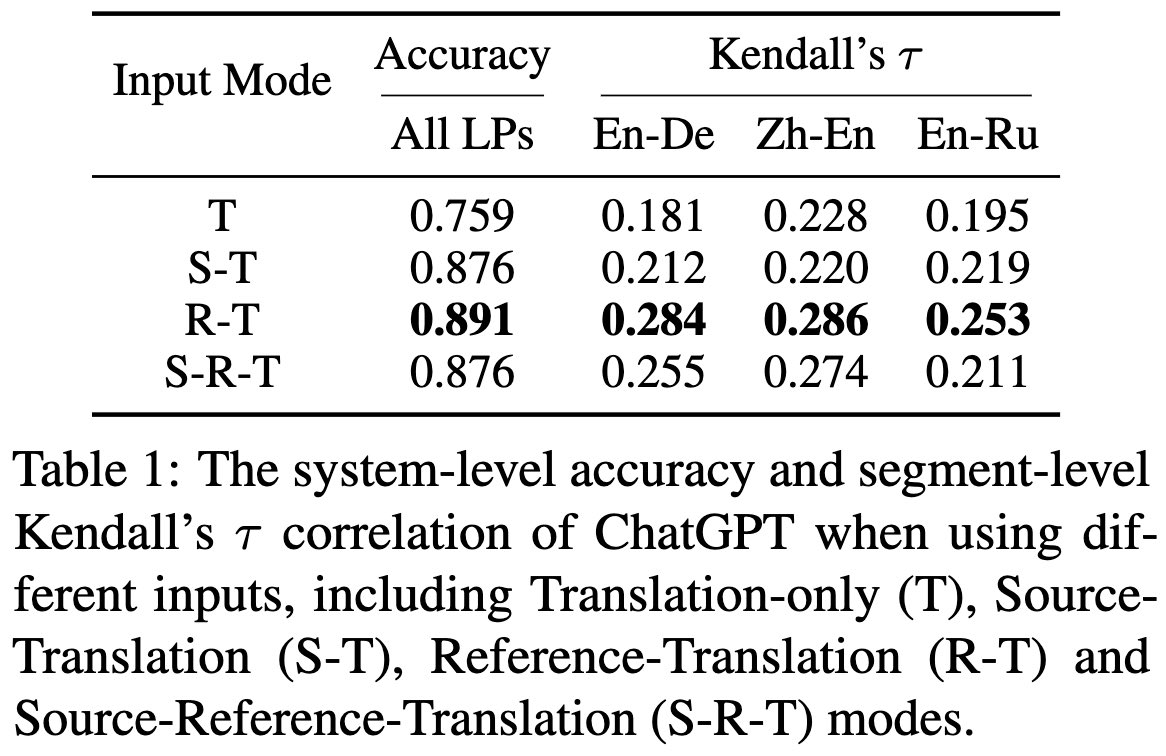
I’m very excited to share our new work on machine translation evaluation with large language models. We find that the reference can significantly enhance the performance, while the source can have negative effects.
Paper: https://t.co/5eujtz12xQ
Code: https://t.co/evn0LZToB1