On behalf of Gemini 4’s modeling team to improve VibeCoding capabilities (spanning WebDev, 3D, games, full-stack, Android dev, and more), we just landed 91.9% on VibeCodeBench!
As the AI race heated up, our release cadence accelerated dramatically. The pressure was immense - we worked day and night, non-stop, to land critical recipe improvements and push our model performance forward!
Today, with Gemini 4, we came back strong!
Huge thank you to my teammates who held the line through countless days and nights without ever complaining, and to our horizontal partner teams and leadership who believed in us and gave us unwavering support. Onward and upward!! 🚀
🚨 Tokens are the surface.
Attention is the mechanism.
What if RL learned the latter?
💡 Introducing Reinforced Attention Learning
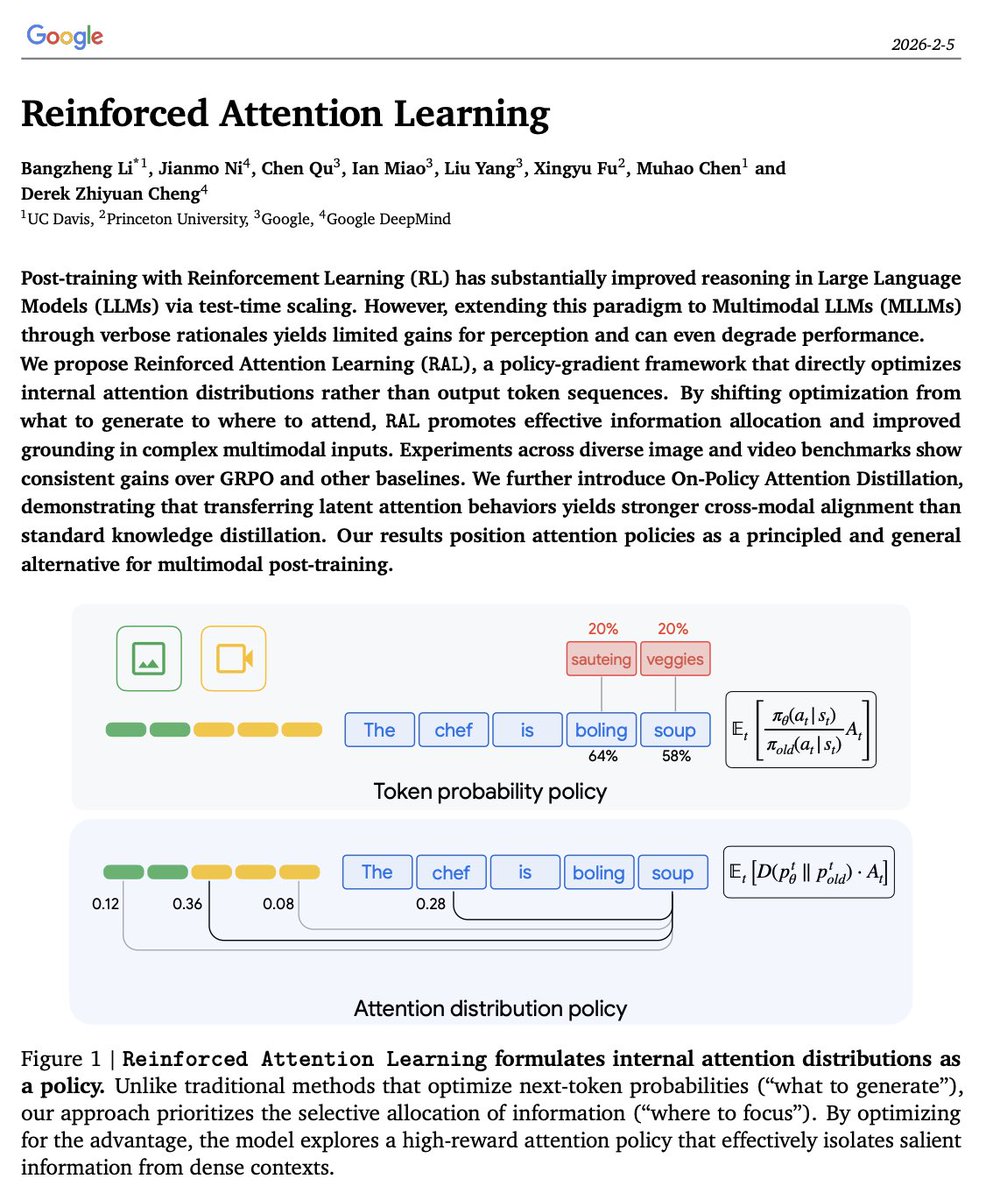
🧠 Key idea: Current RL for LLMs shapes "what is generated". We instead optimize "where the model focuses", to influence how it actually reasons.
📰 Paper: https://t.co/UnZ7txssG6
(with @Google and @GoogleDeepMind)
Standard PPO/GRPO perform importance sampling over token distributions, using advantages to up- or down-weight token probabilities.
⏳ The flip: Instead of "what token to generate", we optimize "where to attend"
At each generation step, we measure the divergence between attention distributions of the current and old policy—across all previous tokens.
- High-reward samples → keep attention close
- Low-reward samples → push attention away
The policy learns where to allocate computation, not just which surface-level token to generate.
⚙️ Plug-and-play
Our attention-level objective pairs with any policy gradient method, including PPO and GRPO.
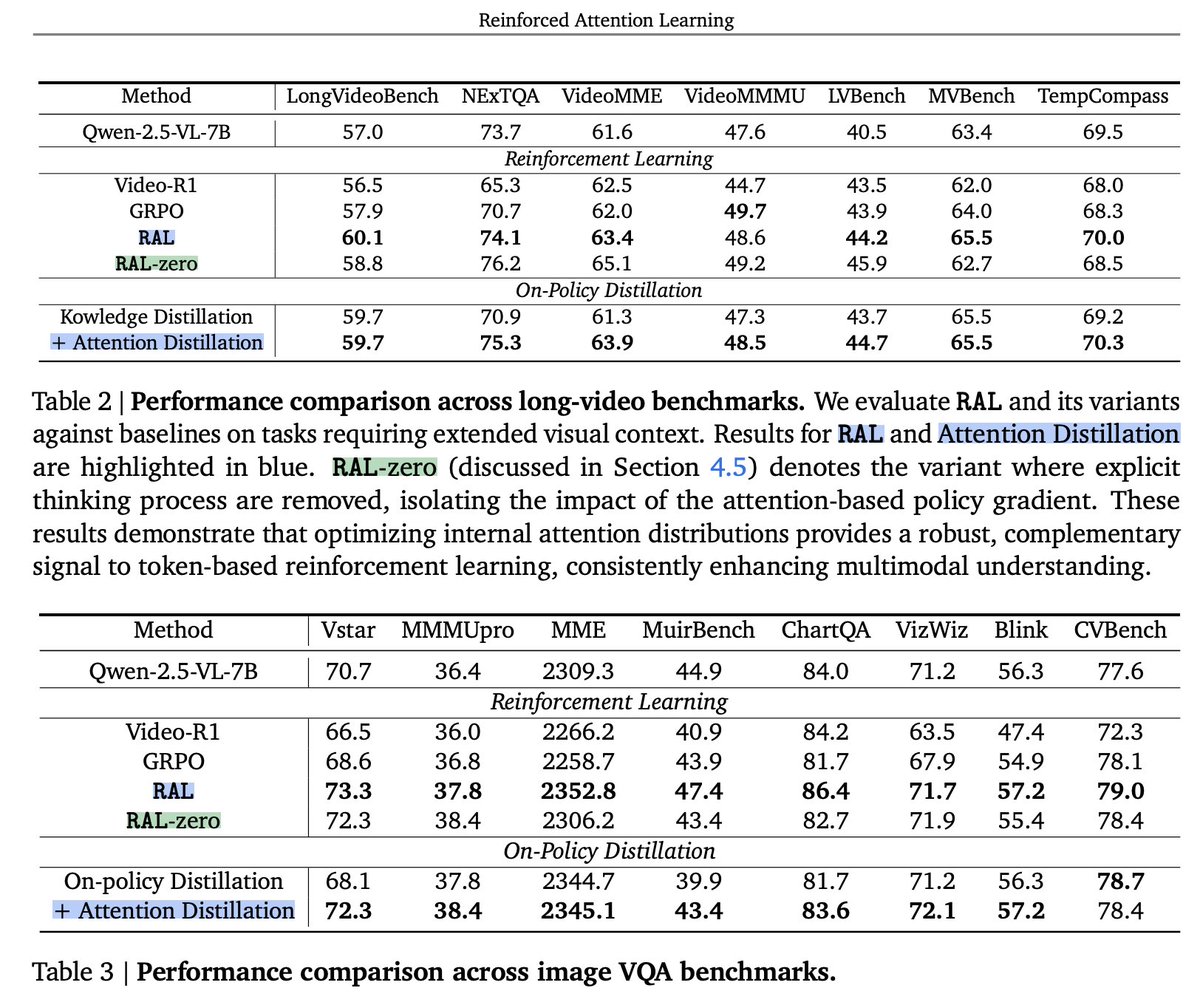
📊 Results
RAL > Vanilla GRPO.
We’re seeing consistent accuracy gains across a wide range of image and video QA benchmarks when experimenting on multimodal LLMs.
✨ One more thing
Attention can be learned from a teacher model via on-policy attention distillation—going beyond knowledge transfer to inherit latent attention behaviors. This On-policy Attention Distillation takes standard On-Policy Distillation to the next level.
Thanks to all my colleagues: @jianmo_ni@Chen_Qu1@ianmiao@liuyang_irnlp@XingyuFu2@infolaber🙏
🚀 Thrilled to share our paper “Teaching Language Models to Gather Information Proactively” is accepted to #EMNLP2025-Findings 🎉!
We move beyond clarification—teaching LLMs to ask new, insight-seeking questions that help them build better answers.
🔗 https://t.co/GyvRGIbmAe
This work is done during my internship @Microsoft Office of Applied Research 🙌
🤔 If MLLMs encode vision & text in a joint space, why not reason over both?
We introduce Latent Visual Reasoning (LVR) — a new paradigm for multimodal LLMs.
- Keeps everything autoregressive
- Reconstructs query-relevant visual semantics in hidden states (like human visual thinking)
- Interleaved LVR with text generation
- No external tools needed (unlike “Thinking with Images”)
- Outperforms CoT-based & image-tool MLLMs on perception-heavy tasks
We further adapt GRPO to latent reasoning: only text tokens are supervised, while latent states guide reasoning internally.
🌐 Website: https://t.co/guJ6GJiein 📄 Paper: https://t.co/SwtPIyRgoe 💻 Code: https://t.co/fvdj8xGbwl 🤖 Model: https://t.co/QbwtUVpFwU
Excited to share that two of my first-author papers were accepted to #EMNLP2025! ✨📚
1️⃣ Code Execution as Grounded Supervision for LLM Reasoning (Main)
2️⃣ Familiarity-Aware Evidence Compression for Retrieval-Augmented Generation (Findings)
Huge thanks to my collaborators🙌
@ReviewAcl@emnlpmeeting Urgent help needed.
acFZ: initial score 3
🧊 Complete silence during discussion.
⏰ 4am PST, 9 min before deadline: quietly drops to 2.
with “Thanks for the rebuttal. I have updated the score.”
⚠️ No explanation. No notice. No chance to respond.
(0/n)
🚨 New paper accepted to #ACL2025!
We propose SudoLM, a framework that lets LLMs learn access control over parametric knowledge.
Rather than blocking everyone from sensitive knowledge, SudoLM grants access to authorized users only.
Paper: https://t.co/gzzs9L6S1z
🧵[1/6]👇
😴 Extending modality based on an LLM has been a common practice when we are talking about multimodal LLMs.
❓ Can it generalize to omni-modality?
We study the effects of extending modality and ask three questions:
https://t.co/H8uiPQIp2U
#LLM#MLLM#OmniModality
🧵1/ Excited to share our #NAACL2025 work! 🎉
"Assessing LLMs for Zero-Shot Abstractive Summarization Through the Lens of Relevance Paraphrasing"
We study how robust LLM summarization is to our relevance paraphrasing method? 🧠📝
More details below:👇
https://t.co/YYqU6COQAg
How many r's in the word strawberry?
Human:3✅
GPT-4o:2❌
Such mistake rooted in subword tokenization or lack of character-level training?
Find out in my NAACL talk on May 2: LLM The Genius Paradox: A Linguistic and Math Expert's Struggle with Simple Word-based Counting Problems
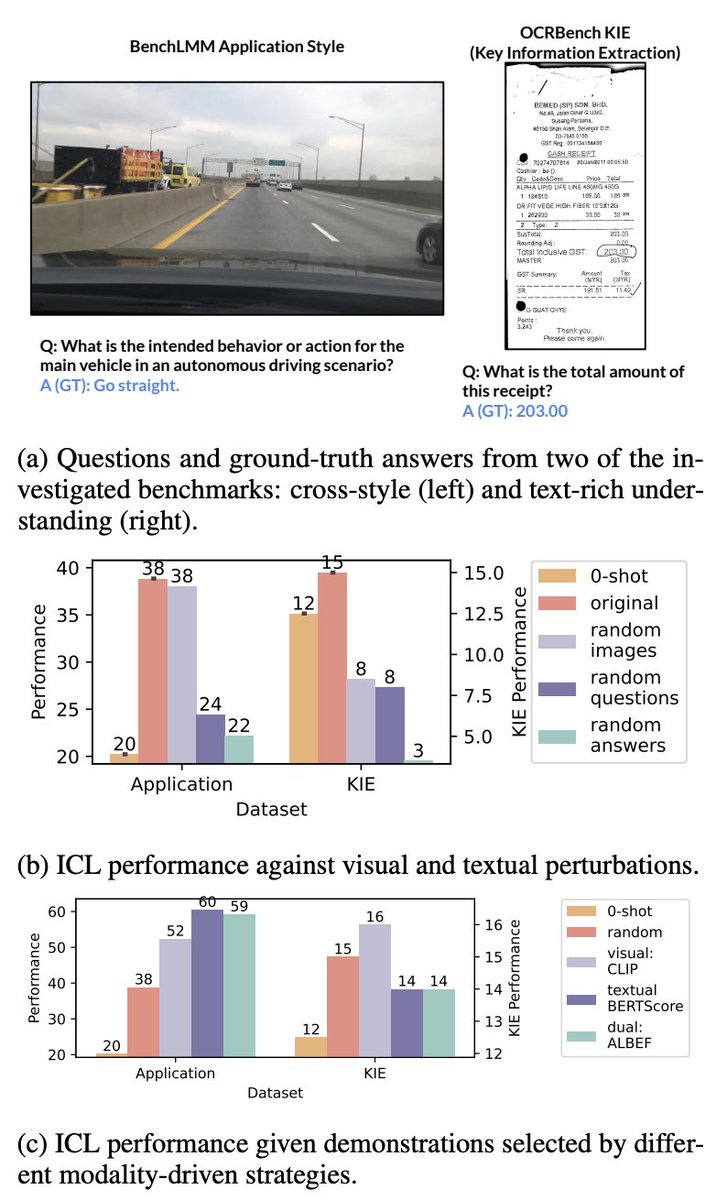
Our work shows that modality matters differently across tasks! Guided by task-specific modality impact, we recommend modality-driven demonstration strategies! We also find pretrained MLLMs acquire inductive biases from ICL, even when those biases contradict pretraining semantics.
Should multimodal in-context learning demonstrations mirror the visual or textual patterns of test instances?
I'll present paper “From Introspection to Best Practices: Principled Analysis of Demonstrations in Multimodal In-Context Learning” on April 30th at NAACL.
See you there!
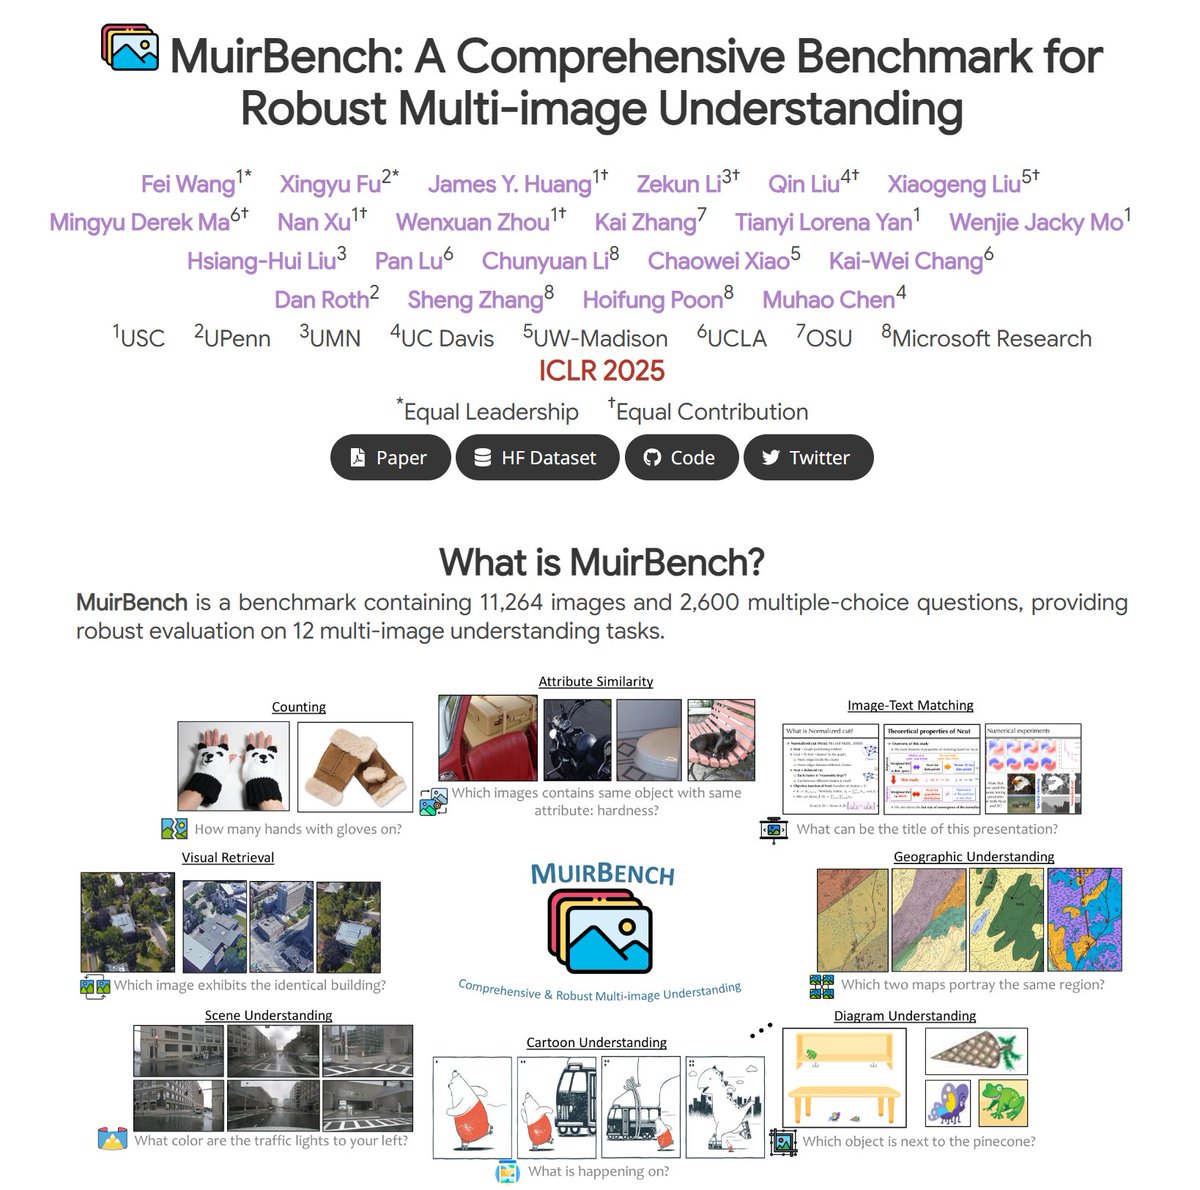
🎉 Excited to share that our paper, "MuirBench: A Comprehensive Benchmark for Robust Multi-image Understanding", will be presented at #ICLR2025!
📅 Date: April 24
🕒 Time: 3:00 PM
📍 Location: Hall 3 + Hall 2B #11
MuirBench challenges multimodal LLMs with diverse multi-image tasks, highlighting the need for models that can reason beyond single images.
🔗 Learn more: https://t.co/AGL17b4HEC
🖼️ Poster: https://t.co/KXK7bzymMp
#MuirBench #MultimodalAI #ICLR2025
🚨 Call for Papers! @aclmeeting 🚨
LLM Security Workshop @ ACL 2025 (the first workshop of ACL SIGSEC)
🔐 Topics: Adversarial attacks, defenses, vulnerabilities, ethical & legal aspects, safe deployment of LLMs and more
📅 Submission Deadline: April 15, 2025
📍 August 1, 2025 in Vienna, Austria
🔗 https://t.co/DQuDPKnYCy
👥 Organizers: @LeonDerczynski, @J_Novikova_NLP and @muhao_chen
#LLMSEC #ACL2025 #AISafety #LLMsafety #NLP
🌟 Check out our latest comprehensive survey on: 🌟
⚠️Emergent backdoor threats to LLMs
👻Safety challenges to LLMs
💡Future research directions in this area
Invited paper at 60th Annual Allerton Conference: https://t.co/oaCRSHuM4P
Mitigating racial bias from LLMs is a lot easier than removing it from humans!
Can’t believe this happened at the best AI conference @NeurIPSConf
We have ethical reviews for authors, but missed it for invited speakers? 😡