This holiday season, I got a chance to reinvest in something I love: contributing to open source! - Adding Apple Metal Performance Shaders (MPS) support to CTGAN, a powerful tool for generating synthetic data.
Why Synthetic Data and CTGAN Matter
In an age of increasing data security and privacy concerns, synthetic data is a game-changer (more on this topic later). CTGAN (Conditional Tabular Generative Adversarial Network) is a leading method for creating realistic synthetic datasets from real-world tabular data. This has applications in:
- Privacy-preserving machine learning: Test models on synthetic data that mirrors the statistical properties of real data without exposing sensitive information.
- Data augmentation: Generate synthetic data to supplement limited datasets, improving the performance of machine learning models.
- Data sharing: Share data with collaborators or the public without compromising privacy.
However, training CTGAN models can be computationally intensive, especially with large datasets. This is where Apple's MPS comes in.
Harnessing the Power of Apple's GPUs with MPS
Apple's Metal Performance Shader (MPS) framework provides a way to tap into the immense power of Apple GPUs. By offloading compute-intensive tasks like machine learning model training to the GPU, MPS can significantly accelerate performance. This is crucial for tools like CTGAN, where training time can be a bottleneck.
Key benefits of MPS include:
- Optimized for Apple hardware: MPS is designed to work seamlessly with Apple silicon, maximizing performance and efficiency.
- Ease of use: MPS integrates with popular machine learning frameworks, making it relatively straightforward to implement.
- Improved performance: By leveraging the GPU, MPS can dramatically reduce training times for complex models.
Speeding Up CTGAN with MPS: My Contribution
My contribution focused on enabling CTGAN to utilize MPS for training on macOS devices with Apple silicon. This involved modifying the CTGAN codebase to leverage MPS functions for key mathematical operations.
The results were impressive: In my initial tests, I observed 2x to 5x speedups in CTGAN training times compared to CPU-only training.
I'm looking forward to seeing even greater performance gains and wider adoption of synthetic data generation techniques.
Further Reading:
- Apple's MPS Documentation:https://t.co/HHUVf48Oxx
- CTGAN: https://t.co/japVgjkIP0
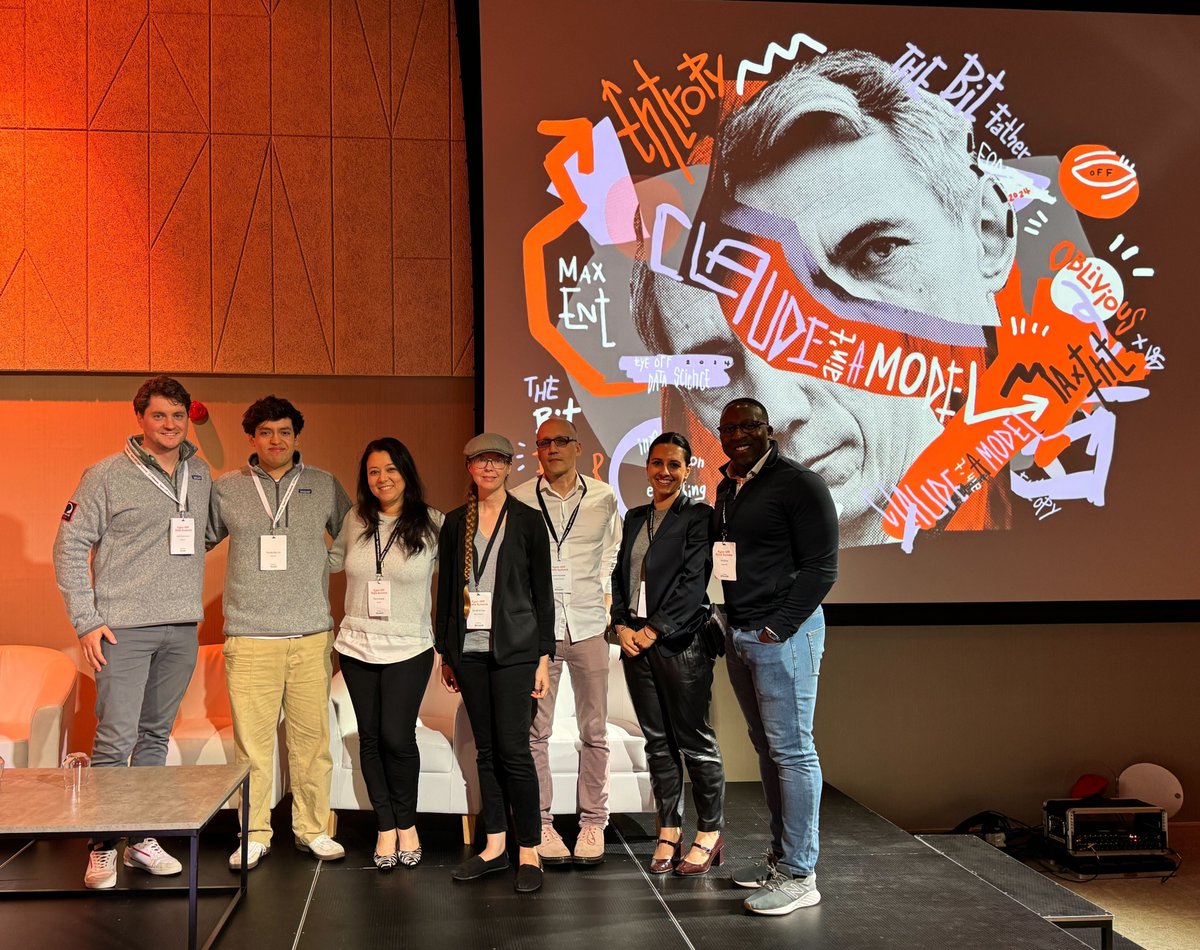
What an amazing eyes off data summit this year @oblivious_AI !
It’s always great seeing the @opendp_org crew as well, looking forward to next year!
Recap: https://t.co/bQhi40xM4W
Big OpenDP community representation at @oblivious_AI#EODSummit2024 speaking on panels about differential privacy, use cases, and building community in the PETs space! ❤️ Thanks Oblivious for putting together such a compelling event - can't wait for next year!
Join the conversation at OpenDP's Community Meeting Industry Panel: Deploying DP in Practice with @yawetse (@CapitalOne), Seyi Feyisetan (@amazon), @jk_fitzsimons (@oblivious_AI), James Honaker (@mozilla Anonym), and Christina Ilvento (@Apple)!
More Info: https://t.co/raW53JPs8Z
As a follow-up to "Hashing, Synthetic Data, Enterprise Data Leakage, and the Reality of Privacy Risks," it's important to address the limitations of synthetic data beyond just privacy concerns.
Synthetic data is not a replacement for high-quality original data, especially because of the risk of model collapse. This issue was highlighted in a conversation with Jack Fitzsimons from Oblivious, who shared the Nature article "AI Models Collapse When Trained on Recursively Generated Data." Transformers, known for their ability to capture long-range dependencies through self-attention mechanisms, are also pretty vulnerable.
The paper points out that “When models are trained on data that has been generated recursively, they can become increasingly biased towards the synthetic data, leading to a degradation in performance when exposed to real-world data.”
https://t.co/rfYAw3G0cg
The timely “No, Hashing Still Doesn’t Make Your Data Anonymous” post from the FTC is a great reminder that, especially with the rise of large language models (LLMs) and generative AI, how those models are trained and fine-tuned creates opportunities for massive data leakage.
Synthetic data is often considered the convenient solution to the data privacy challenges associated with LLM training and fine-tuning. However, synthetic data is not equivalent to anonymous or de-identified data. https://t.co/FDa3lciURP
Making Better Decisions: Good Arguments-Driven vs. Data-Driven Decisions
Performance management season always brings a push for data-driven approaches, and it’s usually not lost on people managers the truly subjective nature of the process.
As previously written, I think embracing this subjectivity can be more beneficial than attempting to mask a subjective process with vanity metrics.
There still is an opportunity to improve flawed data-driven approaches by being data-informed when data supports good arguments rather than replaces them.
The Pitfall of Vanity Metrics
Vanity metrics are appealing because they provide quantifiable data that seems to offer clear insights. However, they often obscure the subjective nature of performance management.
This reminds me of the ongoing discussion on the distinction between math and science.
Math relies on deductive reasoning, starting with basic principles and logically deducing consequences. If you accept the initial premises, the conclusions are certain. In contrast, science uses inductive reasoning, drawing general conclusions from observations. For example, if every swan observed is white, one might conclude all swans are white, but a single black swan disproves this theory (1).
The Advantages of Being Data-Informed
Being data-informed means using data as a valuable tool to support well-reasoned arguments, not as the sole determinant of decisions, e.g.:
Comprehensive Understanding: Data provides insights, but a comprehensive understanding of the factors driving performance is essential. Are all factors driving your metric well understood? If not, data may be misleading (2). By being data-informed, you use data to enhance your understanding rather than replace it.
Supporting Good Arguments: Good arguments are often based on a mix of data, context, and expertise. By supporting arguments with data, you ensure that decisions are well-rounded and consider multiple perspectives. This holistic approach is more robust than relying solely on data, which might overlook important nuances (2).
Encouraging Experimentation: Can you run an experiment to test your assumptions? Controlled experiments are invaluable for establishing causality. When data is used to inform hypotheses and guide experiments, it becomes a powerful tool for validation and learning (2).
Enhancing Communication: Data can help communicate complex ideas clearly and persuasively. Good data storytelling combines narrative with explanatory visuals, making insights more accessible and actionable (3).
Maintaining Motivation: Metrics that align with an individual’s or team’s convictions can enhance motivation. By focusing on meaningful metrics that truly reflect performance and contribution, organizations can boost morale and intrinsic motivation (2).
Challenges with Overemphasis on Data
While data is invaluable, an overemphasis on data-driven decisions can lead to:
Misinterpretation: Without proper context, data can be misinterpreted. It’s crucial to ensure that data is understood correctly and used appropriately (2).
Streetlight Effect: Organizations may focus on easily measurable improvements, neglecting more significant but harder-to-measure changes. This can lead to superficial enhancements rather than meaningful progress (2).
Suspension of Disbelief: Introducing metrics in areas where they don’t belong can lead to a culture of ignoring the limitations and meaninglessness of certain data points (2).
Weak Leadership: Relying too heavily on data can be a sign of ineffective leadership. Strong leaders should be able to use their judgment and observations to make decisions, using data to support rather than dictate those decisions (2).
The Value of Good Arguments
Good arguments, even without extensive data, can often lead to better decisions. Here’s why:
Correlation vs. Causation: Basic statistical principles remind us that correlation does not imply causation. It’s possible to make great decisions with good arguments and minimal data, but bad arguments can easily lead to poor decisions, even with good data (3,2).
Cultural Impact: An overemphasis on data can harm organizational culture. Metrics can lead to superficial improvements at the expense of more nuanced, meaningful changes (2).
Holistic Decision Making: Good arguments consider a wider range of factors, including context, expertise, and judgment, which are often overlooked in data-driven approaches (2).
Embracing a Balanced Approach
Data has its place and can be a useful tool for supporting arguments. However, it should not be the sole basis for decision-making. Strong arguments, grounded in observation and theory, often provide a more reliable foundation for decisions. Resist the temptation to rely solely on data, and maintain a healthy skepticism towards metrics that promise easy answers.
Being data-informed rather than data-driven means using data to enhance and support well-reasoned arguments. This balanced approach ensures that decisions are both informed by data and enriched by context and expertise.
Performance management benefits from a balanced approach that leverages data to support strong arguments. By being data-informed, organizations can make better decisions that consider both quantitative and qualitative factors.
Embrace the subjectivity of the process and use data as a tool to enhance, not replace good arguments. This approach will lead to more meaningful, well-rounded decisions that align with organizational goals and values.
For further reading, check out my other writings:
Embracing Followership and Technical Fluency in Modern Leadership
Rethinking Performance Management: Embracing Subjectivity Over Objectivity
Improving Engineering Culture by Building Products, Not Projects
University of Houston, THE ENGINES OF OUR INGENUITY: Math Versus Science ↩︎
Richard Marmorstein: Be good-argument-driven, not data-driven ↩︎
Forbes: 8 Pitfalls In The Data-Driven Decision-Making (DDDM) Process ↩︎
The recent LIMA (Less Is More for Alignment https://t.co/KHGkAPsymN) study, presents a method for aligning large language models (LLMs) with minimal fine-tuning data, and highlights the intersection of technological advancement and data privacy.
The study's conclusion that "almost all knowledge in LLMs is learned during pretraining" and that effective model alignment does not necessitate extensive instruction tuning or reinforcement learning from human feedback is both intriguing and promising for creating a data and machine learning strategy that can be accelerated via data privacy.
One of the most compelling takeaways from the LIMA study is its support for the Superficial Alignment Hypothesis, suggesting that alignment is largely about learning the format of interaction rather than acquiring new knowledge. It implies that the essence of aligning LLMs to produce high-quality outputs does not inherently require massive datasets, which often carry the risk of including sensitive or personal information.
By leveraging a mere 1,000 fine-tuning examples, LIMA achieved performances that were "either equivalent to or strictly preferred over GPT-4 in 43% of cases." This efficiency not only speaks to the power of well-designed pretraining but also to the potential of minimizing the privacy risks associated with training data.
The success of LIMA with minimal data aligns perfectly with the use of synthetic data and differential privacy. Synthetic data, generated to mimic real datasets but without containing any actual user information, offers a path to training powerful models while sidestepping the pitfalls of data privacy infringement.
The use of synthetic data, in light of the LIMA study's conclusions, represents a significant step forward in risk mitigation from anonymous data. While anonymization seeks to strip data of personally identifiable information, it is not foolproof. The risk of re-identification persists, especially with large datasets and sophisticated de-anonymization techniques which can further be mitigated by leveraging differentially private guaranties of privacy. However, by minimizing the volume of data needed for effective training, as LIMA suggests, and supplementing this with synthetic data and differential privacy, we drastically reduce the avenues through which privacy breaches might occur.
The LIMA study contributes to our understanding of how LLMs learn and align and also paves the way for a more data privacy-conscious approach to AI development.
Demonstrating that "massive instruction tuning and RL from human feedback are not as crucial as previously thought," it invites us to reconsider our reliance on extensive real-world data, steering us towards a future where data privacy and AI innovation go hand in hand.
First of all thank you @Visa and @SecuritiAI for inviting me to speak on your respective panels at @PrivacyPros yesterday, it was amazing to see the level of engagement into all of the issues I personally find fascinating.
Apologies in advance to the folks who I didn’t get to elaborate on my answers because I had to rush from one talk to another but I mentioned I would follow up and summarize some of those answers here, and be on the look out for my white paper on the topic later this year.
Here’s the follow up on LinkedIn:
https://t.co/rjyemMEl94
And on medium: https://t.co/qJXYwsJSeS
It’s always fun when extremely talented engineers bring up the topic of continuing down an individual contributor path versus entering formally into people leadership.
I recently had the chance to talk about the usual trade-offs in conversations about people leadership vs individual contributions. Topics like, do you think you can effectively lead through others, or you’re a brilliant engineer are you sure you want to manage people instead of doubling down on your expertise?
Naturally, The conversation generally shifts to an equally fascinating topic: quantifying effectiveness. For individual contributors, effectiveness can be measured in various ways, such as algorithmic efficiency or the robustness of systems and platforms they develop.
In contrast, measuring performance and effectiveness in leadership introduces a different kind of subjectivity. It tends to lead into an opportunity where I quote from a concept from my favorite leadership book (at this point I should use an Amazon federal link, hah), that followership is a useful measure of leadership effectiveness because it’s both simple and quantifiable.
Consider this: how many people you lead would choose to follow you if you switched teams, organizations, or even companies? This question underpins the argument in Nine Lies About Work, where the author challenges the conventional wisdom of universally definable and measurable leadership. Instead, the book suggests that “followership” is the real measure of leadership effectiveness, proposing that the essence of leadership is not a singular trait or capability.
Coincidentally, our friends at Quotient recently analyzed a Microsoft study that offers complementary insights, identifying key attributes of effective engineering managers from both managers’ and engineers’ perspectives. These attributes include fostering a positive work environment, enabling autonomy, and nurturing talent. Notably, the study suggests de-emphasizing technical expertise in favor of qualities that promote team cohesion, psychological safety, and personal growth, reflecting a shift in how leadership effectiveness is perceived in the technical domain.
However, I have reservations about the interpretations presented in the Microsoft research paper, especially the assertion that effective managers place less emphasis on technical leadership. This discrepancy might stem from the definition of ‘technical’ prowess, particularly within software and machine learning engineering.
From my experience, there’s a correlation between effective leadership and technical acumen. However, I’d reinterpret ‘technical’ abilities to include the capacity to engage in multiple “languages of abstraction.”
Exceptional leadership, especially in technical disciplines, involves the versatility to engage scientifically with data and empirical evidence, mathematically to argue points with precision, and logically to construct cogent arguments by effortlessly forming valid arguments (any casual reference to using modus ponens or hypothetical syllogism is a win). This abstract multi-lingual fluency enables leaders to connect with their teams on multiple intellectual levels, fostering a deeper appreciation for the leader’s technical capabilities.
I think effective leadership within most engineering domains, hinges as much on technical fluency as it does on vision, empathy, and adaptability. It’s this synthesis of skills and the ability to create an environment where folk would happily follow — that distinguishes truly effective leaders.
I was recently asked about my thoughts on performance management and to share the resources I find helpful. So, as we wrap up another performance management (PM) season, I'd like to reiterate what I've mentioned privately: it’s crucial to reflect on the inherent shortcomings of most PM processes, especially as they pertain to engineering culture. The key point is the importance of acknowledging and embracing the subjectivity at the heart of performance management.
One of the most compelling arguments comes from "Nine Lies About Work" by Marcus Buckingham and Ashley Goodall. They assert, "People can reliably rate their own experience" but are notably unreliable at rating others. They explain, "Your rating of a team member on something called 'performance' is unreliable because your definition of performance is unique to you" (Buckingham & Goodall, 2019). This challenges traditional, often rigid, performance evaluation models and suggests a more introspective approach.
Similarly, "No Rules Rules" by Reed Hastings and Erin Meyer presents the intriguing concept of "The Keeper Test." It's a straightforward yet powerful tool: "If a person on your team were to quit tomorrow, would you try to change their mind? Or would you accept their resignation, perhaps with a little relief? If the latter, you should give them a severance package now, and look for a star, someone you would fight to keep" (Hastings & Meyer, 2020). This approach simplifies performance assessment to a singular, yet profound question, focusing on the real value an individual brings to the team.
"Working Backwards" by Colin Bryar and Bill Carr, though not directly addressing PM, offers valuable insights into creating environments where performance is naturally high. Amazon’s emphasis on clarity, autonomy, and direct, candid communication is a testament to creating a culture where high performance is a byproduct of the work environment itself.
In most large corporate settings managing low performance consumes disproportionate time, energy, and resources. The goal should be to cultivate high-performing teams where excellence is the norm, not the exception.
As @getquotient's Research-Driven Engineering Leadership blog aptly notes, measuring engineering productivity requires a nuanced understanding of what performance means in a technical and creative domain (RDEL, 2022).
In conclusion, embracing the subjectivity of performance management can lead to more genuine, effective, and meaningful assessments. By focusing on individual experiences, aligning personal goals with team missions, and empowering team members with context and autonomy, organizations can create a dynamic, responsive, and ultimately more effective approach to managing performance.
4️⃣ @yawetse
Startup Growth Sectors: Biotech, Machine Learning, Automation.
Challenges & Opportunities: Developing & implementing a robust data strategy for competitive edge through enhanced decision-making, navigation evolving data privacy regulations.
AI & Data Analytics for Startups: Pivotal, particularly in biotech, where they’re revolutionizing genomics & multiomics.
Favorite Investments: @YemaachiBio, @finley_cms, @voxraygames.
Standout Investment: @YemaachiBio's pioneering work in understanding the African genome. Is crucial for global health research & cancer genomics.
Tesla VS BYD
Is it possible to compare these two companies?
We make it a Try...
Manufacturing:
Tesla - Cars, Batteries, electric engine, Superchargers, Solar, AI, FSD, Robots, Trucks, PickUp, Energy storage, Software, and a lot of products inside a car, and a
BYD - Batteries, Cars, Hybrids, Busses, Trucks, engines, smartphones
has traditionally high labour intence factories and cheap labour - Tesla has mainly the opposite.
Revenue 2023:
Tesla: ~$97B
BYD: ~ $85B
BYD is big, but have little to no software capability, so when Tesla hit their OTA with FSD, there would be not so big difference.
Net Profit 2023:
Tesla: ~$9.5B (9.7%)
BYD: ~$3.5B (4.1%)
Employees 2023:
Tesla: ~140.000
BYD: ~631.500
BYD has many manually workers and things that robots do at Tesla, does workers do at BYD, due to low workers cost.
Factories 2023:
Tesla 8 (7 outside China)
BYD 30 (8 outside China)
Total vehicles made 2023:
Tesla: ~1,800,000
BYD: ~3,020,000 (1,570,000 BEV)
Revenue / Employee:
Tesla: $692,857
BYD: $134,600
Profit / Employee:
Tesla: $67,857
BYD: $5,542
Vehicle / Employee:
Tesla: 12.86
BYD: 5.03
ASP 2023:
Tesla: $45,600
BYD: $24,200
I know I can´t compare all this numbers straight off, but I did it anyway.
These are two really different companies
BYD doesn´t even belive in Self Driving Capability in the near term.
Tesla work hard to make it happen.
BYD sells most small to medium cars with low standard and bad safety features in China
BYD has most of their sales in China.
They have tried to sell a few vehicles in Europe with mixed results. In EU15 countries they have 0.8% sales in 2023 (13,816 cars out of 1,811,439)
IF BYD ever going to hit EU or US they need to sell better cars than in China, and they are trying to, but...
And one last thing...
If you have started to manufacturing in China with cheap labour and are used to that, how do you change that to robots and high manufacturing cost.
That´s their biggest issue to sell in bigger numbers outside of China, if they not going to export 95% of their cars from China of course.
However, both companies are accelerating the transition to sustainable transport and that is good, so I hope more companies will try to compete with these two BEV manufacturers!
And yet you’ve never gotten in a crash — because human intervention is a normal part of using ADAS.
The data doesn’t lie. People crash more than twice as often driving Teslas without FSD compared to with FSD. The average car in the US crashes 5 times more often.
Why?
1. FSD requires driver attention and enforces. No phone use allowed. With manual driving, people are quite often distracted or on the phone. This kills people daily.
2. FSD also requires seat belt use unlike manual driving, reducing injuries.
3. Human drivers are often impulsive. They make rash moves, like sudden lane changes or speeding up for a yellow light. When FSD sees a yellow light it can’t make it slows down. Software makes safer choices than humans.
4. FSD can see in all directions, often catching things the human driver may have missed
5. FSD provides advanced active safety features that work even when driving manually. For example, automatic emergency braking was recently updated to detect general obstacles from FSD’s occupancy network.
Shame on those who campaign against life saving safety tech just because they disagree with Elon on politics. I have never seen an example of a team like Tesla doing so much good, saving cars and pedestrians from getting hit on a daily basis, and just get shit on constantly from people who can’t acknowledge that there are people alive today who wouldn’t be if not for this technology.
If you don’t feel that you can intervene when needed, don’t turn FSD on. Simple as that. Reality is the number of corrections needed are dropping like a rock.
This year's recipient of MHS Educator of the Year Award is Social Studies teacher, Mr. Milich! In and out of the classroom, Mr. Milich embodies the idea that it only takes one adult to change the life of a child. Thank you for being that one adult for so many!
@FootballMonty