Misal kardeşim. Üniversiteyi okumak istemedi. Fakat biz zorla okuttuk. Mezun olduktan sonra neden zorla üniversite okuttuğumuz konusunda bize kızdı 😅 pek de bir başarı göstermedi her istenmeyen iste olduğu gibi.
Haklıydı. Okumaması gereken insanı okutmayacaksın. Çalışacak. 🤷♂️
Daron Acemoğlu:
"Herkesi üniversiteye göndermek doğru değildir. Bir elektrikçinin gidip 4 sene üniversitede Shakespeare okuması mı lazım?
Eğitimin daha meslek üzerine olması daha etkili olabilir. Üniversite diploması toplumsal statünün ana ölçüsü olmamalı." (OksijenTV)
Jev (@typesafeai) is so insane & cheap for search!!
> 6000+ @ycombinator Startups indexed.
> Sub 1 second search results.
> 90M tokens & $2.7 in total testing costs.
Search any startup in a second, in any way!
- Color - Niche - Your Competitor - Age - Image - etc...
> watch the entire video, it's so freaking cool omg!
> this is the coolest thing i have ever built for fun! (worked on it for 2 days straight!)
One of the greatest viruses of the modern man is looking at Instagram Stories. You will melt your brain looking at a barrage of outcomes—like vacations, parties, cars—with no visibility of the process that got them there.
@engintezcan veya varlığı Apple kendi stratejisi ve standardı ile yorumlamaları kısmen zoruna gidiyor bu markaların. Çünkü Apple gibi marka değeri yaratamıyorlar. Ama bahsettiğim gibi sanki hassas bir denge var. Amaçları Apple gibi high level bir standarda sahip olmak değil.
ChatGPT retrieval system LEAK alert 💥
I found "something huge" in ChatGPT's server-sent events over the weekend.
Inside the stream is a detailed debug view of ChatGPT's web retrieval system. Which queries it wrote, which engines it called, what came back, scoring objects,what it fetched, how it split each page, and what finally made it into the answer.
I have been pulling this data for a few days. On Saturday I started getting rate limits, so I was probably the most active user of that stream this weekend :)
A few things I can share today:
One question is never one search. Yes, we know there are fanouts. But actually more fanouts behind the scenes!
For a single "best AI visibility tools" prompt, ChatGPT ran 5 search rounds, wrote 18 different queries(hidden queries), made 50 engine calls, pulled 228 results, fetched 223 URLs with selected chunks, and cited 16. You see 16 links.
✍ Let's start today with renderer. How actually ChatGPT uses your page for retrieval.
Your meta tags travel with every result.
There is a separate og_data object in the payload and it is empty on every single result. The raw meta_tags list is what is actually kept.
The page body is not HTML. It is a markdown-like text render. I compared its fingerprints against the common HTML to text parsers. Two-space "* bullet", "* * " for horizontal rules, "# heading" and "--- | ---" table separators with no outer pipes all match the Python html2text library. Turndown, markdownify and Trafilatura each match only one or two of those. So html2text is the strongest candidate, but it is not a stock build.
That render is what gets cut into blocks of roughly 170 words and scored. The model does not see your full page. It sees one to three of those blocks per source.
The images below is not a mockup. Every code block is copied from the stream as is, including our own Peec AI product page.
What I showed above is a small slice. One prompt produces a 150,000-line JSON dump, and the two fields in the image are maybe 2 percent of it.
The same stream also carries:
Every rewritten query, and which of roughly ten internal engines each one was sent to (web, news, Wikipedia, Reddit, arXiv, YouTube, PDF and more)
📍 A per-result score, plus a score object that breaks that score into its components
📍 A per-chunk score for every block of every fetched page, and which blocks were kept for the prompt
📍 A should_fetch decision on each result, with crawl date and publication date
📍 A second ranking pass done in the model's reasoning, where domains are re-ordered before the answer is written
📍 The exact prompt the model receives, with the word budget it is given per source
📍Separate result types for shopping and local queries, with their own fields
If you work on GEO or AI visibility, this is the closest look at ChatGPT's retrieval pipeline I have seen. MORE TO COME.
Follow @DavidKonitzny, @TomekRudzki, @MalteLandwehr, there is a lot more coming THIS WEEK.
🆕 SerpApi quietly built its own search index.
Public in alpha since February, now in preview. 3.2B pages, small, no Google or proxies at query time.
Went finally public because its Reddit counterclaim says the Reddit–Google deal blocks it from competing in search
https://t.co/vh6TGPUIWz
Price of info has reevaluated and unfortunately there will be little monopolies who can afford to build sth in the market 😣
Interesting times. #SEO
I’ve learnt that while building a web app getting AIO answers with @dataforseo
Google has masked their linking on SERP. After losing the case against SERPAPI, google has decided to move battle forward with double edged sword :)
Yo have to deal a hard way to get infos from SERP.
Well done! That is a bold statement as founder of @ahrefs 🙏
There is not prompt volume or search volume. Because prompting is like fingerprint, its unique. Everyone prompts differently. Each use case is different, pain points are different.
There is no such thing as "prompt search volume." If you're paying for it, you're wasting your money.
I've actually looked at a bunch of data samples from clickstream providers who track what people type into ChatGPT.
Can you guess what I saw?
Multi-sentence paragraphs spanning multiple topics, dictated rambles with assignments, rather than searches and follow-up questions that make no sense without previous messages.
…and then there’s personalization, which further messes up the input that AI chatbot actually gets.
Bottomline:
Deriving any meaningful “search volumes” out of that mess is no better than guessing.
But is that data even important for tracking your AI visibility?
That’s the question I asked Dan Petrovic @dejanseo on the latest episode of @Ahrefs Podcast. Dan runs the reputable “AI Influence” agency called DEJAN AI and he is one of the most respected (and positively nerdy) figures in SEO, who’s been at the forefront of the industry for more than 15 years.
Here's what else we covered with Dan:
🔸 Why LLMs.txt is mostly pointless.
🔸 Why LLMs reject Reddit content over 90% of the time
🔸 What is “primary bias” and “secondary bias” of AI models
🔸 Which search indexes do ChatGPT, Claude, and Gemini rely on
🔸 The "Trojan horse method" for getting into LLM citations fast.
🔸 How Dan tests on-page changes with an agentic loop
🔸 What to actually track instead of prompt volumes.
🔸 How to generate the right prompts for AI visibility measurement.
Watch full episode here 👇
YouTube: https://t.co/q7CyNE7vT5
(also on Apple podcasts & Spotify)
I am not sure if Cloudflare is helping or hurting the situation either. My client accidentally blocked the website to bots, the site got deindexed. Then rankings dropped dramatically. Both taking security precautions and managing bots behavior all over the website is dangerous
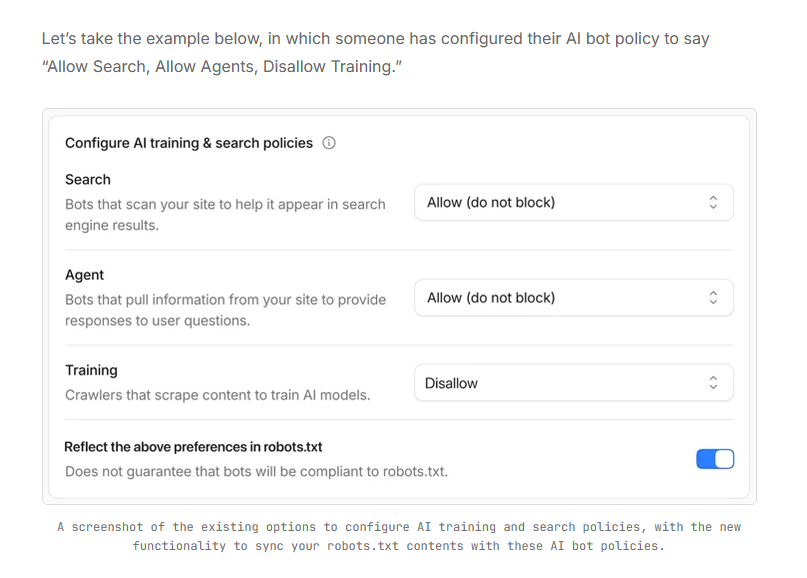
At this point I'm not sure if Cloudflare is helping or hurting the situation. :) I think many site owners will be confused by all of the options -> Cloudflare Introduces Bot Preference Sync
"We're announcing Bot Preference Sync, available to all customers from the Free tier to Enterprise. Bot Preference Sync reflects what you've set in your AI bot configuration by updating corresponding preferences to your robots.txt, and it can be turned on or off at any time. No more static file for one use case: we'll help you tailor your robots.txt to reflect what you’ve already configured for different AI bot categories."
"Bot Preference Sync is a new feature that keeps your robots.txt reflecting the AI bot preferences you've already set for Search, Agent, and Training on the Cloudflare zone-level dashboard. If a site owner already has a robots.txt file, the contents added by Bot Preference Sync will be prepended to the existing material, so any existing Disallow directives are maintained."
https://t.co/1CMuaKm3GJ
looks like reddit is almost wiped from chatgpt sources
the query fanout changes had a big impact
and the past couple of days it seems to be almost completely removed from prompt responses
https://t.co/oCGm9M0yPO