For further results on policy learning, image-based RMs, pluralistic alignment, and using real robot success / failure labels as preference feedback, please check out our paper!
Work done with @ebiyik_
Paper: https://t.co/LbLlWotRFu
Code: https://t.co/weX4Mk4sfC
(7/7)
Active reward learning from preferences means choosing what query to ask, which requires tracking what the reward model (RM) doesn't know.
We introduce PreferenceEKF: an active reward learning method that trains RMs via sequential Bayesian inference. (TMLR 2026)
(1/7)🧵
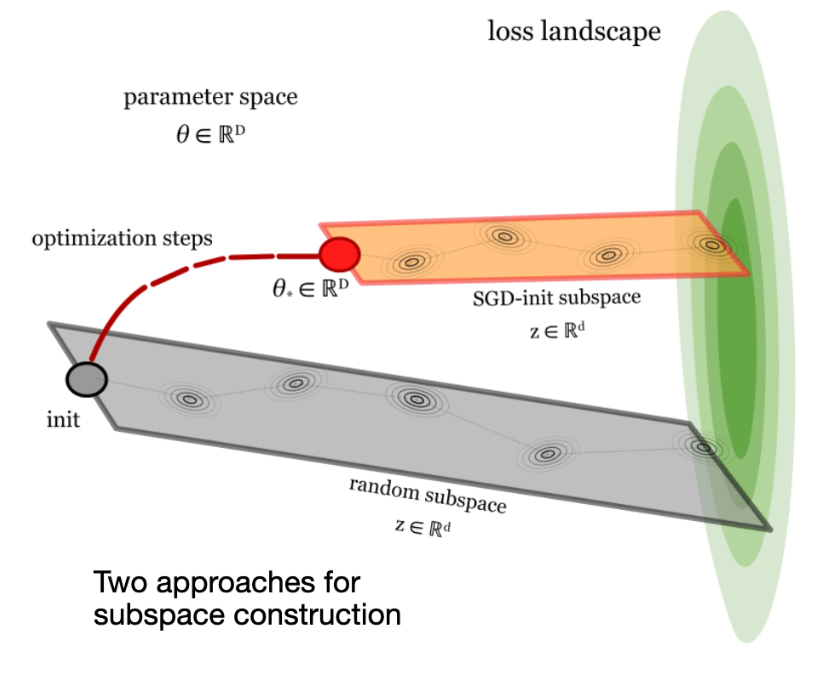
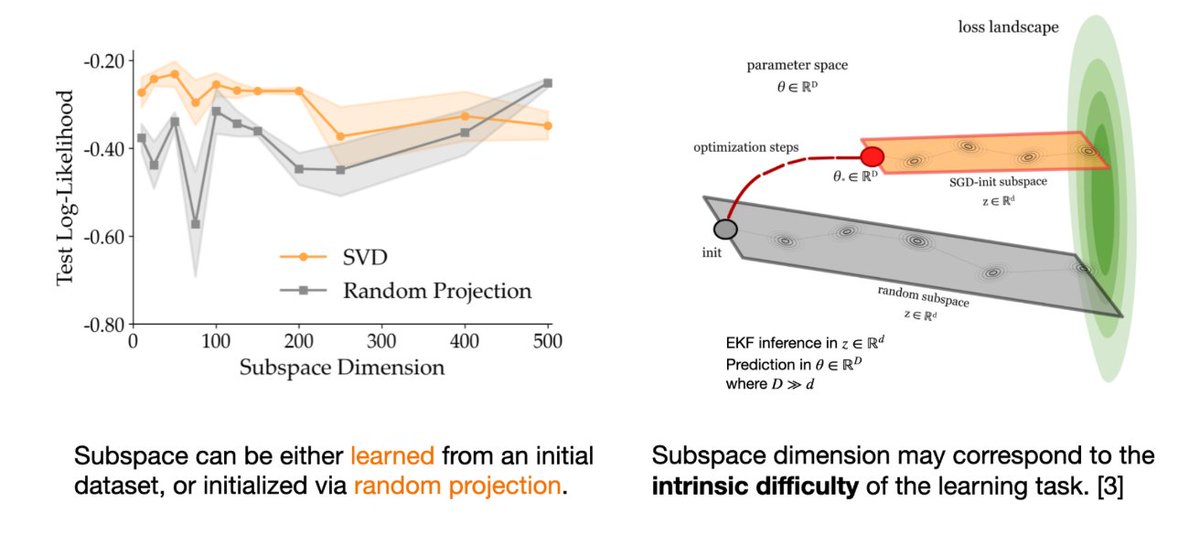
We further show that our subspace inference approach is agnostic to the subspace construction method. While lower-dimensional subspace benefits from learning the subspace, high-dimensional spaces can be randomly generated and still lead to good active learning results!
(6/7)
Doing proper science in robotics is hard, because human demonstrations are expensive and less controllable.
OCBench is a new benchmark providing "human-like" scripted policies. This enables scientific studies of BC and RL with virtually unlimited data!
Tired to go back to the original papers again and again? Our monograph: a systematic and fundamental recipe you can rely on!
📘 We’re excited to release 《The Principles of Diffusion Models》— with @DrYangSong, @gimdong58085414, @mittu1204, and @StefanoErmon.
It traces the core ideas that shaped diffusion modeling and explains how today’s models work, why they work, and where they’re heading.
🧵You’ll find the link and a few highlights in the thread.
We’d love to hear your thoughts and join some discussions!
⚡ Stay tuned for our markdown version, where you can drop your comments!
This is an excellent history of LLMs, doesn't miss seminal papers I know. Reminds you we're standing on the shoulders of giants, and giants are still being born today. https://t.co/r4AWWKqMmS
TRI's latest Large Behavior Model (LBM) paper landed on arxiv last night! Check out our project website: https://t.co/AV2cmfeX40
One of our main goals for this paper was to put out a very careful and thorough study on the topic to help people understand the state of the technology, and to share a lot of details for how we're achieving it.
https://t.co/EVFLJAY6Zu
While some of my students were organizing the human-in-the-loop robot learning workshop at RSS 2025, another group won the best paper award at the OOD workshop among ~50 papers with the ReWiND paper 👏🏻 (see the quoted thread for the paper)
We now know RL agents can zero-shot crush driving benchmarks. Can we put them on a car and replace the planning stack? We're hiring a postdoc at NYU to find out!
Email me if interested and please help us get the word out.
Just a small reminder that our workshop is happening tomorrow, and we have an amazing line of speakers! Make sure to check out the workshop website for the schedule. 🤖
It was a dream come true to teach the course I wish existed at the start of my PhD. We built up the algorithmic foundations of modern-day RL, imitation learning, and RLHF, going deeper than the usual "grab bag of tricks". All 25 lectures + 150 pages of notes are now public! 🧵
@ndaheim_ Hi! Out of curiosity, has your team tried using IVON on sequential control tasks such as RL and imitation learning? If I can get, e.g., improved OOD detection and predictive dist, almost for free in interactive decision-making settings, it seems almost too good to be true!