Demystifying the complexities of a Trusted Research Environment (TRE) for the public 🚀 Join Anwar Gariban as he breaks down the intricacies of TREs 📊 🌟 Read the full article here: https://t.co/Y8f0AqdbmF #TRE#DataSecurity#ResearchCollaboration
You’re a Data Scientist facing a new dataset.
After putting on your arm bands, tightening your goggles and checking the water temperature of your data lake, What actions do you take to impress the boss?
#datascience#data#machinelearning#Analytics#bigdata#cat
📢 Health Data Science Summer 2024 Internship Opportunities 📢
👨🔬 🖥 📈 👩🔬 Apply for a summer work placement in health data research at a UK research organisation, with an HDR UK-Wellcome Biomedical Vacation Scholarship.
Link in Comments.
#DataScience#Internship
We are delighted to announce that we are one of four sites to awarded funding in the new UK Research and Innovation (UKRI) Population Health Improvement UK initiative!
Find out more: https://t.co/RzWXwxM32g
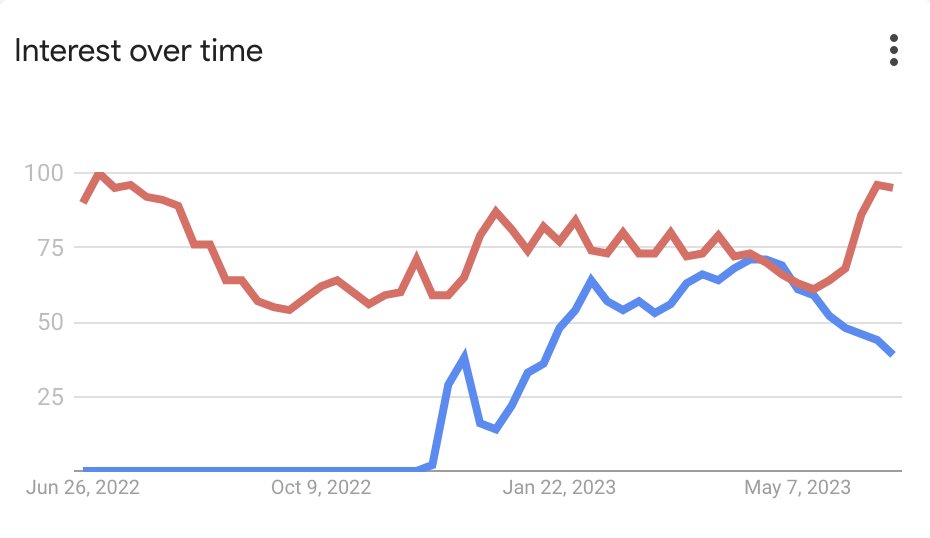
Search interest over time, ChatGPT (blue) vs Minecraft (red).
There's an obvious factor that might well underlie both trends (down for ChatGPT, up for Minecraft). Can you guess what it is?
As it happens, the answer matters for both the future of AI and the future of education.
New book out today by Me, Prof Kieran McCartan (@kieranmc80) Abby Gilsenan (@GilsenanAbby) Amy Adams (@Amy_Welshman) & Jonathan Beavis on 'Understanding & Responding to Sibling Sexual Abuse'
@_HSMCentre@UoBSocialPolicy @CoSS_Birmingham
https://t.co/QoxX32abGe
📚 Call for Papers 📚
The SACRO driver project team is working on a literature review focusing on public engagement around disclosure controls. They're seeking articles, journal papers, and work reports related to this topic, including wider related subjects.
#DAREUK
1/2
Oops haven't tweeted too much recently; I'm mostly watching with interest the open source LLM ecosystem experiencing early signs of a cambrian explosion. Roughly speaking the story as of now:
1. Pretraining LLM base models remains very expensive. Think: supercomputer + months.
2. But finetuning LLMs is turning out to be very cheap and effective due to recent PEFT (parameter efficient training) techniques that work surprisingly well, e.g. LoRA / LLaMA-Adapter, and other awesome work, e.g. low precision as in bitsandbytes library. Think: few GPUs + day, even for very large models.
3. Therefore, the cambrian explosion, which requires wide reach and a lot of experimentation, is quite tractable due to (2), but only conditioned on (1).
4. The de facto OG release of (1) was Facebook's sorry Meta's LLaMA release - a very well executed high quality series of models from 7B all the way to 65B, trained nice and long, correctly ignoring the "Chinchilla trap". But LLaMA weights are research-only, been locked down behind forms, but have also awkwardly leaked all over the place... it's a bit messy.
5. In absence of an available and permissive (1), (2) cannot fully proceed. So there are a number of efforts on (1), under the banner "LLaMA but actually open", with e.g. current models from @togethercompute, @MosaicML ~matching the performance of the smallest (7B) LLaMA model, and @AiEleuther , @StabilityAI nearby.
For now, things are moving along (e.g. see the 10 chat finetuned models released last ~week, and projects like llama.cpp and friends) but a bit awkwardly due to LLaMA weights being open but not really but still. And most interestingly, a lot of questions of intuition remain to be resolved, e.g. especially around how well finetuned model work in practice, even at smaller scales.
📢 Introducing MPT: a new family of open-source commercially usable LLMs from @MosaicML. Trained on 1T tokens of text+code, MPT models match and - in many ways - surpass LLaMa-7B. This release includes 4 models: MPT-Base, Instruct, Chat, & StoryWriter (🧵)
https://t.co/Zg7PcrQvOi
The first RedPajama models are here! The 3B and 7B models are now available under Apache 2.0 license, including instruction-tuned and chat versions!
This project demonstrates the power of the open-source AI community with many contributors ... 🧵 https://t.co/msO4afBQEK
@owainkenway Unless it’s a discussion point around the amount of lost gaming hours due to the massive analysis that was undertaken, then I feel we need to know.