Hi Zarrites! 👋🏻
We have our bi-weekly community meeting today. 🗓️
These meetings are a great place to share updates, showcase your projects, raise an issue, or converse with the vibrant community. 🧑🏻💻
Join here: https://t.co/sJ3rsM9o2P
3/ 𝐅𝐥𝐮𝐱 𝐜𝐡𝐚𝐧𝐠𝐞𝐬 𝐭𝐡𝐚𝐭.
Flux is a plug-and-play solution for serving @zarr_dev data directly from object storage—no bespoke APIs, no server maintenance. Just standard-compliant, production-grade endpoints your tools already know how to use.
Very happy to announce our winter release of @syGlassVR: 2.2.0!
Now control syGlass with your voice! We've also enhanced auto-segmentation, mask handling, and supercharged our narration system. We've also included some basic support for @zarr_dev.
https://t.co/2cZyWQHFVN
🎉 Zarr-Python 3 is here! 🎉
- Full support for Zarr v3 spec
- Chunk-sharding for more efficient data storage
- Major performance boosts with async I/O & parallel compression
💻 pip install --upgrade zarr
Blog post: https://t.co/0pCdmjFQAX
Hi, Zarr community! 👋
🚨 Big news: Zarr-Python 3.0 is dropping next week! 🚨
If your project depends on Zarr-Python, make sure to check out the migration guide to get ready for the update.
Guide: https://t.co/JYbxeAsZt4
More updates soon! 🧑🏻💻
Hi Zarrites! 👋🏻
We have our bi-weekly community meeting today. 🗓️
These meetings are a great place to share updates, showcase your projects, raise an issue, or converse with the vibrant community. 🧑🏻💻
Join here: https://t.co/sJ3rsM9VSn
Also on Thursday, I'll be giving an invited talk titled "Seamless Arrays: A Full Stack, Cloud-Native Architecture for Fast, Scalable Data Access". It combines all that we've been working on for the past year including @zarr_dev v3, #icechunk, and Xpublish.
https://t.co/synDa6b7zu
Hi Zarrites! 👋🏻
We have our bi-weekly community meeting today. 🗓️
These meetings are a great place to share updates, showcase your projects, raise an issue, or converse with the vibrant community. 🧑🏻💻
Join here: https://t.co/sJ3rsM9VSn
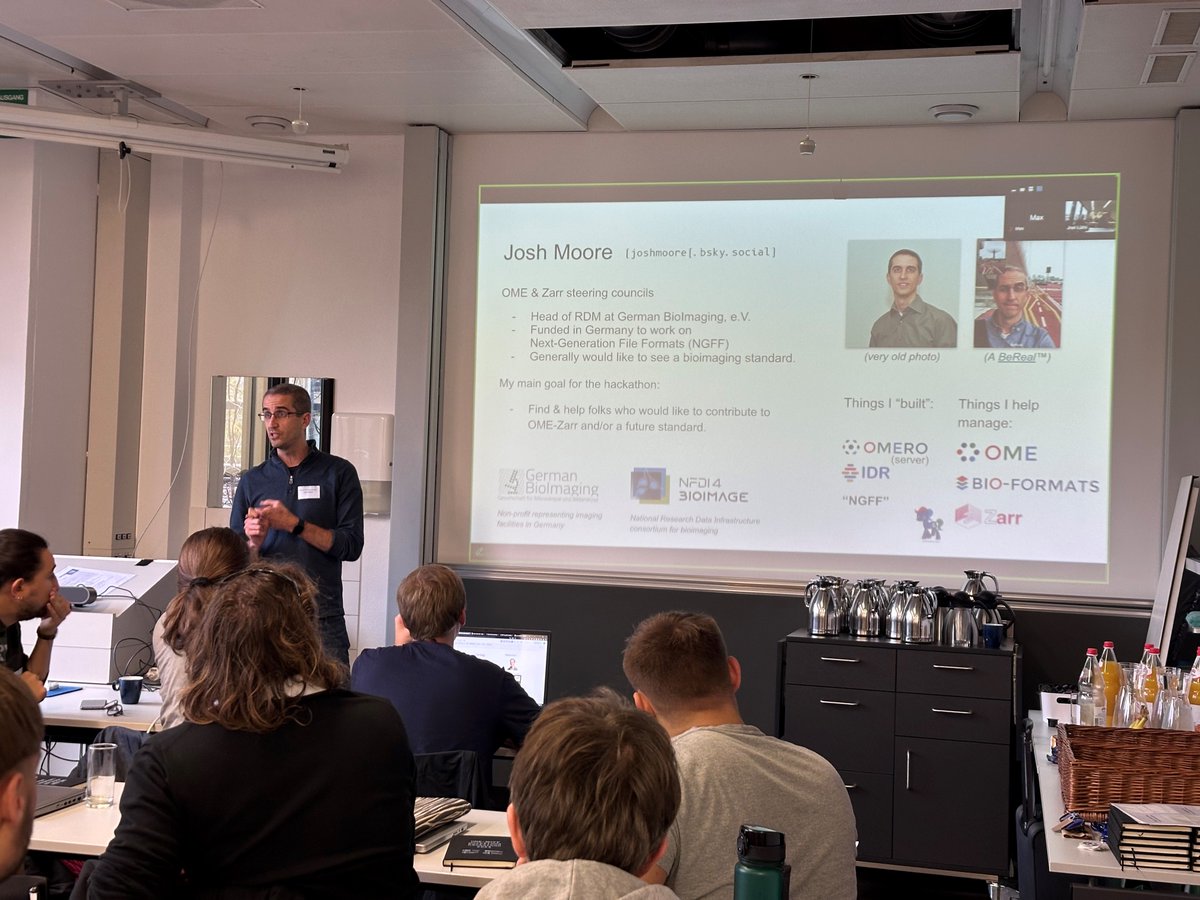
Kicking off the OME-NGFF #hackathon 2024 @UZH_en today! 🚀 With funding kindly provided by @NFDI4BIOIMAGE, we are bringing together experts on #OME#Zarr in Python, Java & image analysis workflows. Follow for updates on the future of a #FAIR bioimaging standard.
In their Perspective article, @VirginieUhlmann, Matthew Hartley, @notjustmoore, Erin Weisbart and @AssafZaritsky tell us how we can make the most out bioimage data through interdisciplinary interactions.
https://t.co/RqzRlvZn6z
#JCSImagingSI
Hi Zarrites! 👋🏻
We have our bi-weekly community meeting today. 🗓️
These meetings are a great place to share updates, showcase your projects, raise an issue, or converse with the vibrant community. 🧑🏻💻
Join here: https://t.co/sJ3rsM9VSn
#30DayMapChallenge Day 6: Rasters
Opinionated metrics on where's good to live, based on a year or two of @ECMWF ERA5 data. Built a lib called zarr-gl to make this work, maybe a useful step getting @zarr_dev into everyone's browsers. Check it out: https://t.co/hWok4yriYB
Very proud to announce Dataset v2.0! ✨
When we first set out to build a universal data format, I wasn't sure if it would ever work. Work to be done, but by building on top of @zarr_dev we're standing on the shoulders of giants.
Come build with us! 🧑💻
https://t.co/AAL7tDe1Sf
Hi Zarrites! 👋🏻
☁️ Looking for a reliable cloud-based data storage format? ☁️
🛠️ Interested in how Zarr works? 🛠️
If you have more questions, please join us during Zarr's office hours today! 🧑🏻💻
More info: https://t.co/RDoQQmxrxl
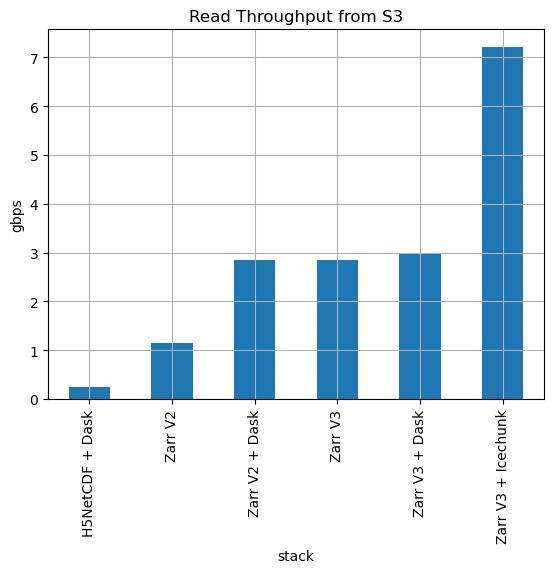
⚡️ Icechunk is fast! What does this mean for users? Reduced cost for all data-intensive compute jobs and enhanced productivity for the data scientists who work with data all day long.
Icechunk, @EarthmoverHQ's new transactional cloud-native storage engine for array / tensor data, works together with @zarr_dev , augmenting the Zarr core data model with features that enhance performance, collaboration, and safety in a multi-user cloud-computing context.
Reading data through Icechunk is 36x faster than trying to read HDF5 files from cloud object storage, 6x faster than regular Zarr alone, and 2.5x faster than regular Zarr + Dask. Most importantly, Icechunk can achieve throughput on par with the compute instance network bandwidth, the "hardware limit" for I/O bound workloads.
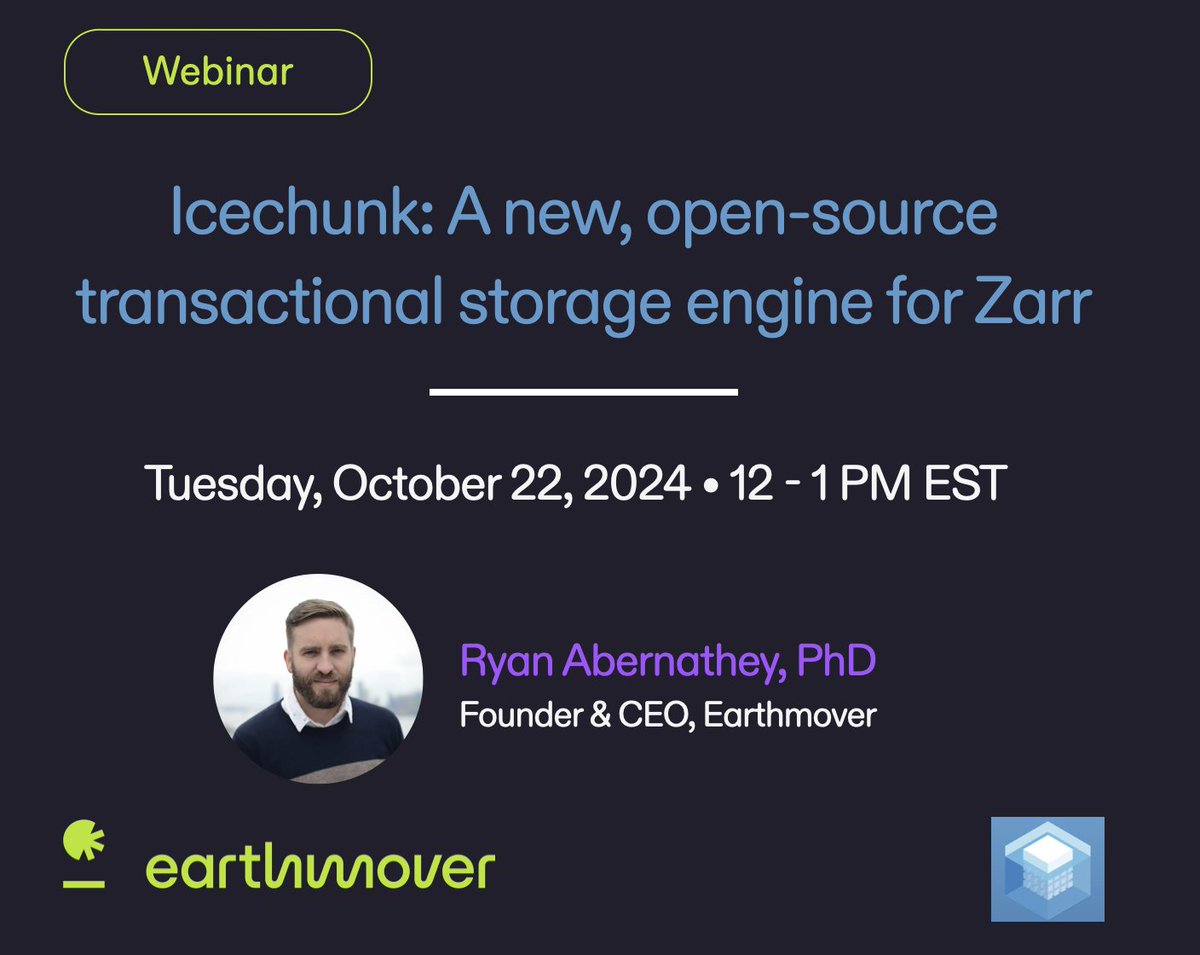
Want to learn more about this benchmark? Come to our Icechunk informational webinar tomorrow, Tuesday, October 22nd from 12 - 1 PM EST. Registration link: https://t.co/dohoeplayZ
We’re hosting a webinar on Tuesday, October 22 from 12- 1 PM EST to discuss what Icechunk means for the scientific data community and answer questions from attendees. Register here: https://t.co/mGrYyqOvEU
Hi Zarrites! 👋🏻
We have our bi-weekly ZEP meeting today at 9:00 PT. 🗓️
ZEP meetings hold discussions for the Zarr specification and ways to evolve it, ongoing ZEPs, and improving the overall process. 🧑🏻💻
Join here: https://t.co/P6jQ2YlmQ6