SpaceXAI engineer, Lauren Tan:
"I shipped 1000 PRs last month. I'm at almost 800 already this month and we're on the 12th
I woke up today and 20 had already landed. I reviewed them on main, after the fact"
In a 1-hour session she walks the exact trust curve, from micromanaging one agent to auto-merging thousands of PRs a month
this is worth more than any $500 agentic engineering course
watch it today, then read how to build the same agent fleet in the article below ↓
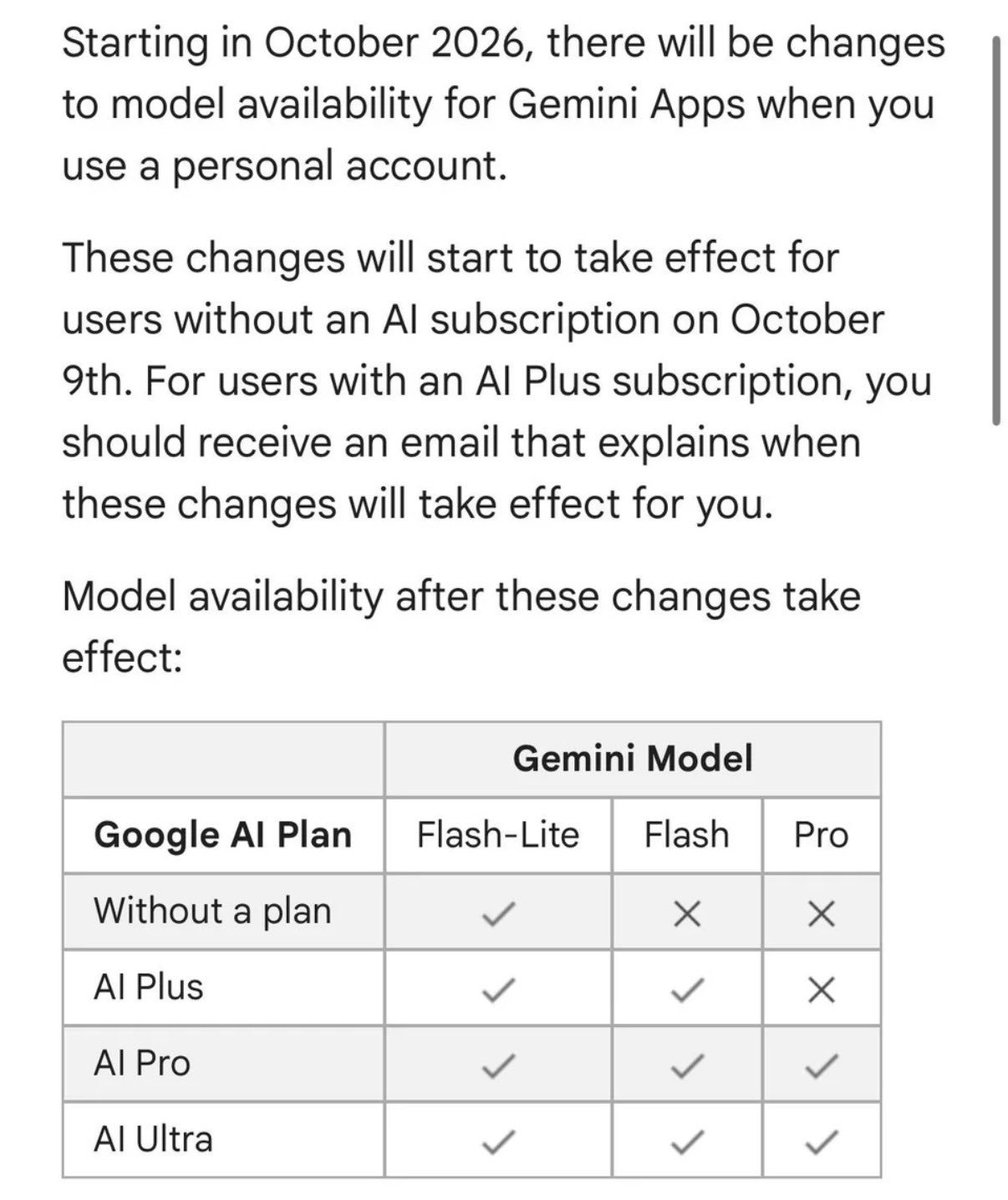
Google is changing Gemini model access starting Oct 9:
• Free → Flash-Lite only
• AI Plus → loses Pro models, Flash only
• AI Pro & Ultra → retain access to Pro models
A few of you asked what mods are, here's a quick walkthrough! They’re really just plugins with a few special functions that let your code run inside Claude Code, like middleware.
(don't worry, you can just ask Claude to write them for you 😛)
dot is my favorite openai product so far!
it is amazing to me that each day it feels noticably better as it learns more of my workflow and style.
having it do the stuff i don't like doing--and usually just builds up as a gravity well of dread--has me very happy.
Global reset landing tomorrow 10am PST for all paid ChatGPT accounts. Apologies for the slow start with GPT-6.1 Sol, it's now back to running at expected speeds after the massive load spike in the first two days.
We'll be spending a lot more time trying to understand the outputs of language models. A few thoughts, tips & tricks:
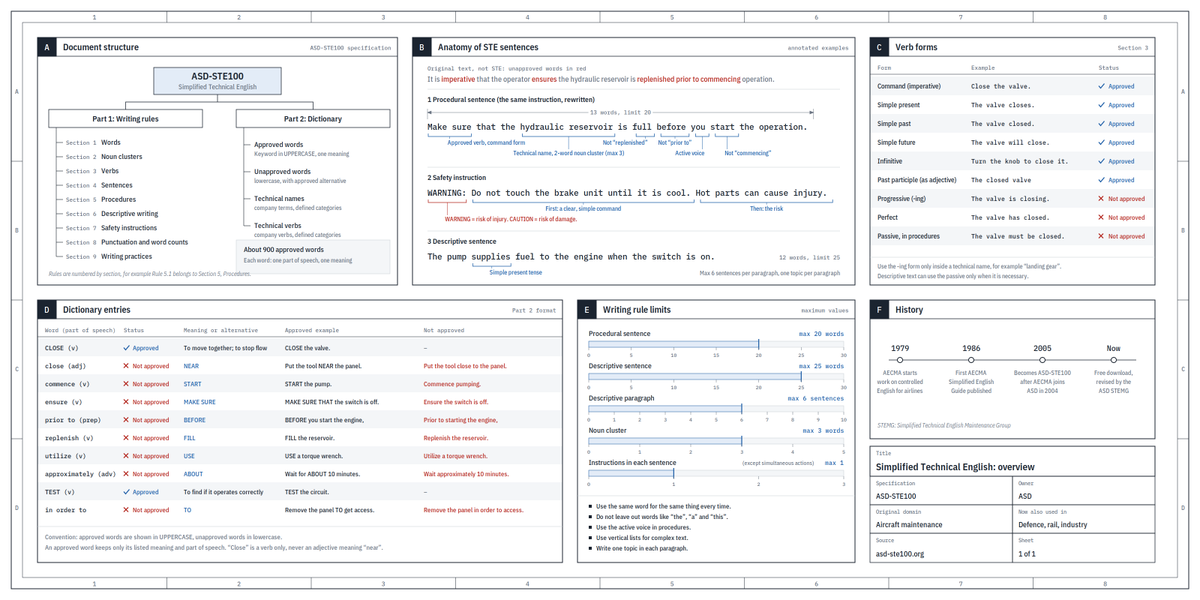
Writing. Something I've had success with: Ask your LLM to explain something in ASD-STE100, it's a controlled language specification originally developed for aerospace maintenance documentation. LLMs well-versed in this language and it comes with heavy constraints on clean writing style that I often find a lot more readable. Sometimes I've tried to soften it a bit e.g. ask for "80% of the way to ASD-STE100" because the spec is quite stringent. But even better:
Diagrams / images. Instead of writing, ask your LLM to create a diagram. These can be a lot easier to process, parse, and understand. But even better:
Web pages. Ask for output "in HTML" to get a beautiful, interactive webpage. LLMs are getting really good at frontend and can create beautiful experiences, animations, etc. But even better:
Explainer videos. The output format I am most bullish on is fully custom / bespoke explainer videos generated on any arbitrary topic. Experiment with things like "Create a 3b1b style video explainer on X. Use my ElevenLabs API key for audio narration". (you'd need an API key for the latter or you can ask your LLM to find you decent free alternatives that use your local compute). This is actually starting to work!
In summary:
- As LLMs get better, they will do more and more of the legwork autonomously, and a lot more of our work will rise up the abstractions into oversight and understanding.
- Luckily, LLMs can help here too because as intelligence and code are increasingly abundant, you can ask for large, custom, discardable software artifacts (e.g. web apps, video explainers) that would have never made sense to create before. Push the boundaries here and you'll be surprised.
Anthropic senior engineer just shared a 1-hour course on building a team of agents with loops & graphs:
00:27 - claude-md & Plan mode
11:24 - building skills and hooks
37:02 - agents and subagents with Claude
52:47 - self-improving loops and graphs
taught by someone who runs this every day inside Anthropic
Prompts → Agents → Loops → Graphs
a loop closes one job without you
a graph decides which jobs exist and carries every accepted one into the next run
watch it today
then save the full guide on building a team of self-improving agents below before everyone catches up ↓
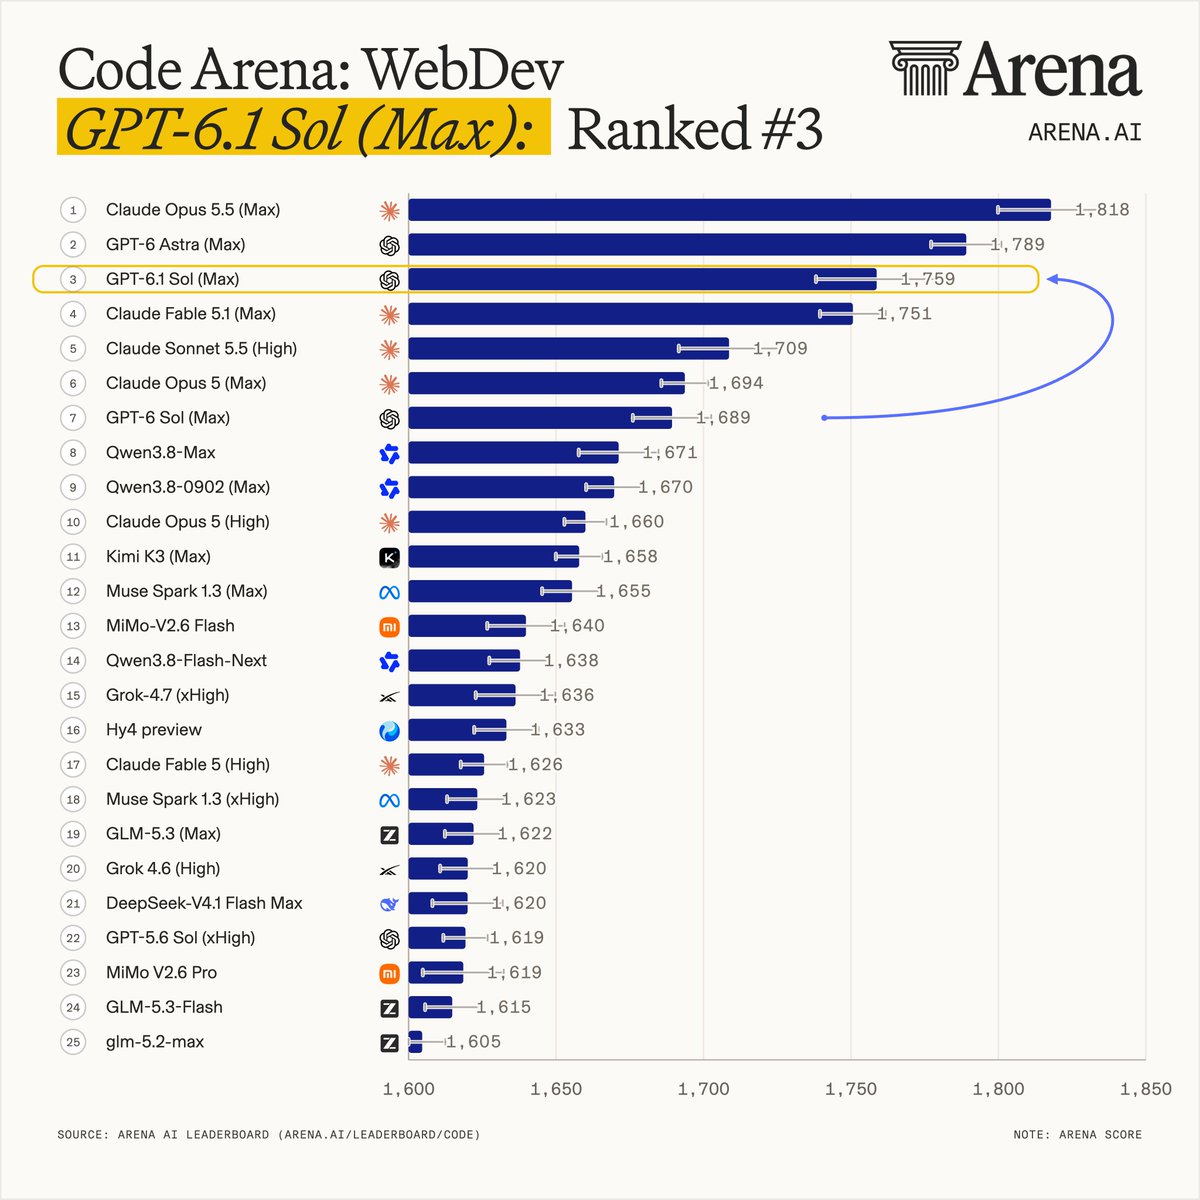
Exciting news: GPT-6.1 Sol (Max) by @OpenAI just landed the Code Arena: WebDev at #3 with 1759 pts, and at a blended $8/MToken it reshapes the Pareto frontier!
GPT-6.1 Sol (Max) marks a clear improvement in cost efficiency: it gained 70 points over GPT-6 Sol (Max) for the same price.
It landed within 30 points of GPT-6 Astra (Max) at 80% lower blended token cost, and 59 points from Claude Opus 5.5 (Max) at 50% of the price. See position on the Pareto frontier for the Code Arena: WebDev in the post below.
Overall, GPT-6.1 Sol improved from GPT-6 Sol by 4 rankings! It also improved in every category:
- Consumer Product: #5 → #1
- Simulations: #6 → #3
- Data & Analytics: #4 → #3
- Content Creation Tools: #4 → #3
- Gaming: #6 → #4
- Reference-Based Design: #6 → #4
- Brand & Marketing: #10 → #6
Congrats to the @OpenAI team on the release!