@LisaSu@AMD Two years ago, AMD gifted me this launch-era Radeon Pro W7900 when I was 19.
This GPU witnessed my growth and my journey into RWKV & ROCm.
Seeing it signed and reposted by Lisa Su truly means a lot to me.
I’ll keep moving forward with this card and continue pushing RWKV further🕊
@cclainstone@AMD Oh that’s awesome 😆 I’d really love to play with this and hack on it with you once the MVP is out. I’m on a Ryzen AI 350 machine, so basically the same XDNA2 NPU core family haha. Really looking forward to your release!🤗
@LisaSu@AMD Two years ago, AMD gifted me this launch-era Radeon Pro W7900 when I was 19.
This GPU witnessed my growth and my journey into RWKV & ROCm.
Seeing it signed and reposted by Lisa Su truly means a lot to me.
I’ll keep moving forward with this card and continue pushing RWKV further🕊
@_m0se_ After a few days, your children will be amazed at the powerful performance of RX6800XT under the AMD open source driver for Linux and the optimization of Steam Proton compatibility layer.😜
The new mechanism in RWKV-8 "Heron" 🪶 is named ROSA (acronym, note SA ≠ Self-Attention here) 🌹 ROSA is compromise-free: we get efficient, scalable, genuine infinite ctx, by applying some beautiful algorithms.
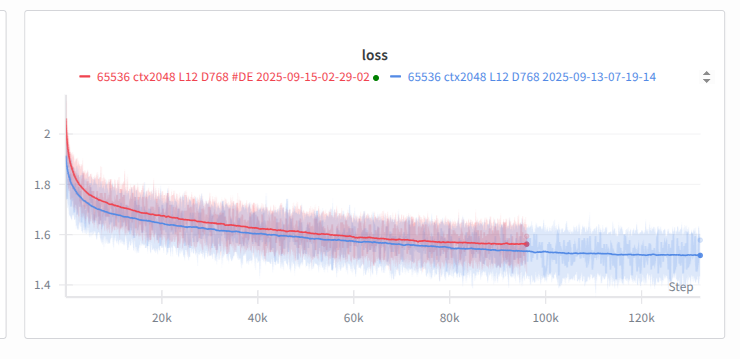
RWKV v7 DE G1 0.1B🪿 & RWKV v7 DEA G1 0.1B🪿🤖 Hybrid Attention models finished training on AMD Instinct MI300X.😎
Loss matches RWKV v7 G1 0.4B, trained on the same datasets.🫢
Performance equals 0.4B.🤯
You can experience on my Hugging Face space :https://t.co/d90ZD63KGM 🕊️
RWKV v7 G1a 0.4B🪿 Translated Dedicated models just finished training on AMD Instinct MI300X. 🕊️
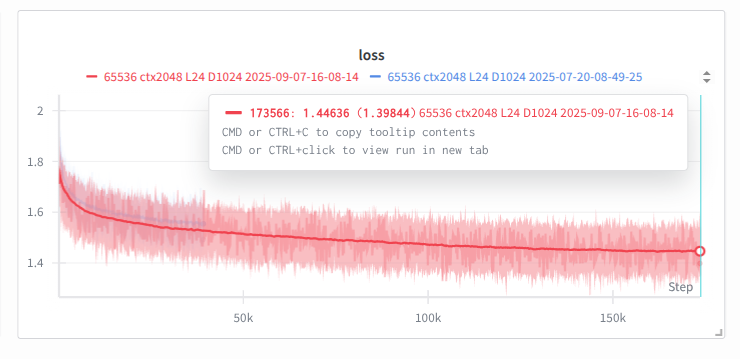
The loss is lower than RWKV v7 G1 0.4B; I trained three times tokens more than before. 🤗
Here is the Hugging Face model repo:https://t.co/Uu9ddL5oHK
RWKV v7 G1a 0.4B🪿Translate Dedicated models achieve *624* batch size with *8400* tokens/s on AMD Radeon RX-6750XT 12G. 🚀
As a pure RNN LLM, the model is trained on AMD Instinct MI300X, supported by AMD Developer Cloud on 🐋DigitalOcean.
@AMD@RWKV_AI@BlinkDL_AI
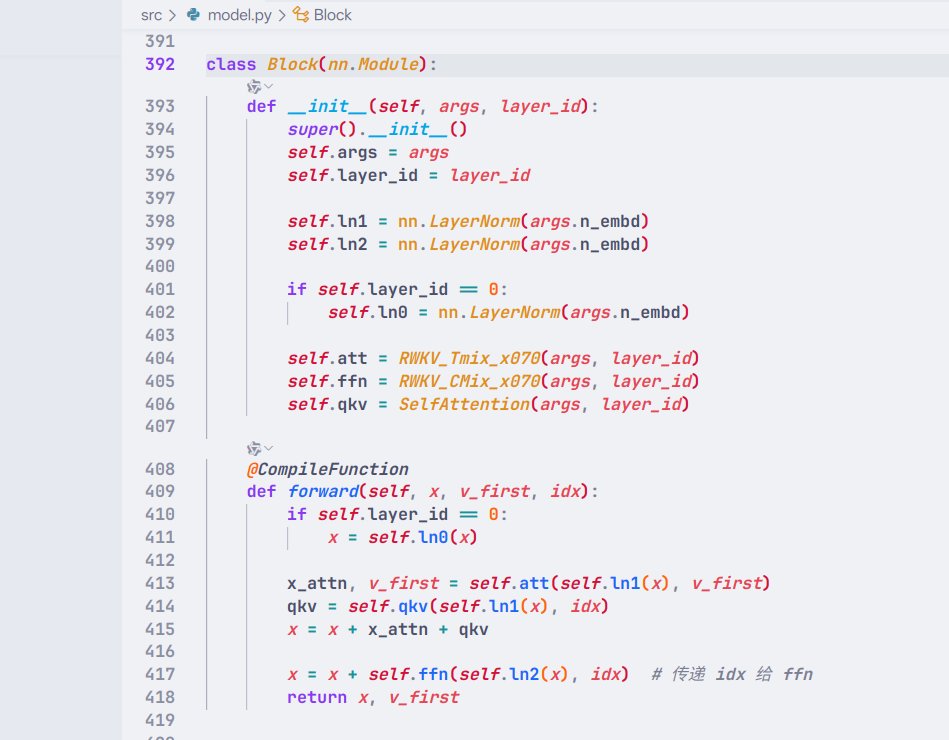
The MiniRWKV_7 with Self-Attention hybrid architecture 0.1B parameter model is under experimentation.🤗
Here is its pre-training loss chart (after numerous failures😢).
I anticipate its performance.😎