@generalsequence - Infrastructure for General Physical AI
Building General Sequences | Master & Undergrad at @Penn | Noe-matrix Robotics| WM Research Fellow
Distributed Cloud Inference is the Future for Physical AI
BENCHMARK results from @generalsequence
Physical-AI models are moving to the cloud: bigger models, more of them, running for real robot deployments. Serving them well turns out to be a distributed-systems problem, not just a modeling one. Here's what the data shows.
Latency is a deadline and we can solve it.
Decompose a single robot-inference call and the model is a small slice: on an open policy like pi0.5-DROID, ~106 ms. A naive cloud path (Runpod, etc.) spends ~1,494 ms per call, dominated by connection setup, observation upload, and routing overhead. Optimize the path and it drops to ~144 ms (a 10.4× reduction, only an additional 38ms) from our networking optimization, which holds across models (pi0.5, Cosmos3-Edge, GR00T, DreamZero). (See Image 1 and Image 2)
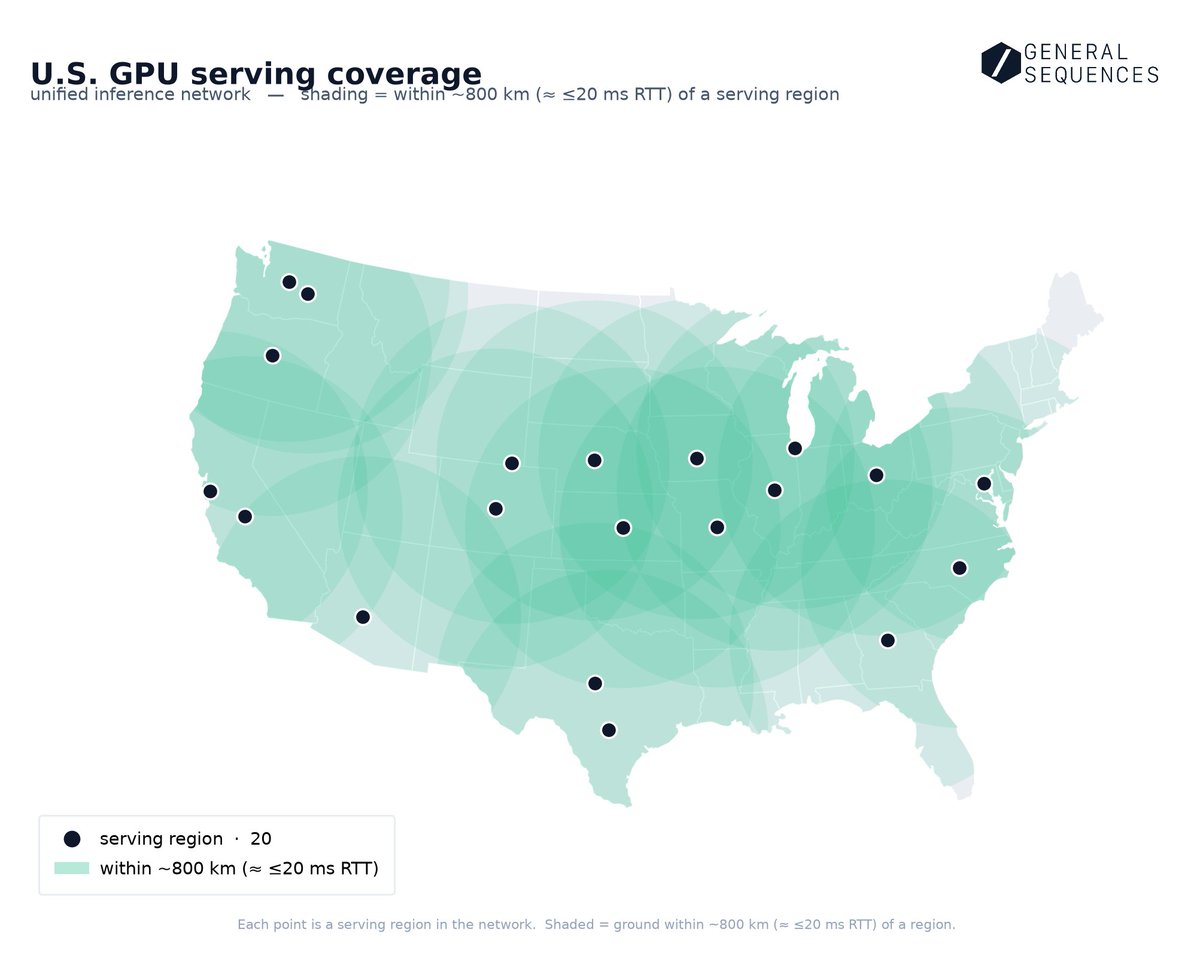
And regional coverage works.
Your customer might carry your robot around the US and things gets unstable. By routing it to the closest data centers with the multiple neocloud providers we support, we provide low latency and reliability on the table. (Image 3)
@generalsequence believe that robotics inference should be distributed, routed across providers to the nearest, warmest GPU, with an optimization layer on top.
This is exactly what we've providing as a platform service. If you're running inference at scale and across the US, contact us.
Shout out to our investor @bcristei from OPTIM VC for making this possible.
Purely atomic task manipulation is one thing. But VLM calling action expert to work is another.
As Open AI and Anthropic brought up the wave of the second approach, there will be more labs publishing how VLMs expand the agentic power to physcial world (Gemini, Llama, Qwen, Kimi, MiniMax etc).
Robot foundation models are getting good.
Running them is still the hard part.
General Sequences is a router HTTPS endpoints for all of it.
Six models. Per-robot-hour pricing. No GPU.
https://t.co/CSLwzedl9T